HiVe-Mem and the Case for Two-Dimensional Agent Memory
A new multimodal memory framework called HiVe-Mem claims a 90 percent token cut by rethinking how agents retrieve past interactions, splitting the problem into broader coverage and query-adaptive evidence rather than flat semantic search.
TL;DR: HiVe-Mem reframes agent memory as two separate jobs, finding the right past episodes and deciding how much detail each one needs, and reports roughly 90 percent fewer tokens than the most efficient multimodal baseline while improving task scores.
The paper is “HiVe-Mem: Interleaving Horizontal Memory Expansion and Vertical Evidence Composition for Multimodal Agents,” posted across arXiv’s cs.AI, cs.CL, and cs.LG listings. The three postings are the same work, so treat the “three sources” here as one paper indexed under three categories, not independent confirmation. No arXiv ID appears in the material I was given, so I am not going to invent one.
Here is the problem it goes after. When a multimodal agent runs for a long time, its history grows: screenshots, captions, prior turns, images. The standard move is to compress all of that into embeddings and do semantic retrieval when a new query comes in. That works until it doesn’t. Two failure modes show up, and HiVe-Mem is built around naming them separately.
Why does flat semantic retrieval fail agents over time?
Semantic search over compressed memory has a coverage problem and a resolution problem, and most systems only treat the first one.
The coverage problem: embedding similarity pulls the obvious matches and misses the ones that are relevant for a non-obvious reason. If you ask an agent about a decision it made three sessions ago, the single closest memory might be the decision itself, but the context that justified it, the thing it saw right before, the follow-up correction, sits in neighboring episodes that score lower on raw similarity. Retrieve only the top hits and you get a thin, sometimes misleading slice.
The resolution problem is the one I think matters more and gets ignored more. Existing systems “expose predefined representations,” in the paper’s words. Meaning: they decide in advance that every retrieved memory comes back as, say, a summary. Or always as a caption. Or always as the raw image. But different queries need different amounts of detail from the same memory. Sometimes a one-line summary is enough. Sometimes you need the actual pixels. Lock the representation in advance and you either overpay tokens by always shipping the heavy version, or you underfit by always shipping the light one.
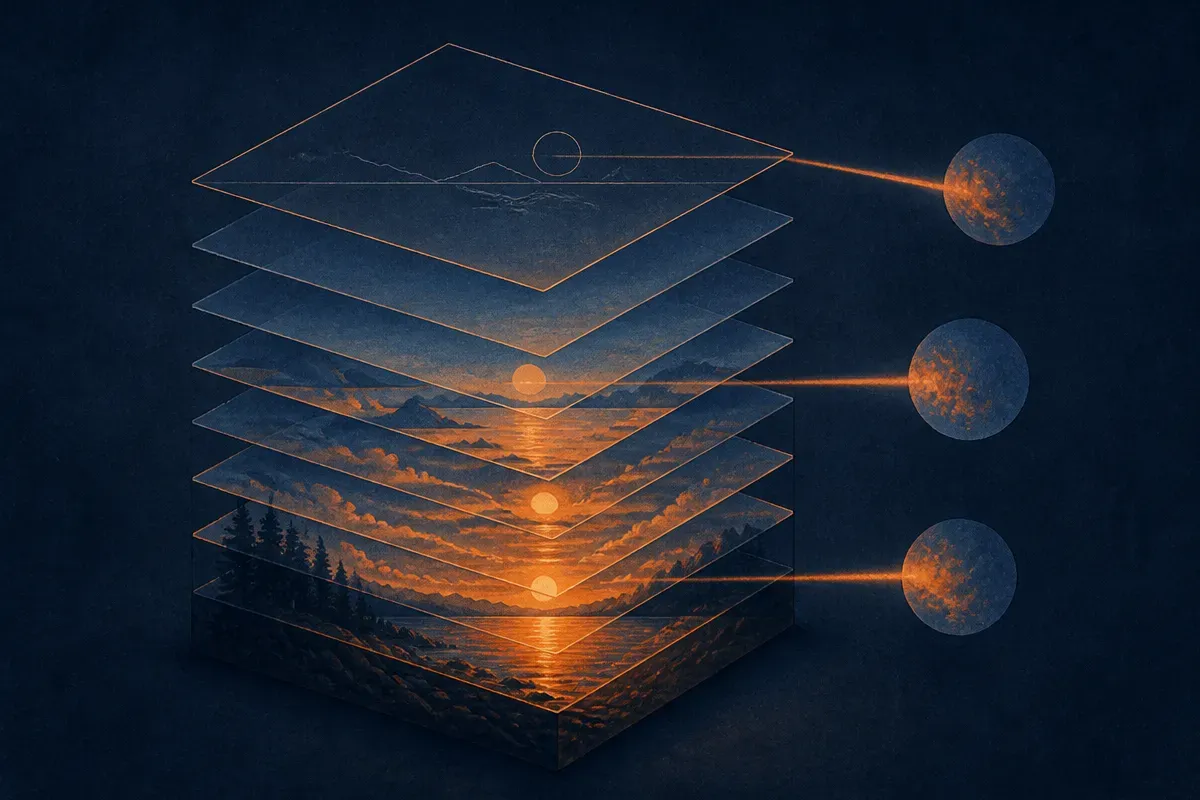
HiVe-Mem’s framing is that these are orthogonal axes. Horizontal is about which memories. Vertical is about how much of each memory. You can be good at one and bad at the other, which is why the authors insist on handling them as two operations instead of one retrieval score.
How does HiVe-Mem’s two-axis design actually work?
The horizontal axis organizes memory episodes into a relational graph, with textual and visual anchors as the connective tissue. Semantic retrieval still happens, but it only produces seeds. From each seed, the system expands outward to related neighbors in the graph to recover the complementary information that pure similarity would have dropped. So instead of “top-k nearest embeddings,” it is “nearest embeddings, then walk the graph to grab what connects to them.”
The vertical axis is where the token savings come from. Each memory keeps multiple evidence forms at once: a compact summary, a caption, a grounded visual view, the raw image, and the interaction history. Nothing is thrown away during storage. Then a lightweight trainable selector decides, per retrieved memory and per query, which subset of those forms to actually hand to the model.
That selector is the quiet heart of this. It is trained, not rule-based, and it composes evidence independently for each memory. So in a single retrieval you might get a full raw image from one episode, just a summary from another, and a caption plus interaction history from a third, all chosen for the specific question being asked. That is the “query-adaptive utilization of heterogeneous multimodal information” the abstract keeps circling.
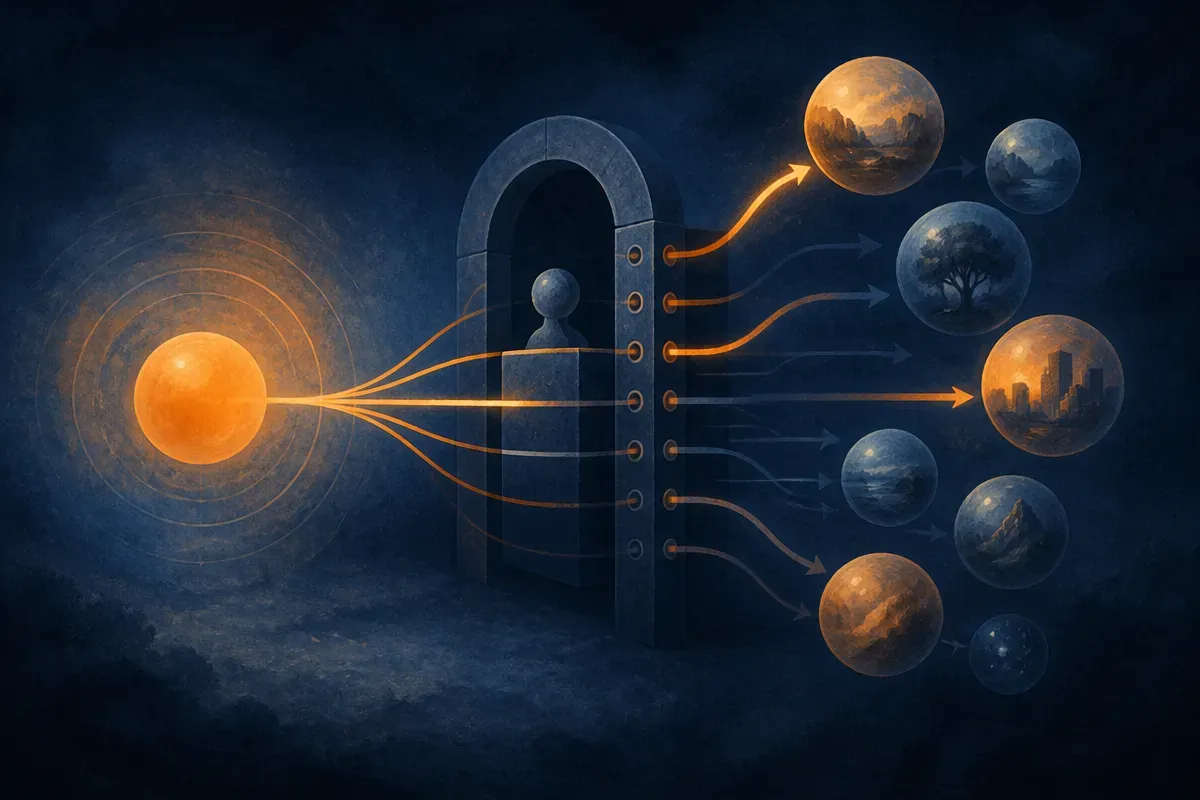
The combination is the pitch: go wider on coverage, go lighter on payload. Broaden what you pull in, then shrink what each piece contributes to only what the query needs.
Is the 90 percent token reduction believable?
The headline claim is roughly 90 percent fewer tokens than “the most efficient competing multimodal baseline,” with consistent task-performance gains across base models on three multimodal memory benchmarks.
I’d read that number with the right frame. It is a comparison against the most efficient baseline, which means the saving comes from the vertical selector refusing to ship heavy evidence forms when they aren’t needed. If your current setup naively stuffs raw images or full interaction logs into context every time, a trained selector that sends a summary most of the time will obviously cut tokens hard. The gain is real, but it is a gain against a wasteful default, and multimodal context is where tokens get expensive fastest. Images cost a lot of context. Not sending the image when a caption answers the question is where 90 percent comes from.
The parts I can’t verify from what I was given: the specific benchmarks, the exact base models, the absolute scores, and whether that selector generalizes past the eval distributions it was trained on. A trainable selector is also a trainable point of failure. If it learns to under-retrieve evidence to look efficient, task quality on harder, out-of-distribution queries is exactly where it would quietly degrade. The abstract says gains are consistent across base models, which is encouraging, but “three benchmarks” is a narrow window, and the paper as summarized doesn’t give me the failure analysis I’d want before trusting it in production.
What should a builder take from this?
The transferable idea does not require you to adopt HiVe-Mem’s code. It requires you to stop treating memory as one retrieval score.
Right now most agent memory stacks do flat vector search and dump whatever comes back into context at a fixed fidelity. Split that into two decisions you can tune independently. First, widen retrieval: after your top-k, pull in linked or adjacent items, whether that is a real graph or just metadata like same-session, same-entity, or temporal neighbors. Cheap to prototype, and it directly attacks the thin-slice problem. Second, make fidelity a choice per item. Store multiple representations of each memory up front (summary, caption, raw asset) and decide at retrieval time which to send. You can start rule-based (ship the image only when the query mentions something visual) before you ever train a selector.
The catch most readers will miss: the token savings and the quality gains come from different mechanisms, and only one of them is free. Wider coverage mostly helps quality. The 90 percent cut comes from the vertical selector, and a selector that is too aggressive trades invisible quality for visible efficiency. If you adopt the fidelity-selection idea, instrument it. Log which evidence form got sent and whether the task succeeded, so you can catch the selector quietly starving the model on the hard cases. Efficiency you can measure. The retrieval misses it causes, you can’t, unless you build the eval to look for them.