ConvMem Turns Long-Context Reasoning Into a Tree Instead of a Chain
A new training-free method reframes long-context reasoning as hierarchical convolution, trading MemAgent's slow sequential memory updates for a parallel logarithmic tree that skips the reinforcement learning bill and the overfitting that comes with it.
TL;DR: ConvMem reads a long document as a parallel tree of summaries instead of one long sequential chain, which cuts latency and skips reinforcement learning training entirely, at the cost of more model calls and a design you have to tune yourself.
The paper is “ConvMem: Convolutional Memory for Long-Context Reasoning,” posted to arXiv under both cs.AI and cs.CL. The core move is simple to state and clever in practice: treat an LLM, prompted with a specific query, as a convolutional kernel that slides over chunks of text and summarizes them. Then stack those summaries hierarchically, the way a CNN stacks layers, so the path from raw text to final answer becomes a logarithmic tree instead of a linear walk. That structural swap is the whole idea, and it’s worth taking seriously because of what it avoids.
What problem is ConvMem actually solving?
Context windows are bigger than ever, but “the model accepts 200K tokens” and “the model reasons well across 200K tokens” are different claims. Long-context reasoning still degrades, especially on multi-hop questions where the answer depends on stitching together facts scattered across the document.
The established workaround the authors name is MemAgent: read the text in segments, keep a fixed-size memory, and update that memory as you go. It works, but it inherits two problems from its sequential shape. First, latency. Every segment waits on the one before it, because each memory update depends on the last. Second, and more interesting, the way MemAgent learns to write good memory is through reinforcement learning, which is expensive to run and, the authors argue, prone to overfitting the specific datasets it trains on. RL-trained memory can lean on parametric priors, meaning the model answers from what it already knows rather than from the text in front of it. That’s fine until you hand it something out of distribution, and then the crutch shows.
ConvMem’s pitch is that you can get the benefit of iterative memory without the sequential bottleneck or the training bill.
How does the convolution framing change the shape of the work?
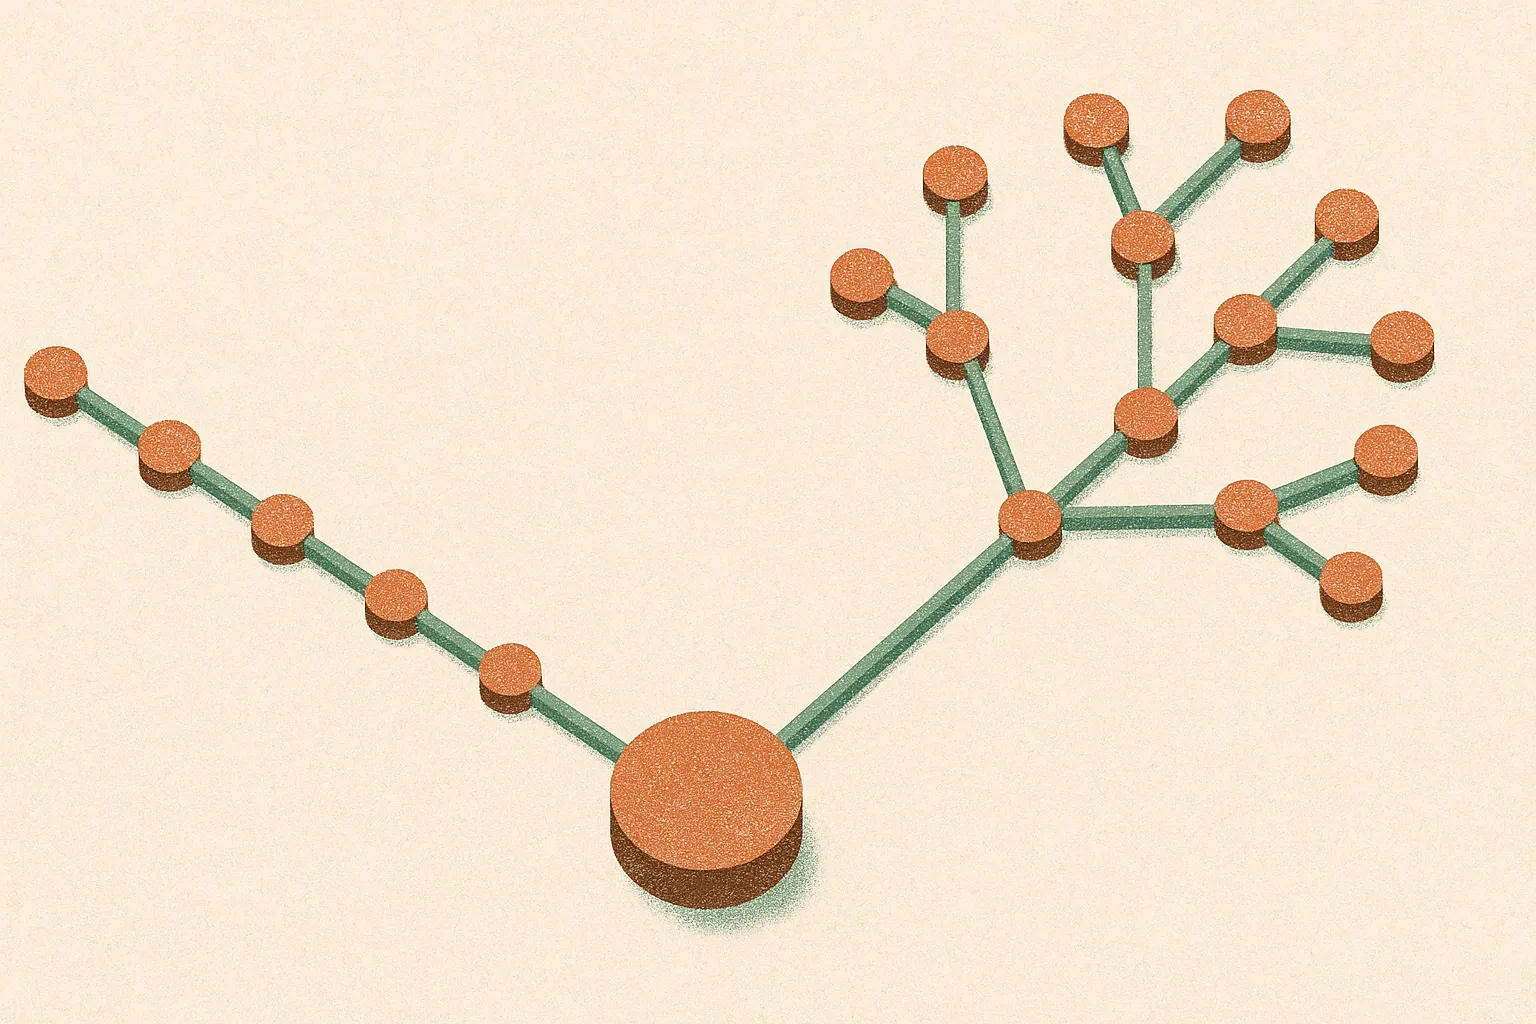
Here’s the mechanical part, in plain terms. Instead of one memory that gets rewritten segment by segment, ConvMem prompts the model with your query and runs it over each text segment independently to produce a local summary. Because those runs don’t depend on each other, they happen in parallel. Then it takes those summaries and summarizes them again, one layer up. Repeat until you have a single condensed answer path. A linear chain of N steps collapses into a tree of roughly log(N) depth.
Three pieces make it hold together, according to the paper:
Configurable Strides and Skip Connections handle a real failure mode in any chunk-and-summarize scheme, which is that evidence gets dropped or smeared as it moves up the hierarchy. Strides control how the kernel steps across segments; skip connections let lower-level evidence jump past intermediate summaries so it isn’t lost by the time you reach the top. Both names are borrowed straight from CNN vocabulary, and the analogy is doing honest work here, not just decorating the method.
Multi-Kernel Convolution decomposes a complex query into what the authors call disentangled semantic channels. A multi-hop question is really several sub-questions; rather than force one kernel to track all of them, you run multiple kernels, each tuned to a different facet, and keep the threads separate until you combine them. That’s the second axis of parallelism: you parallelize across text segments and across reasoning threads.
The payoff the authors claim is twofold: less error accumulation, because no single long chain compounds its mistakes, and massive parallelization, because independence is baked into the structure. If both hold, you get lower wall-clock latency and better robustness on the exact hard cases (multi-hop, out-of-distribution) where sequential memory struggles.
Do the results back the claim?
The evaluation runs on RULER-HotpotQA and RULER-2WikiMultiHopQA, two multi-hop QA benchmarks built on the RULER long-context suite. The paper reports that ConvMem outperforms training-free baselines and, notably, avoids the overfitting-to-parametric-priors problem that shows up in RL-trained models on out-of-distribution tasks.
Read that carefully, because the comparison is doing specific work. ConvMem beats training-free baselines head to head. Against RL-trained MemAgent-style approaches, the claim is narrower and more interesting: ConvMem holds up better when the task drifts away from what the RL model was trained on. So the headline isn’t “ConvMem is strictly stronger than MemAgent.” It’s “ConvMem gets competitive reasoning without training, and doesn’t inherit the brittleness that training introduces.”
That’s a claim I’d want to see stress-tested. Two benchmarks, both from RULER, both multi-hop QA, is a narrow slice. The abstract doesn’t give per-benchmark numbers, latency measurements, or the total token cost of running a hierarchical tree of model calls, and I’m not going to invent them. The honest read: the structural argument is strong, the evidence is early, and the thing I most want to know (how many extra model calls the parallelism costs in absolute terms) isn’t in the material here.
What’s the catch for someone building with this?
Parallelizable is not the same as cheap. Collapsing a chain into a tree reduces latency because independent branches run at once, but it can increase total compute, because you’re now running the model over every segment and then over the summaries of those segments, possibly with multiple kernels. If you’re latency-bound and have spare throughput, that’s a great trade. If you’re token-bound on a budget, you may be moving the cost rather than removing it. The abstract doesn’t settle this, so treat it as an open question, not a solved one.
The genuinely appealing part is “training-free.” No RL loop, no reward model, no dataset-specific tuning. You can bolt ConvMem onto an existing model as an orchestration pattern, which means an operator can prototype it this week without a training pipeline. That lowers the barrier from “research project” to “weekend build” in a way MemAgent does not.
The catch most readers will miss: the parameters that make this work (stride, kernel count, how you split a query into channels) are yours to tune, and there’s no learned policy setting them for you. Training-free shifts the burden from a GPU cluster to your own design judgment. That’s a fair trade for many teams, but it’s a trade, not a free lunch.
Practitioner’s take: if you’re running multi-hop retrieval or document QA and your current pain is either latency from sequential summarization or brittleness from an RL-tuned memory agent, ConvMem is worth a prototype. Start narrow: implement the single-kernel hierarchical summarize-then-summarize loop over your own document set, measure both latency and total token spend against your current chain, and only add Multi-Kernel decomposition once you’ve confirmed the basic tree beats your baseline. Watch the token bill closely, because the parallelism that buys you speed can quietly cost you volume, and no paper result substitutes for measuring that on your own workload. The idea is sound and cheap to test. Test it before you believe the benchmark.