MemPilot and the Case for Deciding Memory at Query Time, Not Ingest Time
A new paper argues agent memory should be curated on demand, with a learned policy that trades accuracy, cost, and latency per query instead of pre-chewing everything up front. Here is what that changes for anyone building agents with memory.
TL;DR: MemPilot’s pitch is that you should decide how much memory work to do when a query arrives, not when the data lands, and it uses reinforcement learning to make that call per query against a performance, cost, and latency budget you set.
The paper is “MemPilot: Orchestrating On-Demand Multimodal Memory Curation for LLM Agents,” posted to arXiv across cs.AI, cs.CL, and cs.LG. It is one of those papers whose core idea is almost embarrassingly obvious once you read it, which is usually a sign it is pointing at a real gap. Most agent memory today is built query-agnostic: you ingest a conversation, a document, a video, and you pre-process it into some fixed representation (chunks, summaries, embeddings) before you have any idea what will be asked. MemPilot’s authors argue that this is both wasteful and lossy. Wasteful because you pay to process things nobody asks about. Lossy because the summary you baked at ingest time throws away the detail a future question needed.
What is actually wrong with how agent memory works now?
If you have shipped a RAG system or an agent with long-running state, you already feel this tension even if you never named it.
The standard pipeline front-loads everything. You take raw history and compress it into whatever your retrieval layer expects. That decision is made once, blindly, before the user asks anything. The MemPilot authors call this query-agnostic construction, and they name two failure modes: unnecessary preprocessing cost, and discarding details that later prove essential.
The second one is the quiet killer. Say you store a meeting transcript as a three-line summary. Later someone asks who objected to the budget line and why. The summary ate that. Now your agent is confidently wrong, not because the model is bad but because the memory layer decided, days earlier, that the objection did not matter. You never see the decision. You just see a worse answer.
The paper frames the alternative as runtime adaptation, which is not new on its own. The authors acknowledge that recent work has started moving memory processing toward query time. Their complaint is that those systems “typically specialize in particular operations or fixed processing schemes.” You get one trick, applied the same way every time. What is missing is flexible control over the three things an operator actually cares about: how good the answer is, how much it costs, and how long it takes.
What does MemPilot do differently?
It treats memory curation as a decision problem and trains a policy to make it.
Here is the shape of it, in plain terms. When a query comes in, MemPilot runs a multi-step policy that repeatedly chooses between two moves: pull from the cheap query-agnostic memory you already built, or spend real compute to curate the raw multimodal history specifically for this question. That curation can be handed off to different models, including both LLMs and vision-language models, depending on what the query needs.
The policy jointly controls four knobs the paper lists explicitly: how much evidence to gather, what curation instructions to issue, which model to call, and whether to look at the visual content at all. That last one matters for multimodal agents, where cracking open the images or video frames is expensive and often unnecessary. If the question is answerable from text you already summarized, you should not be running a VLM over every frame.
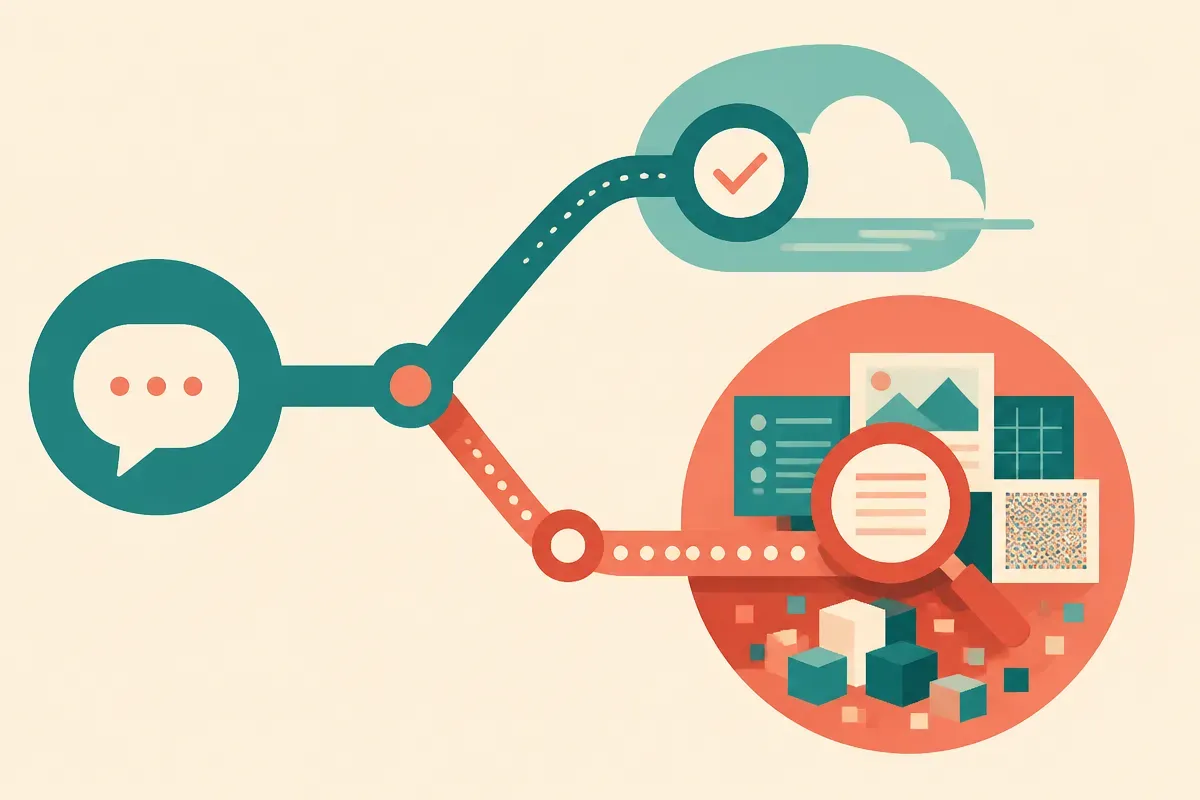
So the output is not a single memory system. It is a controller sitting on top of your memory, deciding per query how hard to work. A simple lookup gets the cheap path. A gnarly question that needs a detail nobody summarized gets the expensive path where raw history is re-examined with the right model. That is the “on-demand” in the title doing real work.
How do they train a policy for three goals that fight each other?
This is the part that separates the paper from a nice diagram, and it is where I would point a skeptical reader.
Accuracy, cost, and latency pull against each other. More curation usually means better answers, more money, and more waiting. A naive RL setup mashes those into one scalar reward and you lose the ability to see the trade-off. MemPilot’s authors adapt what they call objective-wise advantage decoupling: they estimate each objective’s advantage separately, then aggregate. In practice that means the training signal keeps the three goals legible instead of collapsing them into mush, so you can steer toward “cheap and fast” or “spare no expense” by setting a preference.
They add a second piece, prefix-based marginal utility estimation, for credit assignment across the multi-step rollout. Credit assignment is the hard part of any multi-step RL problem: when a sequence of decisions produces a good or bad outcome, which step gets the blame or the reward? Estimating marginal utility at each prefix is their answer to that. I will not pretend the abstract gives enough to reproduce it, and that is the honest caveat with any arXiv paper at this stage: the mechanism is described, the real test is whether it holds up when someone outside the group runs it.
On results, the authors report experiments on five multimodal agent-memory benchmarks and claim “favorable performance—cost—latency trade-offs across optimization preferences,” with preference sweeps producing broader frontiers than existing trade-off-aware baselines. Read that carefully. The claim is not a single state-of-the-art number. The claim is a better frontier: across a range of budgets, you can get more accuracy per dollar and per second than the baselines that also try to manage this trade-off. That is the right way to evaluate a controller, and it is a more honest claim than “we win on benchmark X.” It also means the paper lives or dies on how good those baselines were, which I cannot assess from the abstract alone.
Should you build this into your stack right now?
Not by copying it. By stealing the framing.
Most teams do not need a trained RL policy to get the main benefit. The actionable idea is the separation of two moments: ingest time and query time. Right now you probably do all your expensive memory work at ingest. Move some of it to query time. Keep the cheap query-agnostic layer for the common case, and keep enough raw history around that a hard query can trigger a deeper, query-specific pass. You can approximate MemPilot’s controller with a dumb router first: a classifier or even a heuristic that decides “cheap lookup” versus “go dig in the raw material,” before you reach for reinforcement learning.
The catch most readers will miss is storage and plumbing, not the policy. On-demand curation only works if you kept the raw multimodal history to curate. If your pipeline already threw away the original frames and transcripts after building summaries, there is nothing to re-examine at query time, and the whole idea collapses back into the lossy pattern the paper is trying to fix. So the first change is not a model. It is a decision to retain raw history and make it addressable, with the cost that implies. Do that, add a simple router, and you have captured most of the value before you ever train anything. The RL policy is the optimization you reach for once you have real query traffic to learn from and a cost ceiling you actually care about hitting.
Practitioner’s take: start by auditing where your agent loses detail, then deliberately move one expensive memory operation from ingest to query time behind a cheap router. Keep the raw history. Measure accuracy, cost, and latency as three separate numbers, not one blended score, because the entire point of MemPilot is that those three are a frontier you steer, not a single dial you crank.