Richer Context Does Not Automatically Fix LLM Social Agents
A new arXiv framework tests whether richer context makes LLM social agents less brittle, and the answer is useful but awkward: stability depends on the kind of context, the social change being tested, the model underneath, and not just prompt length.
TL;DR: If you use LLMs as social simulation agents, do not assume that adding more background context makes them more reliable, test whether the agent ignores irrelevant wording changes while still reacting to real changes in the situation.
What problem is this trying to solve?
The primary source here is the arXiv cs.CL/cs.LG paper titled “A Framework for Context Enrichment and Selective Robustness in LLM Social Agents.”
The problem is simple and annoying: LLM agents can change their behavior when the prompt changes, even if the meaning does not.
That is a big deal for social simulation. If an agent defects in one version of a Prisoner’s Dilemma-like setup and cooperates in another version that says the same thing with different phrasing, what exactly did you simulate? Human behavior? Model vibes? Prompt sensitivity?
The paper focuses on a validation gap. Researchers and builders often give agents observations, background, roles, social details, and task instructions, then treat the output as if it represents some stable simulated actor. But if small wording changes move behavior around, the simulation becomes hard to trust.
The useful move in this paper is that it separates two things people often blur together. One is context enrichment: adding different kinds of information to the prompt. The other is what the paper calls selective robustness: the agent should stay insensitive to meaning-preserving prompt variation, but still respond directionally when the social world actually changes.
That second part matters. A model that never changes its answer is not good. A model that changes constantly is not good either. You want an agent that is stable under paraphrase, but responsive to real decision-relevant changes.
Does richer context make LLM agents more reliable?
Not automatically.
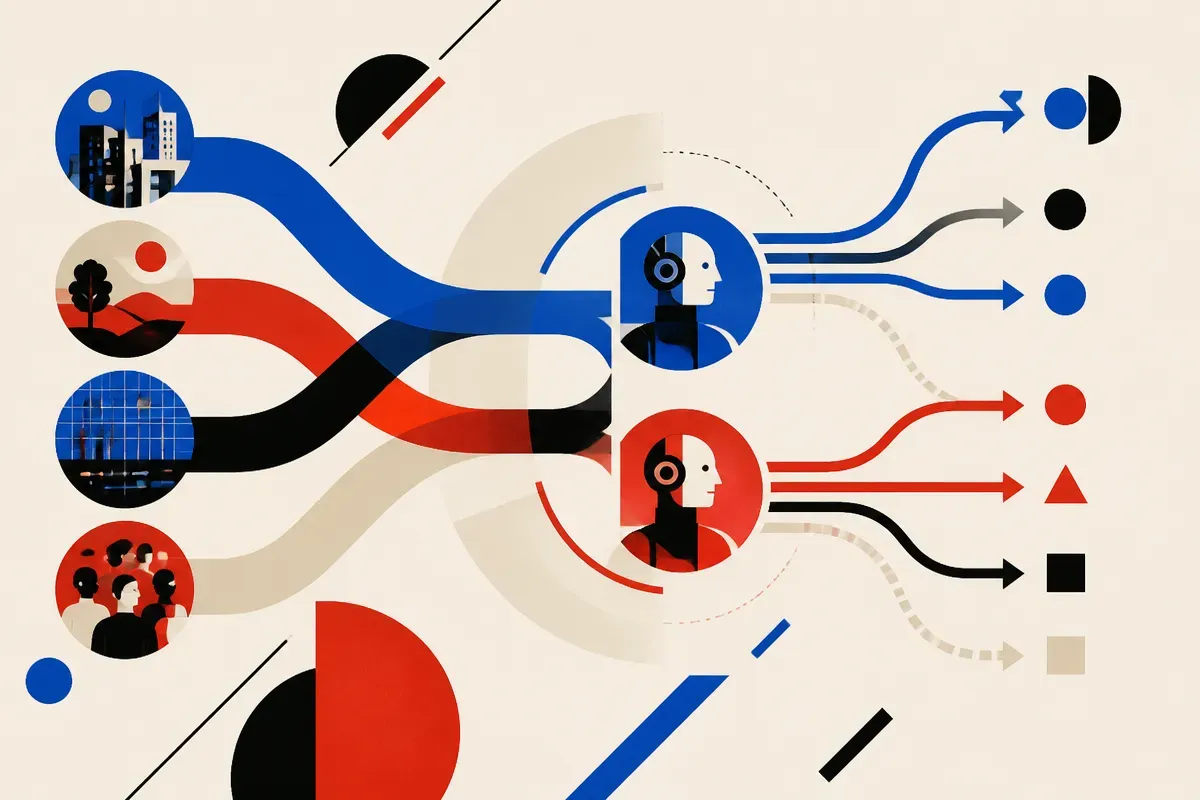
The arXiv paper tests controlled context enrichment through prompt substitution rules. It distinguishes neutral padding, generic social background, descriptive decision grounding, and normative decision grounding. Those are meaningfully different interventions, not just “make the prompt longer.”
That distinction is the point. Neutral padding may add words without helping the agent understand the decision. Generic social background may shape the feel of the scenario without grounding the choice. Descriptive grounding tells the agent more about the decision setting. Normative grounding introduces expectations about what should matter.
In the Prisoner’s Dilemma-like game, the framework showed that these enrichment types produced distinct behavior patterns. The paper also reports that results varied between the two models tested.
That is the part I would not smooth over. “More context fixes brittleness” is the tempting story. The evidence here is narrower and more useful: some context types can make behavior more desirable or stable under the paper’s criterion, but the effect is model-dependent.
For builders, that means context engineering is not a moral vitamin. It is an intervention. It can change the agent’s policy, not just clarify it.
What should builders test before trusting simulated agents?
The test I would steal is selective robustness.
Take your agent setup and create paraphrases that preserve meaning. The agent should not swing wildly. Then change something that should matter, such as incentives, social history, harm, trust, reputation, or payoff structure. The agent should move in the expected direction.
That sounds obvious. It is not how many agent demos are evaluated. Most demos inspect a transcript and ask, “Does this look plausible?” Plausibility is cheap. Stability under irrelevant variation, plus sensitivity to relevant variation, is a stronger bar.
This applies beyond academic social simulation. Customer-support agents, negotiation agents, synthetic user panels, policy role-play systems, sales training sims, and market research agents all run into the same issue. If changing “You are talking with Alex” to “Alex is the person you are speaking with” changes the result, your downstream analysis may be prompt-shaped noise.
Practitioner’s take: build a small eval harness before you trust an agent simulation. For each scenario, create three paraphrases and three meaningful world changes. Track whether the agent holds steady on the paraphrases and moves when the situation really changes. The catch most teams miss is that richer prompts may improve one behavior while distorting another, so test context types separately instead of dumping everything into one giant “better” prompt.