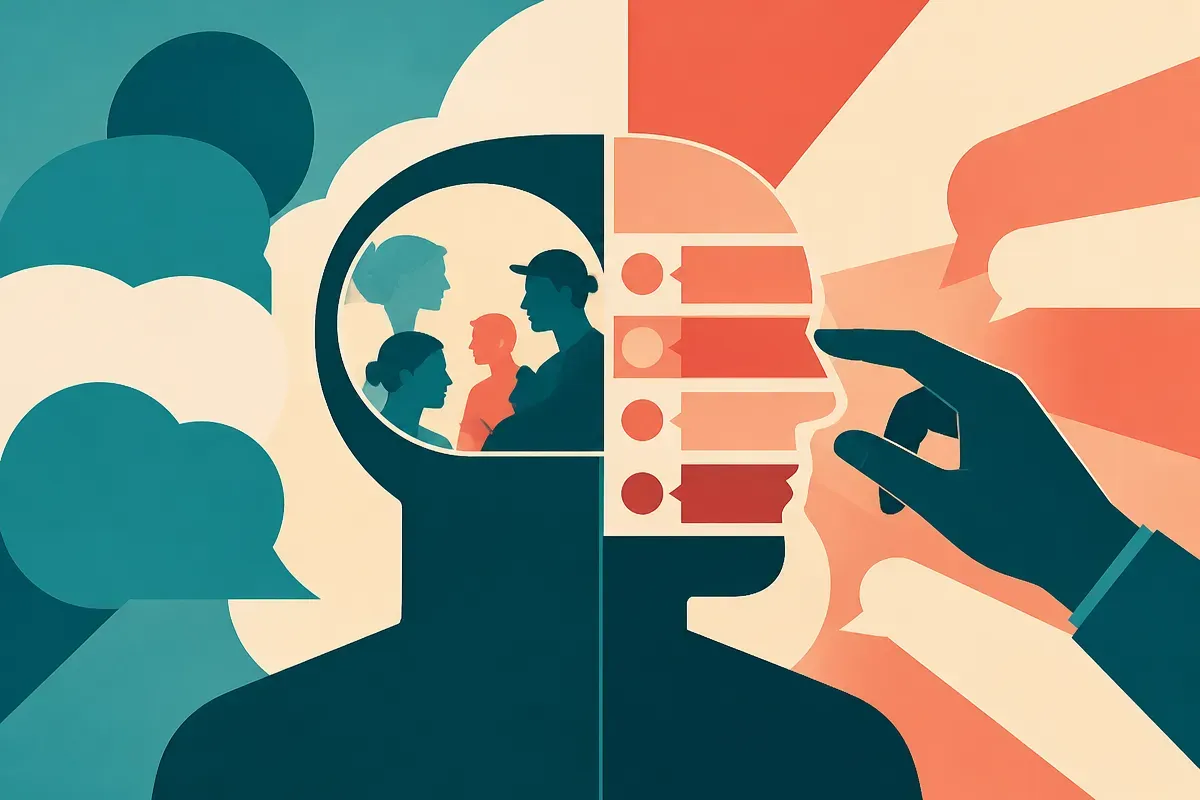
PerSo splits persuasion into reading people and choosing the next move
PerSo uses Reddit ChangeMyView dialogues to test whether LLMs can infer a person’s mental state and choose persuasive actions. The useful bit is the split: models may be good at picking replies without being equally good at understanding why those replies should work.
TL;DR: PerSo is useful because it separates two things people often blur together: whether an LLM understands someone’s beliefs, and whether it can pick a persuasive next response.
What does PerSo actually test?
The primary source here is “PerSo: Investigating Facets of LLMs’ Social Intelligence in Real-World Persuasion Scenarios”, listed on arXiv in cs.AI and cs.CL.
PerSo looks at social intelligence through persuasion. That is a good testbed because persuasion is not just “say something convincing.” It has two parts.
First, cognitive intelligence: can the model infer the other person’s mental state? What do they believe? What do they care about? What are they resisting?
Second, behavioral intelligence: given that read, can the model choose the right social action to move the conversation toward a goal?
That split matters. A model can sound socially fluent without actually modeling the person very well. It can also infer a belief correctly and still choose a clumsy next move. PerSo tries to catch that distinction using real persuasion dialogues from Reddit’s ChangeMyView community, rather than only synthetic vignettes.
The benchmark was built with an LLM-in-the-loop pipeline and validated with human annotation. That combination is now common in eval work, and it cuts both ways. It makes benchmark construction more scalable. It also means serious users should inspect the task construction before treating scores as clean truth.
Did the models beat humans?
Partly.
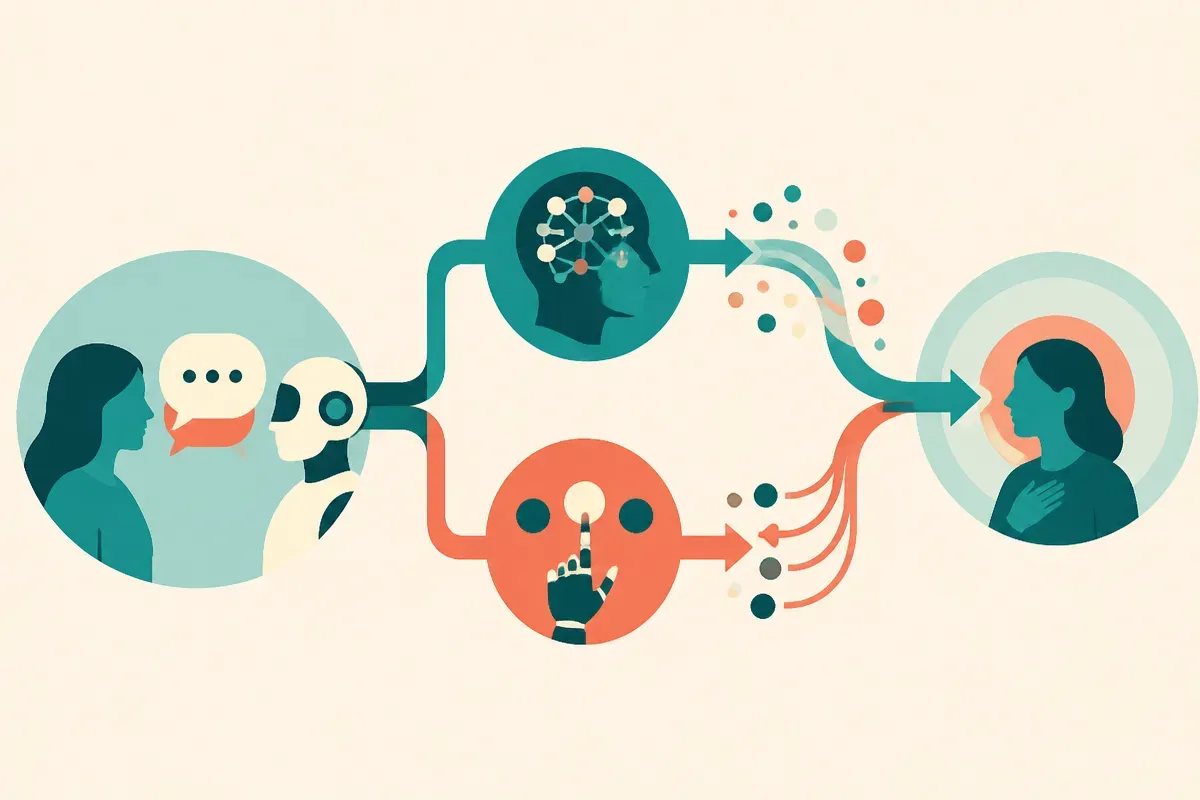
PerSo reports that performance generally scales with model size, but not evenly across the two dimensions. The strongest LLM slightly surpassed the best observed human performance on the behavioral task. In plain English: picking the socially appropriate persuasive move is becoming a model strength.
But the best human participant remained ahead on the cognitive task. That is the more interesting result.
It suggests current models may be better at selecting plausible social actions than at deeply inferring what is going on inside the other person’s head. That fits what many builders see in practice. The model gives a polished reply. Sometimes a very good one. But ask it to explain the user’s unstated motivation, uncertainty, or status concern, and the answer can get thin fast.
This is not a dunk on LLMs. It is a useful map. If you are building an AI tutor, support agent, sales assistant, negotiation bot, moderator, or coaching product, the difference between “good next sentence” and “accurate model of the person” is not academic. It changes what you should trust the system to do.
Where should builders be careful?
Reddit ChangeMyView is real human dialogue, but it is still a specific environment. People there know they are arguing. They often write long, explicit positions. They may behave differently than customers in a refund chat, patients in a medical intake, or employees in a workplace dispute.
So I would not read PerSo as proof that LLMs have general-purpose social intelligence. I would read it as evidence that persuasion evals are getting sharper, and that the next useful frontier is diagnostic, not vibes-based.
The key product lesson is to separate “understanding” from “response selection” in your own evals. If your agent is meant to persuade, coach, retain, upsell, de-escalate, or advise, do not only grade the final message. Also test the intermediate read: what does the model think the user believes, fears, wants, misunderstands, or refuses to accept?
Then grade those claims against human judgment.
A good operational eval might ask the model to produce two artifacts: a private belief-state estimate and a public response. Score them separately. If the response works but the belief-state estimate is wrong, you have a brittle system. If the belief-state estimate is right but the response is poor, you may have a fixable policy or prompting problem.
For builders, I would try PerSo-style evaluation before adding more agent loops. Take 100 real conversations from your domain, annotate the user’s state and the desired next move, then test both separately. The catch most readers miss: the model that sounds most persuasive may not be the model that understands your user best.