The World Model That Edits the Agent's Mind, Not the Environment
A new arXiv paper argues LLM agents fail less from bad tool predictions and more from stale assumptions rotting in their own history, and proposes editing the reasoning trace instead of simulating the world.
TL;DR: A new world model for LLM agents skips simulating tool outputs and instead edits the agent’s own reasoning trace, cleaning out stale assumptions that quietly corrupt long-horizon tasks, and it lifts scores by 3.2 to 6.7 points across six benchmarks.
The paper is “Agent-Editing World Model: Rethinking World Modeling for LLM Agents,” posted to arXiv across cs.AI, cs.CL, and cs.LG. It makes an argument I think most agent builders have felt without naming: the thing that kills a long task usually isn’t a wrong prediction about the outside world. It’s the agent believing something it decided ten steps ago that stopped being true.
What is a “world model” actually supposed to do for an agent?
The standard recipe for a language world model is to predict the next environment observation. You take the history, you take a proposed action, and you generate what the tool would probably return. The idea is that if the agent can imagine outcomes, it can plan better without paying for real execution.
The authors call this mostly wasted effort. Tool responses are high-entropy and execution-dependent. A search result, a terminal dump, a compiler error: these are hard to reconstruct faithfully and, more to the point, you often have real feedback available anyway. Why burn model capacity hallucinating a plausible stdout when you can just run the command and read the actual one?
That reframing is the whole move. Instead of modeling the world, they model how the agent’s own reasoning and actions shape future task progress. The environment stays real. What gets simulated and corrected is the agent’s internal state.
Why do long-horizon agents fall apart mid-task?
The failure mode they name is task-state contamination. Unsupported assumptions and outdated plans persist in the history and distort every decision that comes after.
If you’ve watched a coding agent work for twenty minutes, you know exactly this. It decides early that a file lives in one directory. That turns out wrong, but the assumption never gets flushed. It keeps referencing the wrong path, keeps writing code around a belief that was invalidated five steps back, and the transcript carries the rot forward because the model treats its own prior output as context worth trusting. The tools work fine. The world is behaving. The agent is arguing with a ghost.
This is why “just give it more context” and “just let it run longer” often make things worse, not better. A longer transcript is a longer memory of your own mistakes. Contamination compounds.
The Agent-Editing World Model, or AEWM, attacks this directly with two pieces. Action Judge classifies each decision as Critical, Exploratory, or Noisy. State Revision then edits the noisy reasoning-action continuations, rewriting them from the same observed history rather than appending yet another correction on top. The combined mechanism, EditAct, integrates with real execution and, in the authors’ words, directly changes the state underlying subsequent decisions rather than merely providing critiques.
That last distinction matters. A lot of self-correction work amounts to bolting a critic onto the loop: the agent gets told “you might be wrong here,” and that critique becomes one more thing in the pile. AEWM doesn’t add a comment. It edits the record so the bad assumption stops existing.
How well does editing the trace actually work?
Here are the numbers the paper reports, and I’ll take them at face value while noting they’re the authors’ own benchmarks.
Action Judge hits 70.5% macro-F1 on their classification benchmark, which they say beats the strongest frontier baseline by 10.6 points. So the classifier that decides which decisions are noise is meaningfully better than just asking a frontier model to sort its own steps.
EditAct improves average scores by 3.2 to 6.7 points across six benchmarks and three agent backbones. They train across three domains: Search, Terminal, and Software Engineering, using mid-training and supervised fine-tuning. The range across backbones tells you the effect isn’t a fluke of one model.
Then the part I find most interesting for practitioners. They run rejection sampling fine-tuning on verified EditAct trajectories, call it AEWM-RFT, and get 2.2 to 2.6 points over Self-RFT across the three domains without online AEWM guidance at inference time. Translation: you can use the editing machinery during training to generate cleaner trajectories, distill that into the base agent, and then run the agent normally with no extra editing loop in production. The benefit bakes in.
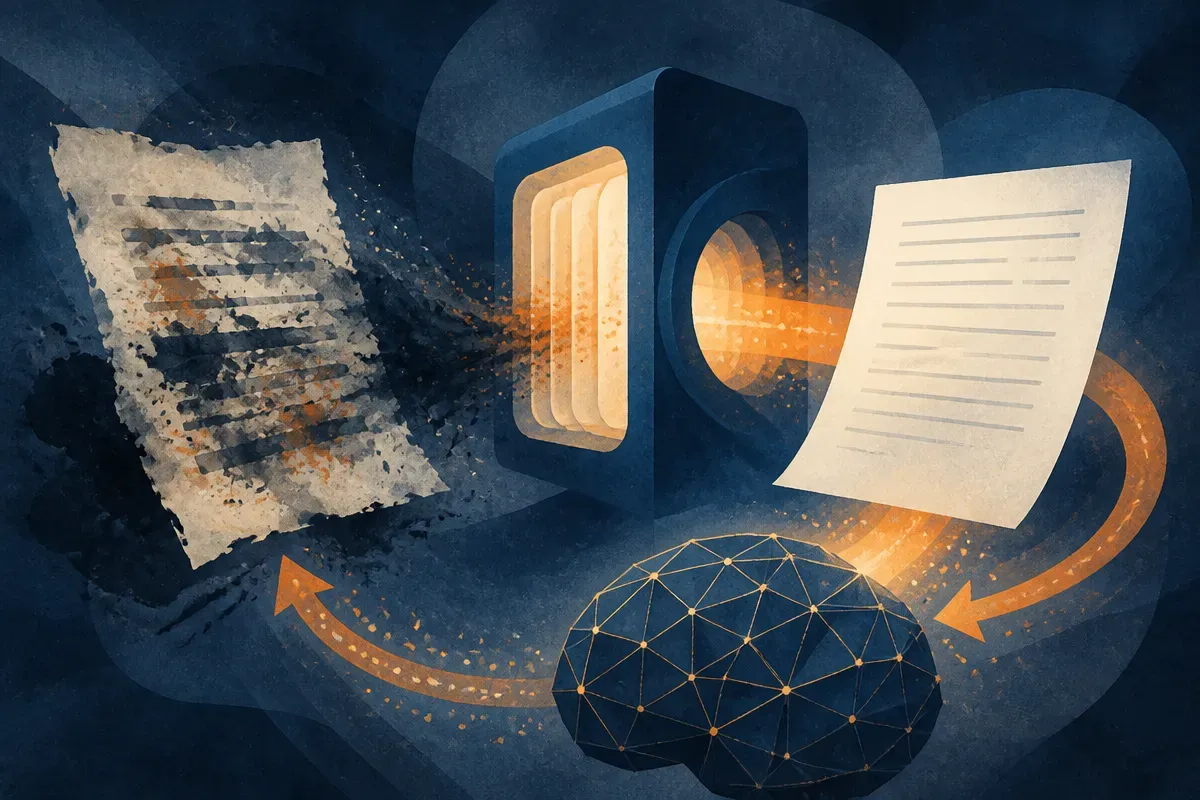
That’s the difference between a runtime tax and a one-time cost. An online correction loop means every task pays for extra passes forever. The RFT version means you pay once, at training, and ship a leaner agent. For anyone doing cost math on agent deployments, that gap is the story.
Where I’d be skeptical
A few things to hold lightly. These are the authors’ own benchmarks, including the Action Judge benchmark they built to evaluate the component they invented. That’s normal in this kind of work, but it’s not the same as independent replication on established suites. The gains, 3.2 to 6.7 points, are real but not the kind of number that reshapes the field overnight. And “Noisy” versus “Exploratory” is a judgment call. An exploratory step that looks like noise in hindsight was doing useful work at the time. Edit too aggressively and you prune the branches an agent needs to find non-obvious solutions.
There’s also a philosophical wrinkle worth sitting with. Editing an agent’s own history is a form of rewriting its memory of what it thought. That’s powerful and slightly unnerving. You’re deciding, on the agent’s behalf, which of its past beliefs get to survive into the present. Done well, that’s hygiene. Done carelessly, it’s a way to launder bad reasoning into confident-looking cleanliness.
Practitioner’s take
If you build agents, the reusable idea here costs nothing to try before you touch any of the paper’s training pipeline. Add a step that classifies your agent’s recent reasoning into keep, explore, and noise, then actually rewrite the transcript to drop the noise before the next action, instead of appending a “wait, correction” note. Most self-correcting agents pile fixes on top of mistakes; this pulls the mistake out of the context entirely. You can prototype that with a second cheap model as the Action Judge and a rewrite prompt, no fine-tuning required, and see if your long-horizon coding or research tasks stop arguing with themselves.
The catch most readers will miss is the AEWM-RFT result, not the headline scores. The point isn’t to run a fancy editing loop at inference forever. It’s to use editing during training to manufacture clean trajectories, distill those into the agent, and then run plain. If you’re going to invest here, invest in the data-generation angle. That’s where the compounding cost of a runtime correction loop turns into a one-time training expense, and that’s the version that survives contact with a production budget.