CoPE trains agents to forecast their own future actions
CoPE is a training method for language agents that turns successful rollouts into multi-step action supervision, improving sample efficiency without adding inference-time machinery.
TL;DR: CoPE’s useful idea is simple: train an agent not only to act, but to predict the future action sequence that worked, so long-horizon rollouts teach more than one final reward.
What does CoPE change about agent training?
The primary source here is the arXiv paper “Co-Evolving Acting and Forecasting for Language Agents,” with code published at https://github.com/ulab-uiuc/CoPE.
The problem is familiar if you have tried to train agents for anything beyond toy tasks. Long-horizon rollouts are expensive. Standard agentic reinforcement learning often waits until the end of a trajectory, gets a scalar reward, and then tries to assign credit backward through a messy chain of steps. That wastes a lot of signal.
Existing fixes usually go two directions. One is value targets, where each step gets an estimated chance of eventual success. Useful, but those targets still trace back to the same terminal reward. The other is observation prediction, where the model learns to predict the environment response. Also useful, but web pages, terminal logs, app states, and simulator observations can be long, noisy, and only one step ahead.
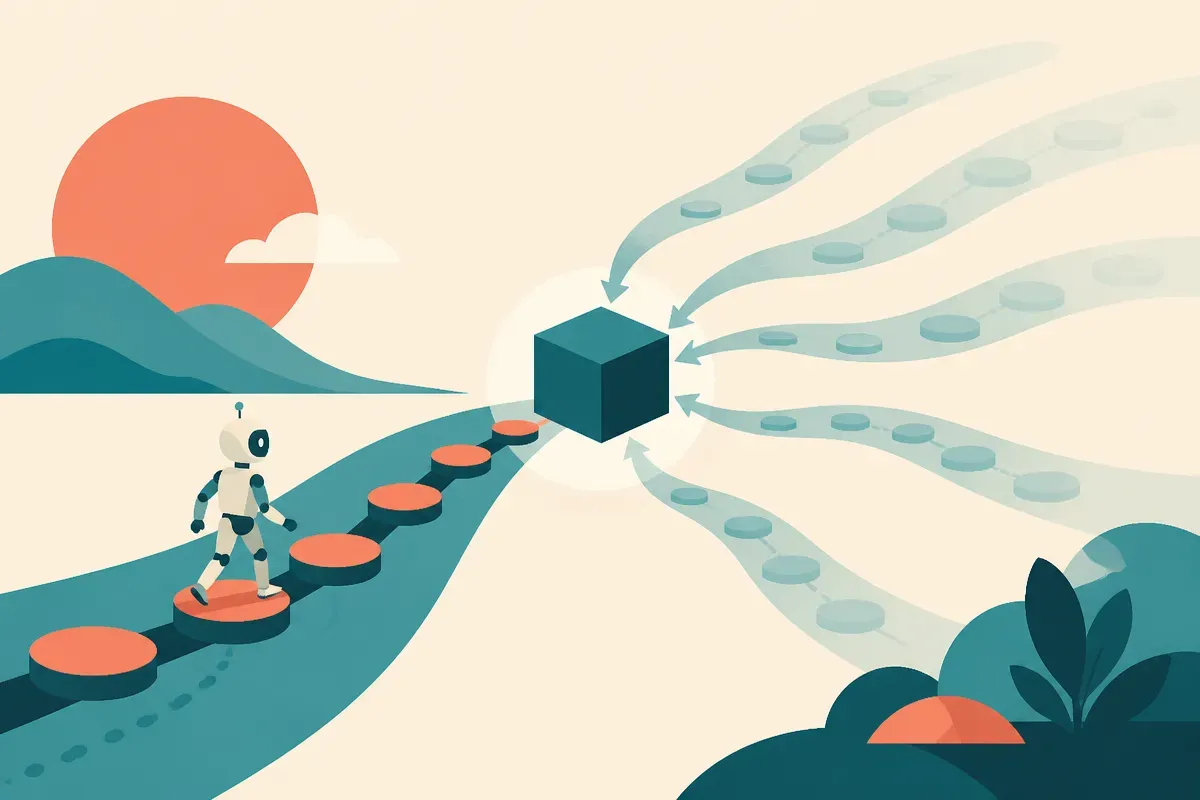
CoPE adds a third target: future action sequences from successful on-policy trajectories. After a successful run, the method trains the same policy backbone to generate the actions that followed each prior history. So an action near the end of a successful task is not only supervised at the moment it happened. It is also supervised as something the model should have been able to forecast from earlier states.
That is the core trick. The agent still acts one step at a time at inference. No second planner. No separate world model. No extra inference overhead, according to “Co-Evolving Acting and Forecasting for Language Agents.”
Why does forecasting actions matter more than predicting observations?
For agents, “what should I do next?” is often the cleaner learning target than “what will the whole world look like next?”
Observation prediction sounds attractive, but in realistic software environments the next observation can be huge. A webpage may include irrelevant markup, repeated navigation, ads, tables, logs, or UI state that does not matter to task success. A terminal output might contain boilerplate, warnings, or noise. Training on that can teach the model to imitate the environment’s surface area instead of the policy’s useful decisions.
Action forecasting is narrower. It asks the model to learn the structure of successful behavior. If the agent bought the right item in WebShop, solved a task in ScienceWorld, or completed an app workflow, the future actions contain a compressed trace of intent. Search. Filter. Click. Verify. Submit. The exact observation can vary, but the action pattern carries the plan.
That does not make CoPE a full answer to credit assignment. It only trains from successful on-policy trajectories, so the quality and diversity of those successes matter. If your agent rarely succeeds, there is not much future-action gold to mine. If it succeeds through brittle shortcuts, CoPE can reinforce those too. The paper’s contribution is not “agents now plan.” It is more specific: successful trajectories can be reused more efficiently by turning later actions into multi-step supervision for earlier histories.
What do the benchmark results actually show?
“Co-Evolving Acting and Forecasting for Language Agents” reports results across ALFWorld, ScienceWorld, WebShop, τ²-bench, and AppWorld. CoPE beats GRPO and reinforcement-learning baselines with predictive auxiliary targets in aggregate across simulated environments, while improving overall performance on the more realistic applications. On ScienceWorld, the paper reports up to 1.9x higher sample efficiency than ECHO and up to 2.0x higher sample efficiency than GRPO.
Those are meaningful claims because sample efficiency is the operator pain point. Long-horizon agent training is not just about final score. It is about how many costly attempts you need before the agent becomes usable. If CoPE can extract more training signal from each success without adding inference cost, that is the kind of improvement that compounds.
The catch is benchmark transfer. ALFWorld, ScienceWorld, WebShop, τ²-bench, and AppWorld cover useful ground, but they are still controlled evaluation settings. Real production agents face changing websites, permissions, flaky APIs, partial observability, hidden business rules, and user-specific context. CoPE looks like a better training recipe, not proof that autonomous agents are ready to run open-ended workflows unsupervised.
For builders, I would try this idea before chasing heavier agent stacks: log full successful trajectories, slice them into histories, and train or fine-tune the model to forecast the next several actions that completed the job. Start with narrow workflows where success is easy to verify. The catch most readers miss: the value is not the forecasting step at runtime. The value is using forecasting during training to make each expensive successful rollout teach the policy many times.