Tev's Dense Progress Rewards and the Sparse-Reward Problem in Long-Horizon Agents
A new arXiv paper tackles why open-source agents fall apart on tasks that run for hours: sparse rewards and no training data. Tev builds a hidden world spec first, then turns progress into a dense per-step signal that makes hard tasks trainable.
TL;DR: The hard part of training agents that run for hours is not the model, it is that you get one reward at the very end and nothing in between, and Tev’s fix is to build a correct hidden spec of the task first so you can score partial progress at every step.
Long-horizon agents are the capability everyone keeps pointing at: software that works on its own for hours or days, chains hundreds of tool calls, and finishes something economically real. The pitch is obvious. The training reality is ugly. Most of these tasks hand you a single pass/fail at the end. Run an agent for three hours, watch it take the wrong turn at step 12, and the only signal you get is a zero at step 400. That is a brutal gradient to learn from.
The paper Tev: Scaling Long-Horizon Agentic Environments with Dense Progress Rewards (posted across arXiv cs.AI, cs.CL, and cs.LG) goes directly at that problem. Two moves: a dataset built so progress is measurable, and a reward recipe that turns that progress into a per-step signal. I want to walk through why those two things matter together, and where I’d be skeptical.
A note on the benchmark names before we go further. The abstract cites GPT-6 Astra, Claude Opus 5, Claude Opus 4.8, GLM 5.2, Gemini 3.7 Flash, and benchmarks like Agents’ Last Exam and Terminal-Bench 3.0/4.0. Some of those read as ahead of what’s publicly shipped today. I’m taking the comparisons as the authors reported them and not treating the leaderboard positions as settled. The method is what’s interesting, and the method stands on its own.
Why do long-horizon agents fail to train at all?
Two reasons, and the paper names both. There’s no good training data, and the reward is sparse.
The data problem is real and underrated. To train an agent on a long task you need a task you can actually verify. For a 400-step workflow, “did it succeed” requires you to know what correct looks like at the end, which means you need a ground-truth model of the whole domain. Curating that by hand is slow and error-prone. Most teams don’t have 1,000 verified long-horizon environments lying around. They have a handful of hand-built evals and a lot of hope.
The reward problem compounds it. Even if you have the task, a single terminal reward is a weak teacher. Reinforcement learning on sparse rewards is famously sample-hungry because the credit assignment is impossible: the model can’t tell which of its 400 decisions mattered. Classic RL hit this wall decades ago. Long-horizon agents hit it again, harder, because the horizons are longer and each step is a full tool call rather than a joystick nudge.
What is the “latent world first” trick, actually?
This is the clever part. Instead of writing an agent-facing task and then trying to verify it, Tev inverts the order.
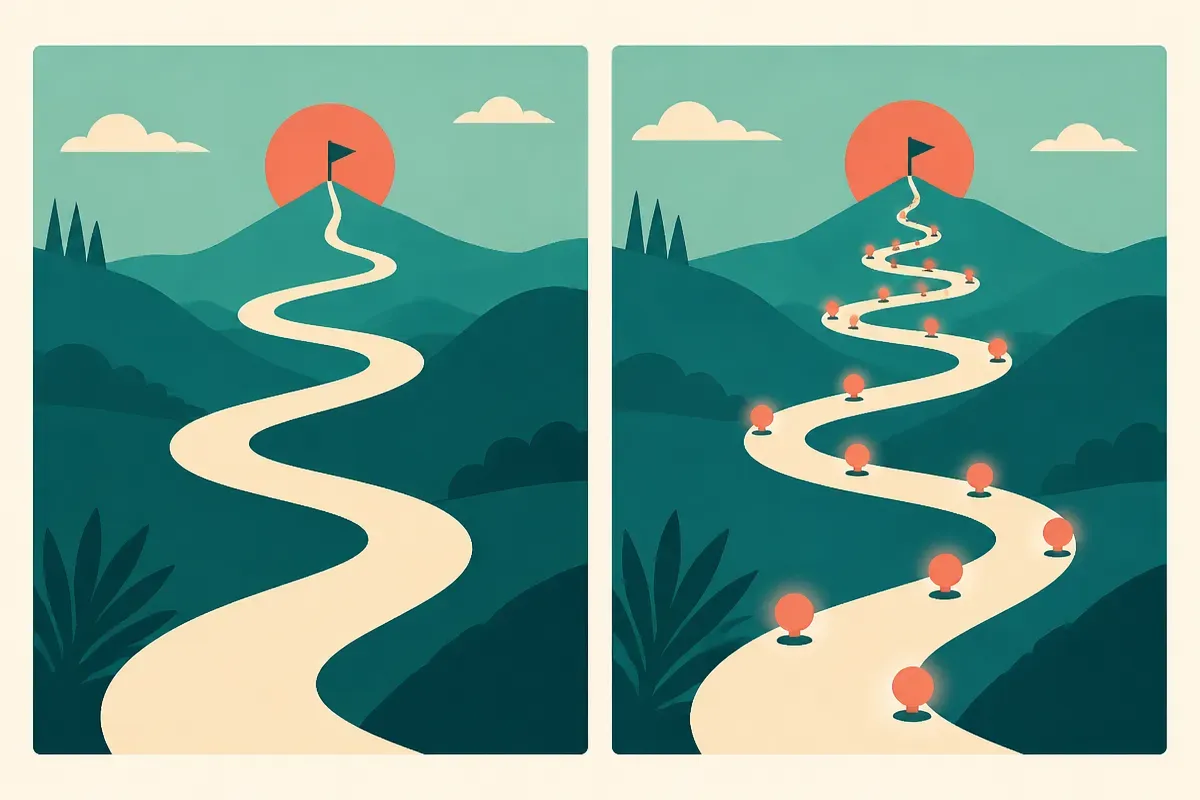
First it constructs what the authors call a latent world: a complete, correct, hidden specification of the task domain, the workflow, and the expected state after every step. Think of it as the answer key written before the test. Because the spec is complete and the step-by-step expected state is known, you get verification almost for free. You always know what correct looks like at step N.
Then each task gets progressively rendered from that spec into an environment the agent sees. Because the authors control the spec, they control the complexity dial, and more importantly they get a natural progress metric: how far along the known-correct trajectory is this agent right now.
That’s the unlock. The progress metric isn’t bolted on after the fact or estimated by a judge model. It falls out of the construction. That’s what lets Tev-Gym ship 1,170 verified task environments across 7 domains with dense, progressive rewards rather than terminal-only ones.
How does progress become a usable training signal?
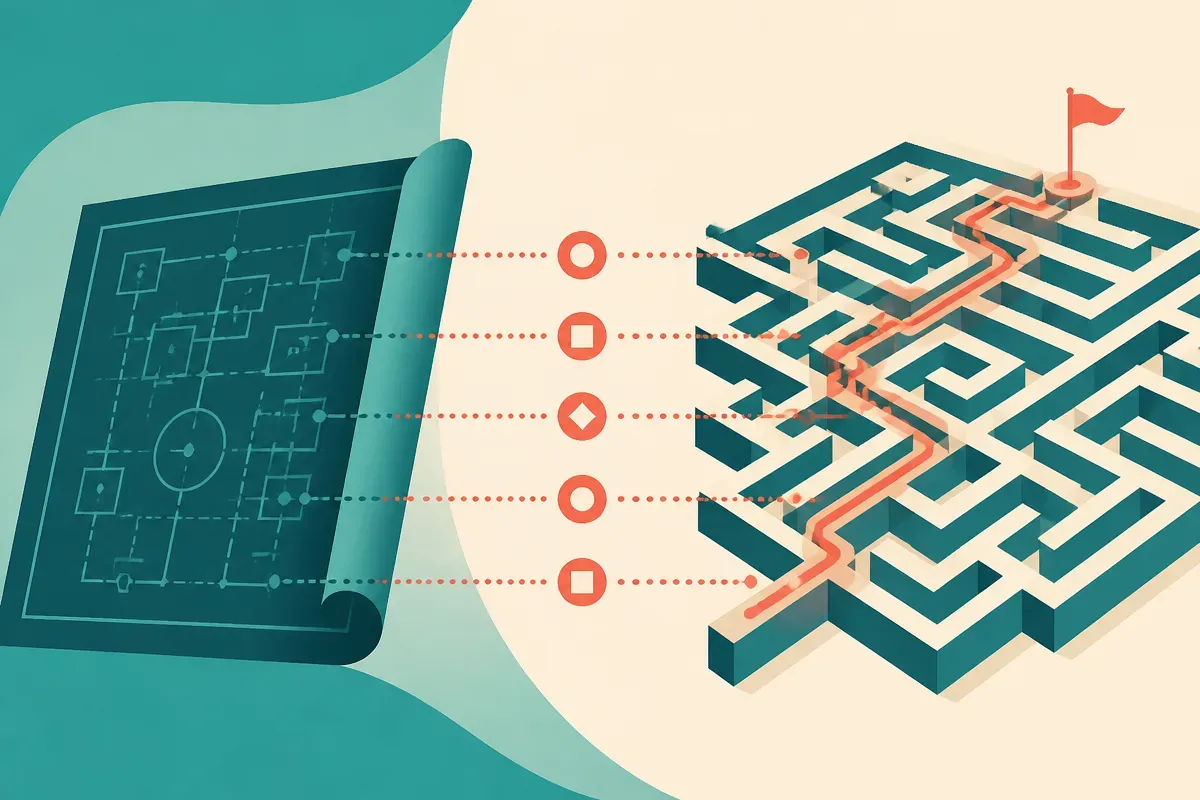
Having a progress number is not the same as having a reward you can train on. Reward shaping is a minefield: add a naive bonus for “looking busy” and the agent learns to game the bonus instead of finishing the task.
Tev uses progress-potential reward shaping (PPRS), which converts progress into a dense per-step reward. The “potential” framing matters. Potential-based reward shaping is the one form of shaping with a theoretical guarantee that you don’t change what the optimal policy is, only how fast the agent learns it. You’re not bribing the agent toward a different goal, you’re giving it a denser map to the same goal. That’s the right instinct. Dense enough to teach, shaped carefully enough not to corrupt.
The result is Tev-27B. Trained with this recipe, it posts gains on the ALE computing and math sciences domains (ALE-CM), and the authors report it matching GPT-6 Astra and Claude Opus 5 at Pass@5. The part I find more convincing is the generalization claim: trained only on ALE-related data, it transfers to Terminal-Bench 3.0 and 4.0 subsets and holds up on middle-horizon tasks like TB 2.1. Transfer is the honest test of whether a method taught something general or just memorized a benchmark. If that holds, the dense-progress approach taught the model how to make steady forward progress, not how to pass one exam.
What should a builder take from this?
The headline number (a 27B matching frontier models at Pass@5) is the kind of claim I’d want to reproduce before repeating. Pass@5 is forgiving: five samples, one has to land. That’s a real metric for some workflows and a flattering one for others. Watch for Pass@1 when it shows up.
But the method is the takeaway, and it generalizes beyond this one model.
The practitioner’s take: if you’re building agents that run long and you’re stuck on evaluation and training, steal the ordering, not just the paper. Most teams write the task, run the agent, and then try to grade a messy transcript after the fact. Invert it. Write the correct trajectory first, the known-good sequence of states, and derive your scoring from that. Even if you never touch RL, that gives you a progress metric for free, which is worth more than a pass/fail for debugging: you can see where the agent fell off the path instead of just that it failed. The catch most readers will miss is that this only works when you can specify correctness completely. For a coding task or a structured workflow with a known end state, the latent-world-first move is clean. For open-ended, taste-driven work where there is no single correct trajectory, there’s no spec to render from, and the whole trick quietly stops applying. Know which kind of task you have before you build the harness for it.