OpenAI wants shared AI standards, but the hard part is enforcement
OpenAI’s call for global AI standards is useful if it turns into shared evaluations, comparable reporting, and governance that changes launch decisions. The risk is a safety vocabulary everyone adopts while still grading themselves.
TL;DR: OpenAI is right that AI needs shared standards, but standards only matter if they make model behavior comparable, reported clearly, and tied to real deployment decisions.
What is OpenAI actually asking for?
OpenAI’s blog post, “Building standards for the next phase of AI,” argues for shared global AI standards built around coordinated evaluation, reporting, and governance. That is the useful core. Not one company declaring its own safety bar. Not a PDF that reads well at policy events. A common way to test systems, describe risks, and decide what happens next.
That matters because AI safety still has a measurement problem. Every lab can say it evaluated a model. Fewer can make those evaluations comparable across systems, versions, tools, and deployment settings. A frontier model used as a chatbot is one thing. The same model connected to code execution, browsing, payments, or internal company data is another thing.
The word “standards” can sound boring. Good. Boring is the point. Aviation, medicine, payments, and cybersecurity all run on boring shared processes that make weird edge cases less weird. AI is not identical to any of those fields, but the lesson travels: if everyone uses private tests and private thresholds, the public gets trust theater.
Where do standards actually bite?
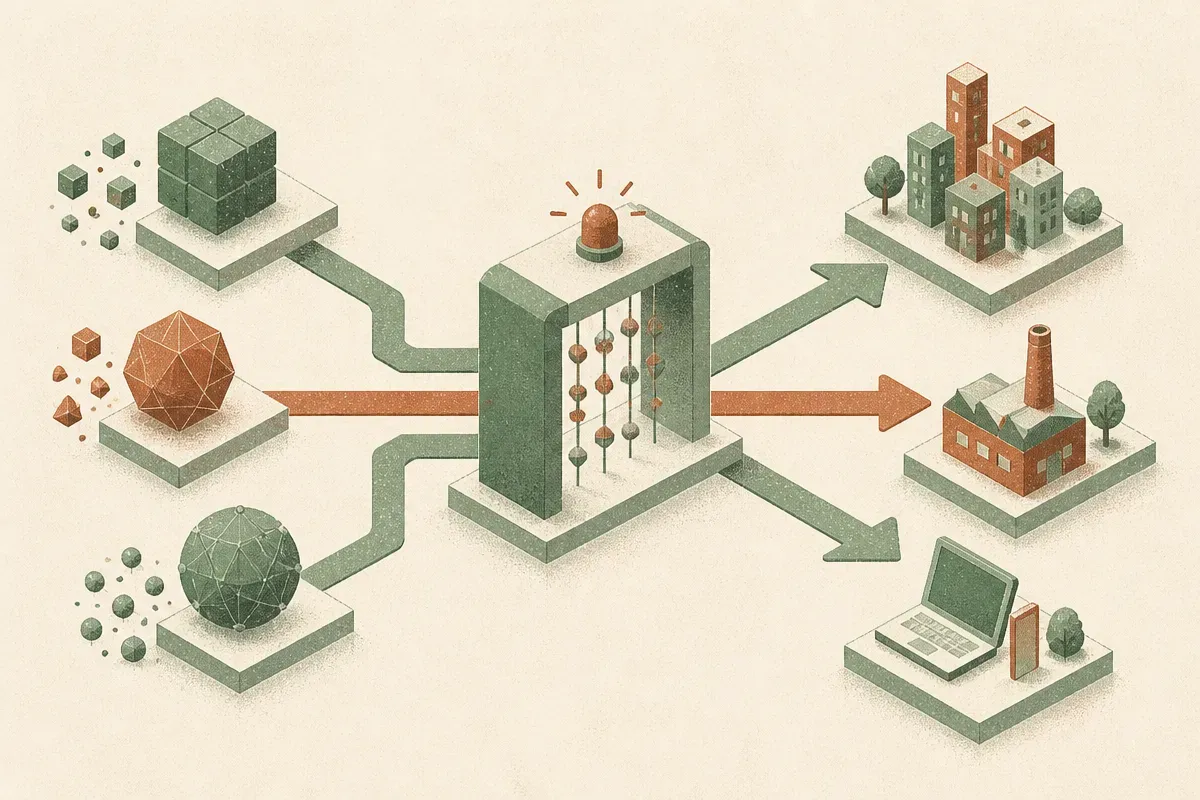
The first place is eval design. A shared standard should force labs and deployers to say what they tested, what they did not test, and what changed between model versions. It should separate benchmark performance from operational risk. A model can score well on reasoning tasks and still be a bad fit for an agent workflow that can take irreversible actions.
The second place is reporting. If reporting is just glossy safety language, it will not help users, developers, regulators, or competitors. Useful reporting is specific enough that another qualified team can understand the risk claim. What capability was measured? Under what access? With what tools? Against what failure modes? After what mitigations?
The third place is governance. This is where many standards die. Governance means somebody can say no, slow down a launch, narrow access, require more testing, or change the product surface. Without that, coordinated evaluation becomes a compliance ornament.
OpenAI is not neutral here. It is a leading model company with commercial incentives, policy interests, and real exposure if standards become stricter. That does not make the argument wrong. It does mean the standard-setting process cannot be owned by one lab, or by labs alone. If the standards are global, they need governments, independent researchers, enterprise deployers, civil society, and smaller builders at the table too.
What should builders watch for now?
The practical question is whether this becomes usable infrastructure or just policy language. Builders should care because standards tend to flow downstream. First they shape frontier labs. Then enterprise buyers start asking vendors for the same evidence. Then procurement teams, insurers, and regulators turn “best practice” into a checklist.
If you build with AI, especially agents or workflows that touch customer data, code, money, health, legal claims, or public content, start assuming you will need a basic evidence file. Not a 90-page safety report. A clear record of model choice, system prompts, tool permissions, eval cases, failure examples, human review points, and incident handling.
The catch most readers miss: shared AI standards will not remove judgment. They will move judgment earlier. Instead of arguing after an incident about whether a system was risky, teams will argue before launch about what risk class it belongs in, which evals count, and what level of reporting is enough. That is annoying. It is also healthier than vibes-based deployment.
Practitioner’s Take: Pick one important AI workflow and write down its standard today. What can the model see? What can it do? What tests would make you pause a launch? What failures would trigger rollback? Keep it small and concrete. The companies that do this early will not just be safer, they will ship faster when customers start asking for proof.