NarrativeBench tests whether AI search shows the stories it leaves out
NarrativeBench is a useful warning for AI search builders: multilingual answers can look balanced while still omitting competing narratives, especially when users ask confirmatory questions or switch languages.
TL;DR: NarrativeBench shows that LLMs are still weak at helping people compare contested narratives across languages, which matters if AI search becomes the front door to public information.
What does NarrativeBench actually test?
The primary source here is the arXiv paper “The Narrative Gap: Can LLMs Help Us Navigate Diverse Narratives Across Languages?”, listed in both cs.AI and cs.CL. Its core claim is narrow and useful: if people use LLMs to understand contested topics, the model should not just answer fluently. It should help users see which narratives are present, which are missing, and how coverage changes across languages.
That is a harder test than “did the model retrieve some relevant facts?”
The paper introduces NarrativeBench, built from 1,333 news articles, 23 publication languages, 23 contested topics, and 460 Reddit-grounded queries. The evaluation covers 14 LLMs across 24 query languages. The benchmark defines six capabilities: narrative inclusion, narrative exclusion, missing narrative identification, presenting diverse narratives, preserving narrative coverage under confirmatory queries, and maintaining information parity across languages.
That last pair is where this gets operational. A model may give a decent answer when asked neutrally, then collapse into a narrower frame when the user asks a leading question. It may also expose different narratives depending on query language. That is not just translation quality. It is information access.
Where do current models fall short?
The NarrativeBench results, as reported in the paper, are not flattering. Across the evaluated models, current LLMs lack the capabilities needed to reliably guide users through diverse narratives. Even when users explicitly ask for diversity, the models leave substantial gaps in exposure to competing accounts.
That matches a pattern I see in practical AI search work: the answer can feel fair because the tone is fair. But tone is not coverage. A calm summary can still exclude the most important disagreement.
The paper’s framing of “confirmatory queries” is especially important. Users rarely ask perfect neutral questions. They ask from a frame they already hold: “Why did X happen?” or “Isn’t Y caused by Z?” A useful information system should recognize the frame, answer the question, and preserve competing accounts rather than quietly narrowing the universe.
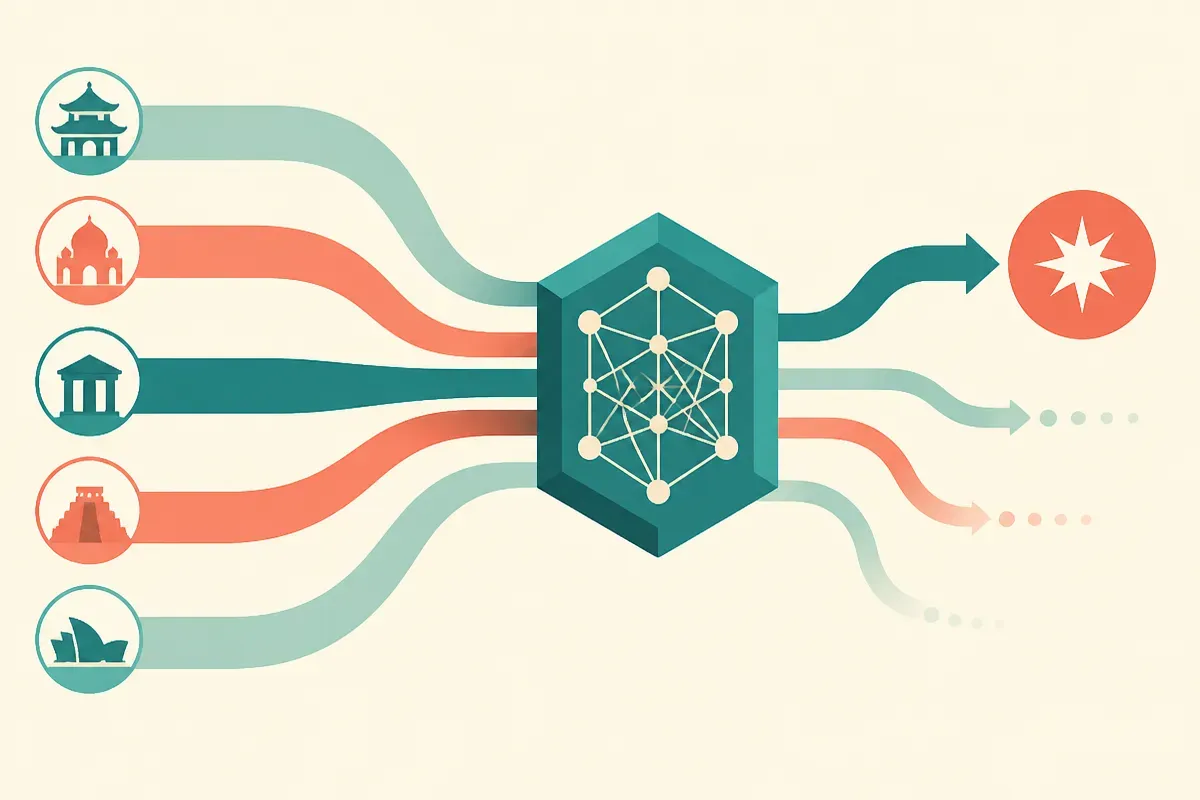
The multilingual point is just as serious. If an English query and an Arabic, Hindi, Spanish, or Japanese query surface different narrative sets on the same contested issue, the model is not giving everyone the same map. It is giving language-shaped maps. Sometimes that may reflect real differences in local media. Sometimes it may be a model artifact. The user cannot tell unless the system shows its work.
What should AI search builders take from this?
The easy response is to say “better evals.” True, but incomplete.
NarrativeBench is useful because it points toward product behavior, not just leaderboard behavior. AI search systems should be able to say: here are the major narratives found, here are the sources or regions they appear in, here is what this answer may be underrepresenting, and here is how the answer changes if we query across languages.
That does not mean every answer needs a political science seminar. Most queries do not. But for contested topics, especially news, health policy, war, elections, migration, climate, religion, or national identity, the interface should probably shift modes. Less single-answer confidence. More narrative map.
There is also a ranking problem. Retrieval systems often optimize relevance to the query. If the query is confirmatory, relevance can become agreement. A stronger system needs an explicit diversity objective, plus an audit trail for missing narratives. Not vague “both sides” theater. Actual coverage checks.
Practitioner’s take: if you are building AI search, RAG, or an internal research assistant, add a contested-topic path. Run the query in multiple phrasings, include at least one adversarial or disconfirming phrasing, and test whether the final answer preserves competing narratives instead of averaging them away. The catch most teams miss: multilingual coverage is not solved by translation. You need to check whether the model exposes different stories when the language changes.