MAEMs turn residual stream directions into testable text
A new activation inversion method generates text that lights up specific model internals, giving interpretability work a more testable path than corpus search or free-form natural-language explanations.
TL;DR: MAEMs are interesting because they turn hidden model directions into generated examples that can be checked with a forward pass, not just interpreted by vibes.
What problem are MAEMs trying to solve?
The primary source here is the arXiv paper “Towards interpreting any residual stream direction by scaling activation inversion,” listed under cs.AI and cs.LG. The core problem is simple to state and hard to solve: if you find a direction in a language model’s residual stream, what does that direction mean?
One common move is corpus search. Scan a pile of text, find snippets that activate the direction, then inspect those snippets. That is useful, but bounded by the corpus. If the relevant concept is rare, multilingual, domain-specific, or just not represented in your search set, you may get a bad read.
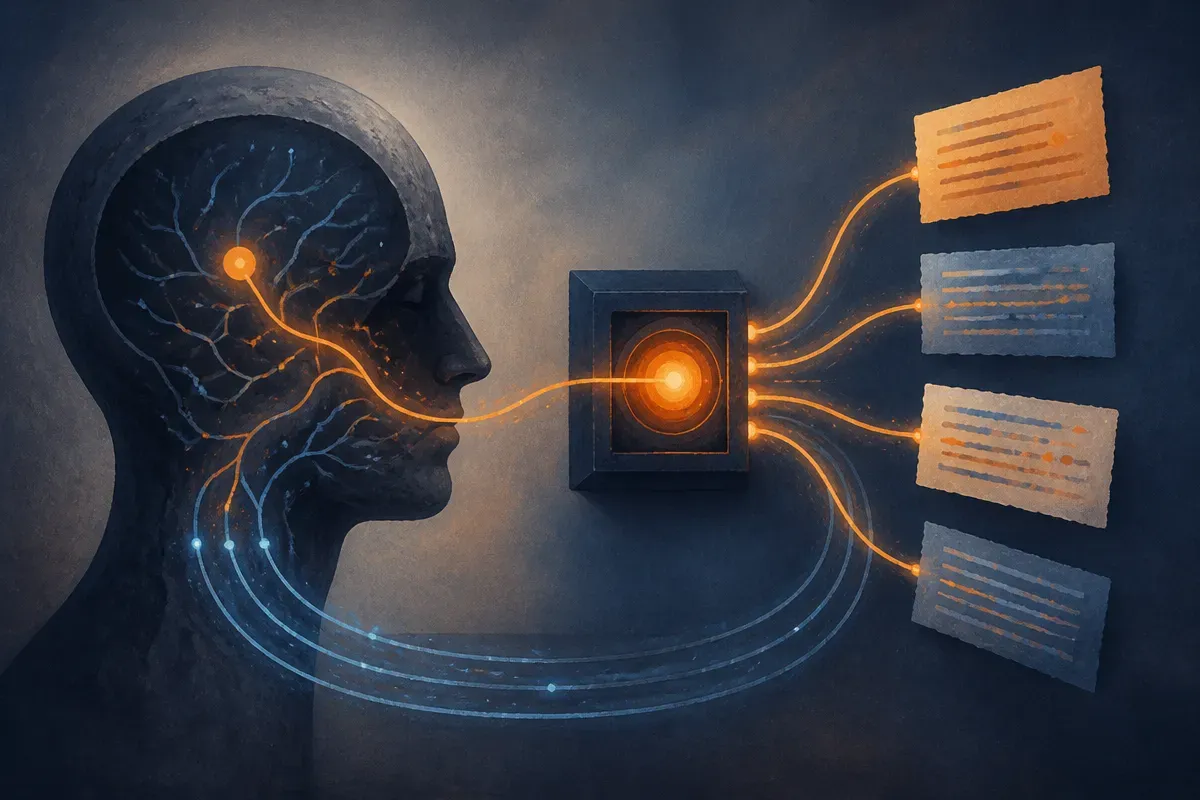
The paper proposes Maximally-Activating Example Metamodels, or MAEMs. A MAEM is itself a language model. It takes a residual stream direction from a subject model and generates text intended to strongly activate that direction. The training objective is label-free reinforcement learning: maximize cosine similarity between the supplied direction and the activations produced by the generated text.
That matters because the output is not just an English explanation. It is an input you can run back through the model. If the generated text lights up the target direction, you have a grounded check. Not proof of meaning. But a better test than “this explanation sounds plausible.”
Is this better than corpus search?
The paper reports that a Qwen3.6-27B MAEM inverted held-out activations better than corpus search and a natural-language autoencoder. It also reports that the MAEM beat corpus search over 10M tokens on a majority of held-out languages and domains, and activated 89% of held-out SAE features.
Those are meaningful claims because they point at scale. Interpretability often works in small controlled cases, then starts to fray when you ask it to cover many features, languages, domains, and weird internal directions. MAEMs try to make the search space generative instead of archival. Rather than asking “did my dataset happen to contain the right phrase,” the metamodel can synthesize candidates.
The paper also reports that MAEMs identify concepts behind steering vectors about as well as natural-language autoencoders, recover LoRA backdoor payloads more often than corpus search, and can verbalise some model workspace inner monologue.
That last phrase will attract attention, and it should be handled carefully. “Inner monologue” here does not mean we suddenly get a transcript of model consciousness. It means some internal working patterns can be prompted into text-like exemplars that activate the same direction. Useful, yes. Spooky framing, no.
What should builders take from this?
The real operator value is not “we can explain models now.” It is narrower and more useful: we may be getting better tools for turning internal signals into testable probes.
That could matter for model debugging. If a feature or residual direction correlates with unsafe behavior, hidden policy shortcuts, a memorized payload, or brittle reasoning, a MAEM-style tool could generate examples that trigger it. You could then inspect the examples, run them through evals, compare models, and see whether mitigation actually changes the activation pattern.
The catch is that generated exemplars are still artifacts of an optimization process. A MAEM can find text that activates a direction without fully capturing the human concept behind it. High activation is evidence. It is not a clean semantic label. Builders should treat these examples like diagnostic test cases, not final explanations.
I would try this first on boring but concrete problems: known backdoors, known refusal circuits, known domain features, known multilingual failures. Pick a direction, generate activating examples, verify them with a forward pass, then test whether the examples predict real behavior. If they do, you have a practical debugging loop. If they only look convincing, you have another interpretability demo wearing a lab coat.