Animal ID Models Need Evidence, Not Just Retrieval Scores
A paper on animal re-identification shows why retrieval accuracy is not enough: builders need evidence profiles that separate real foreground signal from background shortcuts, especially when datasets become shared benchmarks and foundation-model training fuel. The CFR protocol is a useful pattern for evaluating vision retrieval before leaderboard scores become fragile product claims.
TL;DR: Counterfactual evaluation makes animal re-identification more useful by showing whether a model recognizes the animal, or just the scene around it.
What does CFR test that accuracy hides?
The arXiv paper “CounterFactual Retrieval for Evidence-Aware Individual Animal Identification” puts a clean name on a common computer vision problem: a high retrieval score can be right for the wrong reason.
In animal re-identification, the task is usually query-gallery matching. Given one image of an animal, find the same individual in a gallery. That sounds straightforward until the model quietly learns that one zebra is usually near a certain bush, one whale is photographed from one boat, or one camera trap has a particular background. The score looks good. The evidence is suspect.
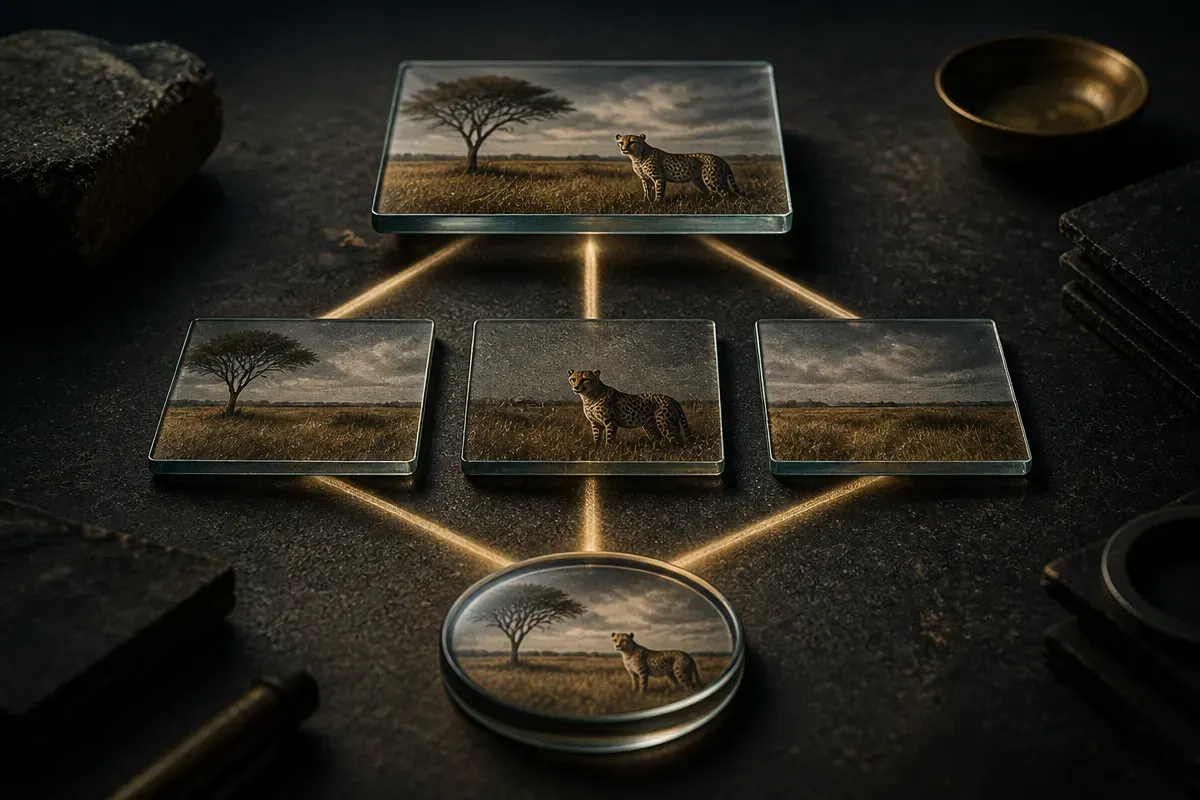
Counterfactual Foreground Retrieval, or CFR, evaluates the same retrieval task three ways. Full-image retrieval measures the normal benchmark result. Foreground-only retrieval asks how much performance remains when only the animal is visible. Shortcut-only retrieval asks how much identity signal is still recoverable from the background or silhouette after the animal itself is removed.
That turns one score into an evidence profile. Not “did it match?” but “what did it use to match?”
The paper reports the release of around 0.5 million masks across 34 datasets, plus code for mask generation and CFR evaluation. That matters because this kind of test is often discussed as a principle, then left as custom glue in one lab’s repo. Here, the contribution is partly the protocol, and partly the boring infrastructure that lets other people run it.
Why does this matter beyond animal identification?
Animal ID is a good testbed because the shortcut problem is easy to picture. But the pattern is everywhere.
Medical image models can pick up hospital-specific artifacts. Product recognition systems can learn packaging context instead of the item. Security cameras can associate people with locations. Satellite models can confuse geography with the object being detected. Retrieval systems are especially exposed because a model only needs enough correlated signal to rank one item above another.
The CFR framing is useful because it does not treat accuracy as fake. Full-image performance still matters. If a conservation team is trying to identify individual animals in the field, retrieval quality has operational value. The mistake is pretending the number explains itself.
This is where I think a lot of AI evaluation is headed. Less worship of a single aggregate score. More decomposition. What part of the input did the system depend on? What happens when that part is removed? Does the answer survive when the obvious shortcut disappears?
The animal ID setting also points to a bigger benchmark problem. As automated identification moves from small curated studies toward shared benchmarks and reusable foundation models, dataset quirks scale too. A shortcut that once affected one experiment can become baked into model selection, product claims, and downstream research.
How should builders use this pattern?
If you are building a vision retrieval system, CFR is less a wildlife-only method than a checklist for evidence-aware evals.
Start by defining the thing the model is supposed to recognize. Then create counterfactual views that remove or isolate it. For animals, that means foreground masks and background-only images. For retail, it may mean product crop versus shelf context. For industrial inspection, it may mean defect-only crop versus machine-line background. The goal is not a perfect philosophical separation. The goal is to catch the dumb failure before it becomes a confident demo.
The catch: counterfactual evals can reveal uncomfortable truths without telling you the fix. If shortcut-only retrieval is strong, you still need better splits, better data collection, masking, augmentation, or training objectives that punish context dependence. CFR gives you the smoke alarm, not the fire department.
Practitioner’s take: before trusting any retrieval benchmark, run at least one “object removed” and one “context removed” evaluation. If the model performs well when the target evidence is missing, do not ship the claim as recognition. Ship the system only after you can say what signal it is using, where it fails, and whether that failure matters in the real workflow.