Hide and Seek tests black-box vision models by removing the thing you care about
Hide and Seek is a concept attribution method for black-box vision systems that asks a practical question: if we hide a human-readable concept in the image, does the model’s output change in the way we expect?
TL;DR: Hide and Seek is useful because it explains black-box vision models by testing behavior directly, not by asking for weights, gradients, or a perfectly labeled concept dataset.
What does Hide and Seek actually test?
The primary source here is the arXiv cs.AI/cs.LG paper “Hide and Seek: HIDE Concepts to SEEK explanations for black box models.” It proposes HnS, a concept-level attribution method for vision models where you do not need access to model weights or a large concept-annotated dataset.
That matters because a lot of real systems are black boxes now. You may be calling a vision API. You may be evaluating a vendor model. You may have an internal model where the team using it does not control training. In all of those cases, classic interpretability methods that need internal activations, weights, or gradients are dead on arrival.
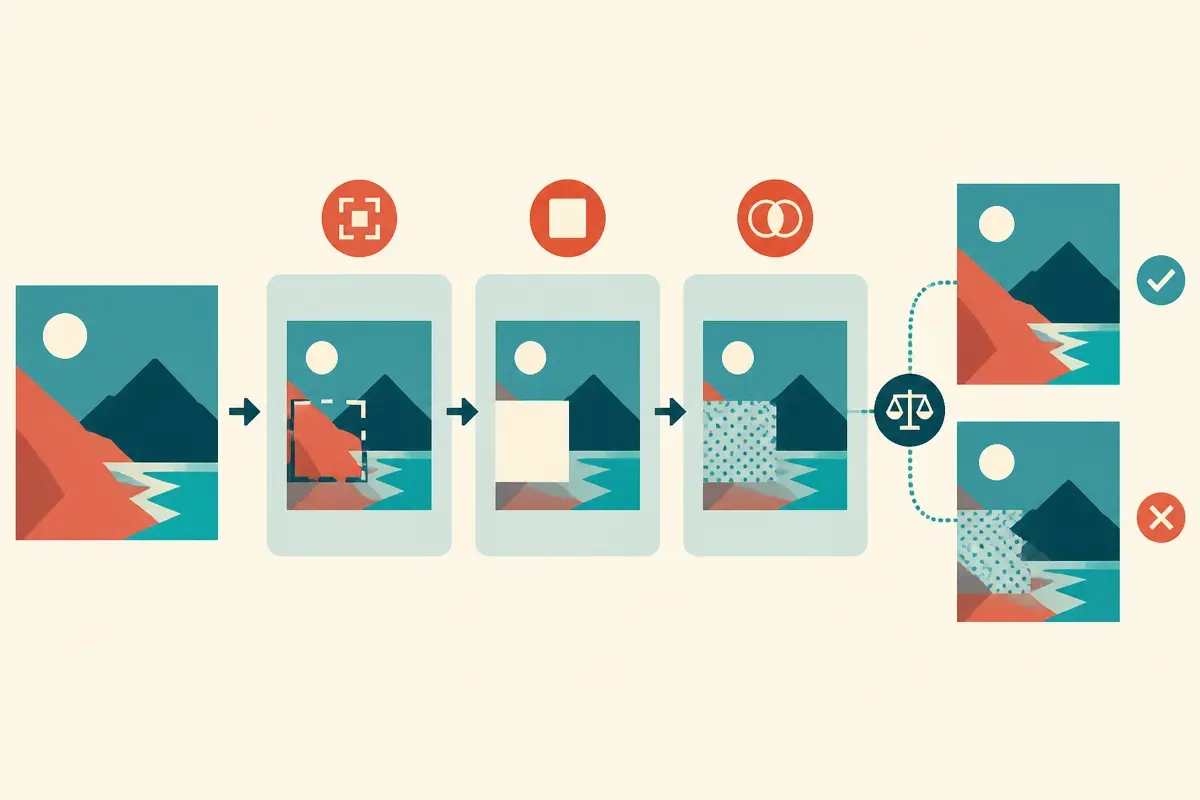
HnS takes a more operator-friendly route. Given a concept and a set of images, it uses a vision-language model to retrieve images aligned with that concept. Then it localizes the concept inside each image. Then it masks that region. Finally, it measures how much the black-box model’s output changes between the original image and the masked image.
That last step is the key. The method does not just say, “This region looks related.” It asks, “When this concept is hidden, does the model behave differently?”
Why is this different from older concept attribution work?
The arXiv paper frames the gap plainly: existing concept-based methods are mostly built for classification and regression models, often require model internals, and usually cannot provide image-level attribution.
HnS is aimed at a broader class of vision tasks. The paper reports validation on CelebA and COCO-Stuff, with better agreement with ground-truth attributions than existing methods. It also demonstrates HnS on image captioning and satellite image segmentation, two settings where the paper says existing concept attribution methods cannot be used.
That is the interesting part to me. Not that it “solves interpretability.” It does not. The useful shift is that HnS treats explanation as an intervention. Hide the concept. Re-run the model. Measure the change.
For builders, that is much closer to how debugging actually works. If a satellite segmentation system marks an area as flooded, you might ask whether “water,” “roof,” “shadow,” or “vegetation” is driving the result. If an image captioner mentions “helmet,” you might ask whether the model found the helmet or inferred it from a bike, uniform, or scene context. HnS gives a structured way to run those tests without cracking open the model.
Where can this go wrong?
There are real caveats.
First, HnS depends on the vision-language model used to retrieve and localize the concept. If that helper model has weak concept grounding, your explanation pipeline inherits that weakness. The black-box model may be the target, but the explanation stack is not neutral.
Second, masking is not a clean intervention. Covering part of an image can create unnatural inputs. A model may react to the mask itself, not only to the missing concept. Good experiments need careful mask design and baselines.
Third, the choice of image set matters. A concept like “snow” may mean background in one dataset, weather in another, and terrain risk in a satellite task. Attribution is not just a property of the model. It is also a property of the distribution you test against.
Still, I like the direction. Interpretability work often gets stuck between pretty heatmaps and methods that require access most users do not have. HnS sits in the middle: black-box compatible, concept-based, and tied to actual output changes.
Practitioner’s take: if you run vision models in production, try this pattern as an evaluation harness before treating it as an explanation engine. Pick 5 to 10 concepts that matter to your workflow, build a small image set, mask each concept, and compare output changes. The catch most teams miss is concept selection. If you only test obvious objects, you will miss the spurious cues that cause real failures, like shadows, backgrounds, uniforms, borders, reflections, or image quality.