Verifying Computer-Use Agents by Letting the Verifier Go Look
VeriCUA reframes task verification for computer-using agents as active exploration instead of passive judgment, and that shift matters more for anyone training or evaluating agents than the benchmark numbers suggest.
TL;DR: VeriCUA checks whether a computer-using agent actually finished a task by having the verifier actively explore the environment and gather evidence, instead of reading a fixed screenshot or guessing from accessible state, and that one design change fixes the quiet failure mode that poisons agent training and evals.
The paper is “VeriCUA: Verification as Agentic Exploration for Computer-Using Agents,” posted to arXiv under both cs.AI and cs.CL. I want to walk through why this is a bigger deal than it looks, because verification is the unglamorous bottleneck in the whole computer-using-agent stack right now.
Why does verifying an agent’s work turn out to be the hard part?
Here is the setup. A computer-using agent (CUA) is a model that drives a desktop, a phone, or a browser: clicking, typing, scrolling, filling forms, navigating apps. To build these at scale you need three things that all depend on one shared skill. You need to curate training data (keep the good trajectories, drop the bad ones). You need to evaluate (did this run succeed?). And if you want reinforcement learning, you need a reward signal (was the task completed?). All three reduce to the same question: did the agent actually do what was asked?
That sounds trivial until you try to automate it. The two standard approaches both work from a partial view of the environment, which is exactly where they break.
The first approach prompts a vision-language model to judge the trajectory. You show the VLM the screenshots and the actions and ask: success or not? The problem the authors flag is that the VLM is “restricted to supplied observations.” It only sees what it was handed. If the decisive evidence lives on a screen nobody captured, or in a confirmation dialog that scrolled off, the judge is guessing.
The second approach generates a program to inspect application state: query the database, check the file, read the DOM. More rigorous, but it “depends on accessible state.” If the thing you need to verify is not reachable through the API or the accessibility tree, the check comes back empty or wrong.
So both methods look at a sliver of a complex digital world and render a verdict on the whole thing. And there is a second cost the paper names: you end up building separate verifiers for each platform and each access setting. A desktop verifier, a mobile verifier, a web verifier, one for when you have state access, one for when you do not. That is a lot of engineering to maintain, and every one of them inherits the partial-view problem.
What does VeriCUA actually do differently?
The reframe is in the title: verification as agentic exploration. Instead of handing the verifier a fixed set of observations and asking for a judgment, VeriCUA lets the verifier go look for the evidence it needs.
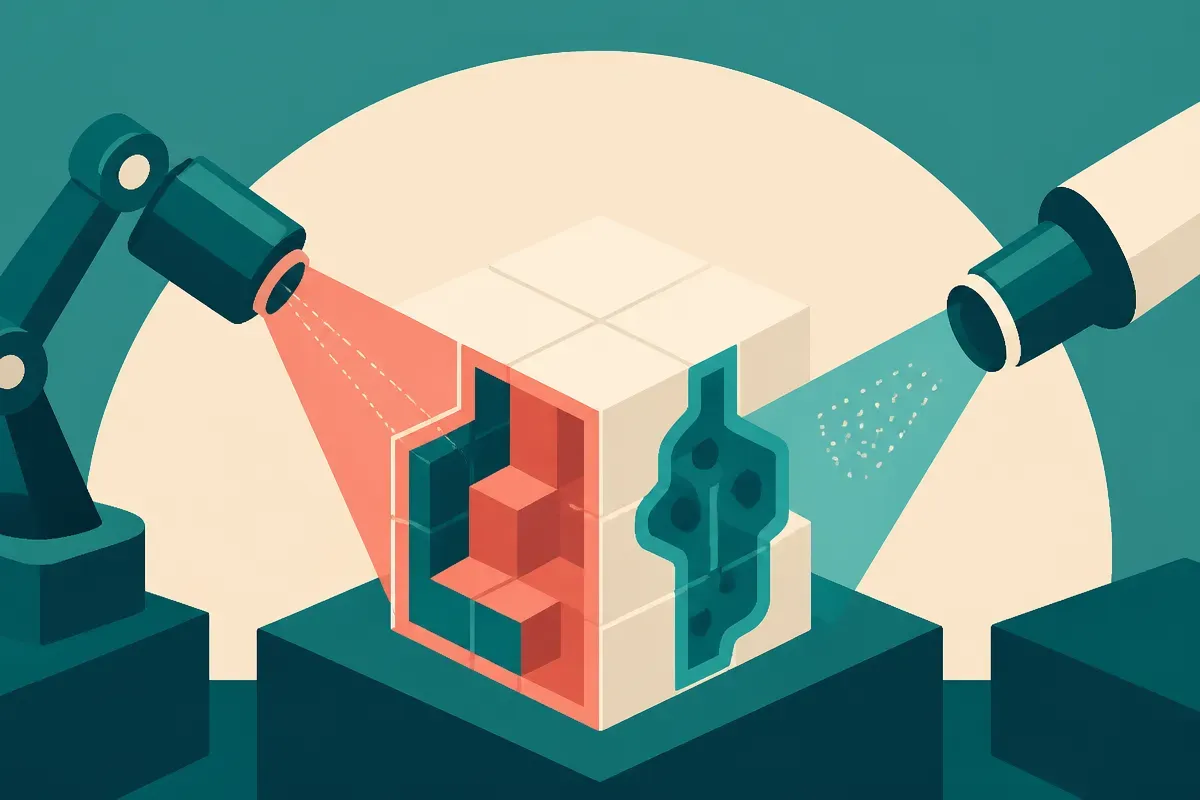
The procedure, as described: the verifier first inspects the available context to construct a task rubric, the set of requirements the agent was supposed to satisfy. Then, for each unresolved requirement, it chooses how to check it. It can run a GUI check (navigate the interface to confirm something visually) or a code check (inspect state programmatically). It combines those findings under explicit evidence rules rather than vibing a conclusion.
Two things stand out to me here.
First, it is one shared procedure across online and offline settings, across platforms, across observation modalities. That directly attacks the “build a separate verifier for everything” tax. The verifier is platform-agnostic because exploration is platform-agnostic: you are not hardcoding what evidence looks like, you are describing how to go find it.
Second, mixing GUI and code checks is the whole point. A VLM-only judge cannot query hidden state. A program-only check cannot see a rendered confirmation that never touches the database. VeriCUA uses both and lets them cover each other’s blind spots. The paper calls this “complementary evidence,” and the ablations tie the gains specifically to that complementarity plus test-time exploration. In other words, the improvement is not from a smarter single judge. It is from letting the verifier do more work at check time.
Where do the gains actually show up?
I want to be careful here, because the abstract gives directions and shapes, not a results table. What it claims: improved agreement with reference labels over the compared baselines, across online and offline settings. The largest offline gains are on hard cases. And online, the standout is “stronger rejection of false completion claims.”
That last one is the result I would stare at if I were reviewing this. False completion claims are agents reporting “done” when they are not done. In an eval, a false positive inflates your success rate and tells you the agent is better than it is. In an RL loop, a false positive is a corrupted reward: you are literally training the model to believe a half-finished task counts as a win. That is how you teach an agent to declare victory early, confidently. A verifier that is better at calling out fake completions is attacking the single most damaging error in the pipeline.
The honest caveats: the abstract names “the compared baselines” without, in what I have, naming them or giving magnitudes. “Improved agreement” and “largest gains on hard cases” are the right direction but I cannot tell you by how much from this material, and I am not going to invent a number. Treat the numbers as unverified until the full tables are in front of you. What I can evaluate is the design logic, and the design logic is sound: partial views cause bad verdicts, so give the verifier the ability to gather more of the view on demand.
What should a builder take from this?
If you run agent evals or an RL pipeline, the practical move is to stop treating verification as a single-shot judgment and start treating it as a budget. The lesson underneath VeriCUA is that spending compute at check time, letting the verifier explore, run a GUI probe here, a state query there, and combine them, buys you accuracy that no cleverer single prompt will. Before you reach for a bigger judge model, ask whether your verifier is even allowed to go look at the evidence it needs, or whether it is stuck grading whatever screenshots happened to get logged.
The specific thing to audit first is false positives, not overall accuracy. Pull a sample of runs your current verifier marked “success” and check them by hand. If your verifier is a VLM reading a trajectory, I would bet a meaningful slice of those are false completions where the decisive evidence was off-screen or in state the judge never queried. Those are the runs quietly poisoning your reward signal and inflating your leaderboard. A mixed GUI-plus-code verifier with explicit evidence rules is the direct fix.
The catch most readers will miss: agentic verification costs more per check, and it introduces its own exploration policy that can itself be wrong or wander. You are moving the hard problem, not deleting it. The verifier now needs to decide what to check and when it has enough evidence, and a verifier that explores badly can be as misleading as one that cannot explore at all. The win is real, but you are trading a cheap, lazy judge for a more expensive, more capable one that needs its own evaluation. Verify your verifier before you trust it to grade your agents.