SpecSlot splits image tokens by what needs global attention
SpecSlot is a pixel-space generative Transformer design that keeps global attention focused on low-frequency structure while modeling fine detail locally. The useful idea is not just better image scores, it is a cleaner way to spend compute where it matters.
TL;DR: SpecSlot shows a practical path for image generators: send broad structure through expensive global attention, keep fine detail mostly local, and stop paying full Transformer cost for every extra bit of texture.
What problem is SpecSlot trying to solve?
The primary source is the arXiv paper “Read, Allocate, Route: Role-Coupled Tokenization for Pixel-Space Generative Transformers,” posted under cs.AI and cs.LG.
The problem is familiar if you have watched image models scale. Pixel-space generative Transformers usually map image patches to tokens. Want sharper output? Use more tokens, smaller patches, or denser representations. But then global attention gets expensive fast, because every token can talk to every other token.
That is overkill for a lot of image detail.
A face, a room layout, a car silhouette, or a horizon line benefits from global coordination. The model needs to know what belongs where. But pores, fabric texture, grass, brick patterns, and small edges are often local. They need detail, not full-image discussion.
SpecSlot takes that split seriously. It expands each spatial anchor into multiple “slots,” and each slot owns a different band of DCT coefficients. DCT is the same broad family of frequency decomposition ideas behind classic image compression. Low-frequency components capture broad structure. High-frequency components carry finer detail.
The key move: only the lowest-frequency slot from each anchor enters global attention. The other slots interact locally. So the model can add spectral detail without making the global sequence longer.
That is the whole bet. Not more tokens everywhere. More role-specific tokens, routed differently.
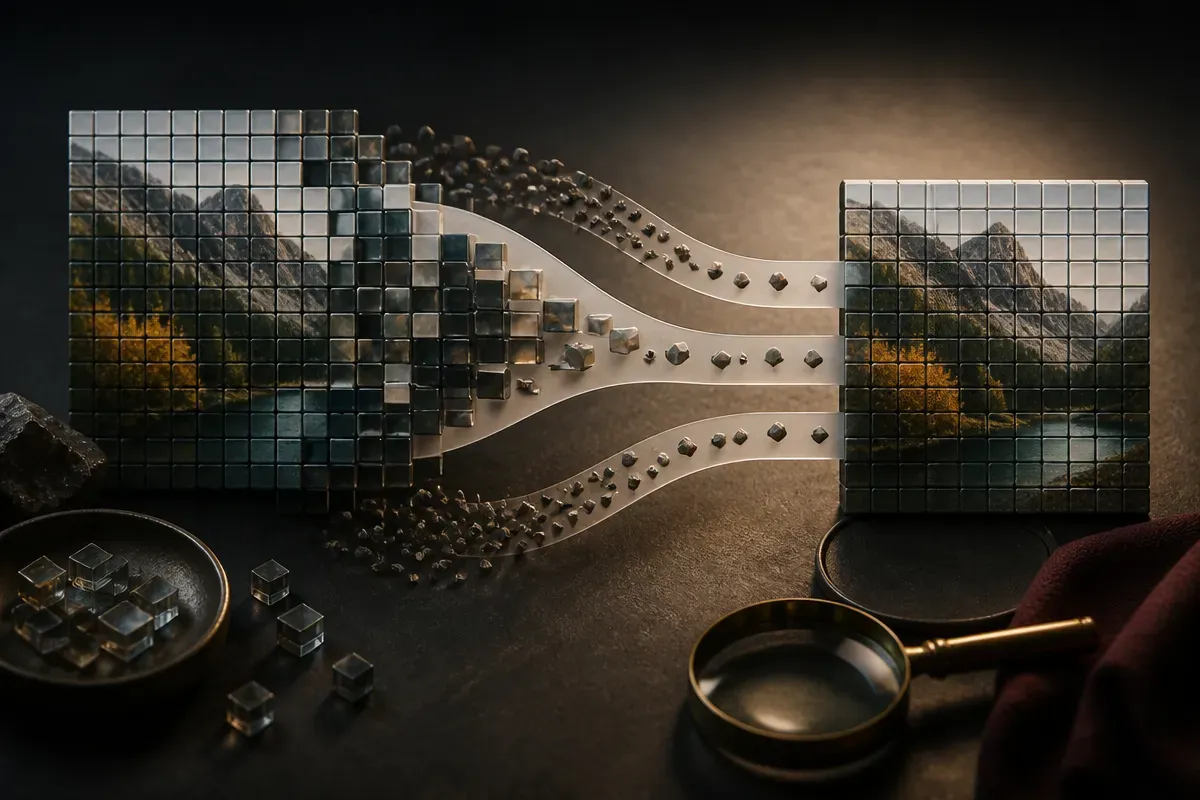
Why does routing frequency bands matter?
This is a compute allocation paper as much as an image generation paper.
SpecSlot keeps the generative state, target, and loss in pixel space, but uses spectral subdivision to decide what needs global communication. It also adds a spatial head for local correction, which matters because frequency decomposition alone is not a magic replacement for spatial modeling.
The reported results are strong enough to pay attention to, without treating this as settled.
On ImageNet-256, SpecSlot reaches a comparable final FID to a FLOPs-matched JiT control while converging faster. On ImageNet-512, it improves FID by 2.84 over the control with 3.9% fewer FLOPs. It also comes within 0.69 FID of JiT-B/16 at 38.2% lower cost. For text-to-image generation, the paper reports that SpecSlot beats JiT-B/8 on DPG-Bench by 1.06 at 40.6% lower forward cost.
Those numbers point to a useful pattern: cheaper attention does not have to mean less detail. It can mean different communication rules for different kinds of detail.
That matters because attention cost is one of the quiet constraints behind image and video generation. Everyone likes talking about parameter count, but the operator question is simpler: how much useful image quality do I get per unit of training and inference cost?
If SpecSlot’s idea transfers beyond the paper’s settings, it could help pixel-space models compete more directly with latent approaches. Pixel-space generation has appeal because it avoids some lossy abstraction. But it often pays for that with cost. SpecSlot says: keep pixel-space supervision, but stop pretending every detail needs the same network pathway.
What should builders take from this?
I would not read this as “SpecSlot beats everything.” The benchmarks are specific. FID is useful, but imperfect. DPG-Bench helps on text-to-image alignment, but no single benchmark captures taste, prompt faithfulness, artifact rate, speed, memory behavior, and production reliability.
The bigger takeaway is architectural: separate what needs global reasoning from what only needs local refinement.
That idea travels. Image generation is the obvious case, but the same pattern shows up in video, 3D, audio, and long-context language systems. Not every token deserves the same attention budget. Some tokens carry scene structure. Some carry texture. Some carry bookkeeping. Some are local cleanup. Treating them equally is simple. It is not always smart.
For model builders, SpecSlot is a reminder to look at token roles before adding scale. For product teams, it is a reminder that cost improvements often come from architecture, not just distillation or smaller checkpoints. For anyone buying API inference, it hints at where the next generation of cheaper visual models may come from: less brute-force attention, more routing.
Try the idea at the system level even if you are not training image models. Split broad planning from local execution. Give global context to the parts that need it, then constrain the rest. The catch most readers miss is that “more detail” and “more global context” are not the same requirement. SpecSlot is useful because it makes that distinction concrete.