Pixel diffusion gets a smarter prediction target
MFlow is a useful reminder that image generation quality is not only about bigger backbones. The prediction target, data representation, and small post-training refiners can change what a diffusion transformer learns, especially when generating directly in pixel space.
TL;DR: The useful idea in MFlow is not “pixel diffusion is back,” it is that diffusion models may need prediction targets that adapt to the data and model size instead of one fixed training recipe.
Why does pixel-space diffusion matter again?
The arXiv cs.AI paper titled “Rethinking the design space of Vanilla Pixel Diffusion Transformers” looks at a question that keeps coming back in image generation: should diffusion models generate in a compressed latent space, or directly in pixel space?
Latent diffusion won the practical era because it is cheaper. Compress the image through an autoencoder, run diffusion in that smaller representation, decode back to pixels. That made systems like Stable Diffusion possible at useful speeds and costs.
But compression has a cost. A separately trained autoencoder can throw away detail, introduce artifacts, or shape what the diffusion model can learn. Pixel-space diffusion avoids that bottleneck. The model works directly on the image. Cleaner conceptually, harder computationally.
JiT, which the paper builds from, showed that a vanilla diffusion transformer can work in pixel space by switching from velocity prediction, often called u-prediction, to clean image prediction, or x0-prediction. That is a pretty specific knob, but it matters. The target you ask the model to predict changes the training dynamics.
The MFlow paper argues that this should not be a fixed choice.
What does MFlow actually change?
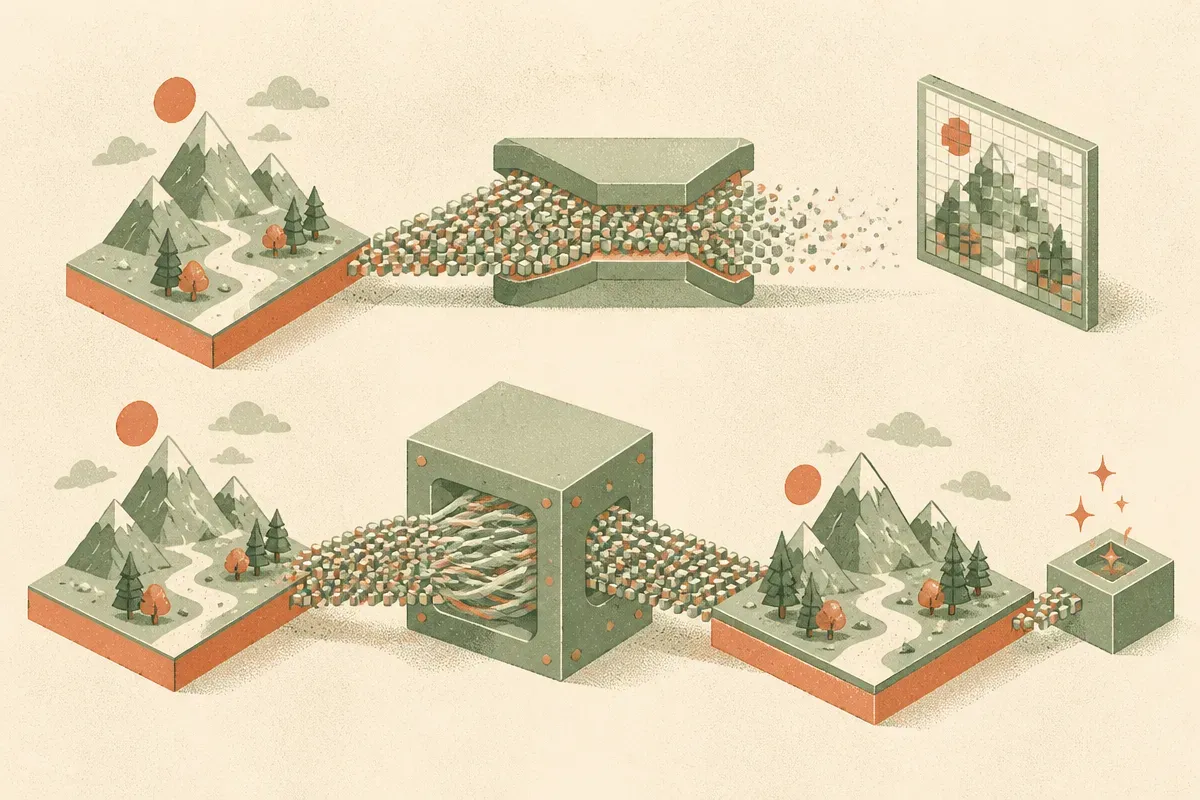
MFlow is an adaptive parameterization. Instead of deciding upfront that the model should predict x0 or velocity, it learns to interpolate between the two across principal directions of the data. That interpolation is trained end-to-end with the diffusion model.
That sounds abstract, but the practical read is simple: different parts of the data distribution may want different prediction behavior.
The paper reports that the preferred parameterization varies with both the data representation and the model capacity. One finding stood out to me: as model capacity increases, the preference shifts toward velocity prediction. That is a useful warning against taking a trick that works at one scale and treating it like law.
The evaluations cover ImageNet, UCF-101 video, and large-scale text-to-image generation. The reported result is competitive or improved generative performance across those settings. I would not overread that as “pixel diffusion now beats latent diffusion everywhere.” The paper is narrower and more useful than that. It says the design space inside vanilla pixel diffusion transformers is not settled, and the prediction target is one of the live wires.
There is also a second, very operator-relevant result: vanilla pixel diffusion transformers still show a persistent high-frequency deficit versus real images, regardless of parameterization. In plain English, the samples can miss fine texture and crisp detail.
That is where ConvRefiner comes in. The paper introduces it as a lightweight convolutional module trained after the fact with an adversarial loss, while keeping the diffusion backbone frozen. With a small amount of extra training, ConvRefiner restores high-frequency statistics while preserving FID, according to the paper.
That setup matters. Freezing the backbone means the refiner is more like a targeted post-training patch than a full retrain. For builders, that is the interesting pattern.
What should builders take from this?
My main takeaway is that “better model” can mean three different things here: a better representation, a better prediction target, or a better final correction stage.
Most product teams only think about the first one. They pick a base model or API and move on. Research like MFlow is a reminder that the training objective can be just as important as the architecture. If you are building image or video systems, especially anything where texture, typography-adjacent detail, surfaces, or motion realism matters, you should care about what the model is actually trained to predict.
The ConvRefiner piece may be the more near-term idea. A small frozen-backbone refiner is easier to imagine in applied systems than retraining a giant diffusion transformer. You can picture domain-specific polishers for product photos, medical imagery, game assets, satellite images, or video frames, assuming the evaluation is honest and the refiner does not hallucinate detail that users mistake for ground truth.
Try this as a builder: separate your generation pipeline into backbone quality and finishing quality. Test for high-frequency failures directly, not just prompt satisfaction. Use human review, frequency analysis if you have the skill, and task-specific checks. The catch most readers miss is that a prettier refiner can improve texture while making factual fidelity harder to judge. For creative work, that may be fine. For inspection, documentation, or scientific imagery, it is a risk you need to measure before shipping.