Hugging Face points open AI back at the iPhone
Hugging Face’s AnySpeechRecognizer and AnyDecisionModel announcement is less about one model drop and more about a practical shift: open models that run close to users, on Apple hardware, for speech input and local decision workflows.
TL;DR: Hugging Face’s Apple-platform model announcement is a reminder that useful AI may move less through giant chat boxes and more through small, local components embedded in apps.
What did Hugging Face announce?
The primary source here is Hugging Face’s own announcement, “Introducing AnySpeechRecognizer and AnyDecisionModel: Open Models for Speech and Decisions on Apple Platforms.”
The important part is in the names. Hugging Face is presenting two open models, AnySpeechRecognizer and AnyDecisionModel, aimed at Apple platforms. One points at speech. The other points at decision workflows. Together, they sketch a different path from the default “send everything to a frontier model API” pattern.
That matters because Apple devices are where a huge amount of personal computing actually happens. Phones, laptops, tablets, watches. The AI layer on those machines does not need to be one giant assistant. It can be a set of smaller pieces: recognize speech, classify intent, pick an action, route a task, summarize a short local context, decide whether to ask the user for confirmation.
This is not the same claim as “local AI replaces cloud AI.” It does not. The largest models still win on many hard reasoning, coding, and research tasks. But a lot of product AI is not that. A lot of it is input handling and workflow control. If those parts can run locally, open, and close to the interface, builders get a different design space.
Why do speech and decisions belong together?
Speech recognition by itself is useful. Decision modeling by itself is useful. Paired together, they become an interface primitive.
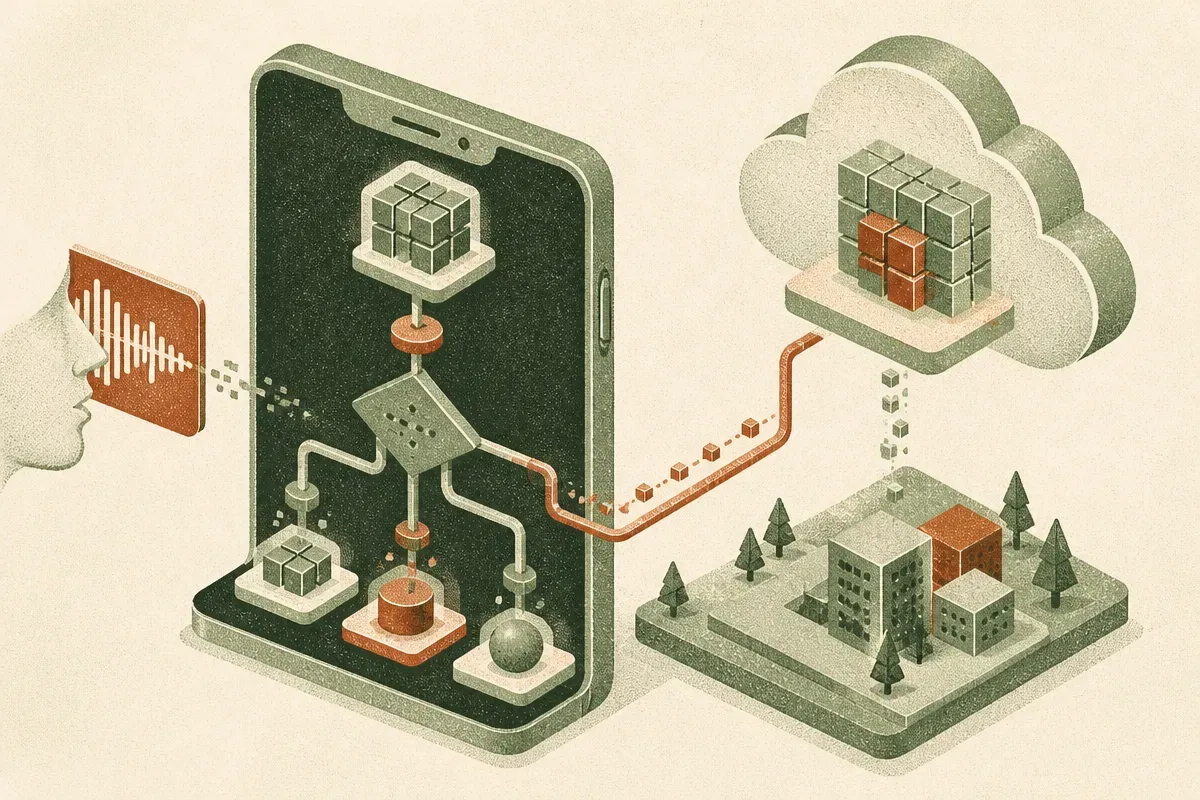
A voice command is rarely just transcription. “Remind me to call Maya when I leave” is not only words. It contains intent, entities, timing, location, permissions, and a follow-up action. The app has to decide what to do with the recognized speech. It may need to ask a clarifying question. It may need to reject a request. It may need to route the task to Calendar, Reminders, Maps, or a private backend.
That is why I like the pairing in Hugging Face’s announcement. It frames voice AI as more than dictation. The output is not just text. The output is a next step.
This is where smaller open models can be more interesting than people give them credit for. A local speech recognizer does not have to be the best general model in the world to be useful inside a constrained app. A decision model does not have to solve philosophy to choose between “save draft,” “send for review,” and “ask user.” Tight scope changes the bar.
The catch is evaluation. Builders should not ask, “Does this feel smart?” They should ask, “Does it make the right routing choice 99 times out of 100 on the commands my users actually give?” That is a much better test, and a much harsher one.
What changes for builders on Apple platforms?
The practical shift is latency, privacy shape, and product control.
Local speech can feel faster because the app is not waiting on a round trip for every interaction. It can also reduce what needs to leave the device, depending on how the app is built. That is not automatic privacy. Local models can still be wrapped in bad data collection. Cloud calls can still be designed responsibly. But on-device inference gives builders an option they did not always have.
Open models also change the dependency story. If a key workflow relies only on a closed hosted API, the product inherits that provider’s pricing changes, downtime, moderation choices, model changes, and roadmap drift. Open local components do not remove maintenance. They add it. But they also give teams more control over packaging, fallback behavior, and domain-specific testing.
I would not read Hugging Face’s announcement as a finished answer to Apple Intelligence, Siri, or any one assistant product. The better read is modular. Speech in. Local decision layer. Cloud model only when needed. Human confirmation when risk is high.
For a builder, the move is simple: pick one narrow voice workflow in an app and prototype it as a local pipeline. Speech recognition first. Then an explicit decision step with a small set of allowed actions. Log failures. Test accents, background noise, interruptions, and weird phrasing. The part most readers miss is that the decision model is where trust breaks, not the transcript. A perfect transcript that triggers the wrong action is still a bad product.