LongZero trains long-context reasoning without outside documents
LongZero is interesting because it attacks a practical bottleneck in long-context model training: getting long, hard, checkable tasks without relying on human annotation, external corpora, or stronger teacher models.
TL;DR: LongZero points to a useful training pattern: make the model generate compact, verifiable reasoning tasks first, then expand them into long contexts for reinforcement learning.
What problem is LongZero trying to solve?
The primary source is the arXiv paper titled “LongZero: Enhancing Long-Context Reasoning in LLMs from Zero Data,” listed under cs.CL and cs.LG. The claim is narrow but important: reinforcement learning can improve long-context reasoning, but the data pipeline is the bottleneck.
That tracks with what builders see in practice. Long-context models are easy to demo and hard to trust. A model can ingest a giant pile of documents, then still miss the one sentence that matters, blend two facts from different sections, or answer confidently from the wrong part of the context.
Training against that failure mode needs examples that are long, diverse, challenging, and verifiable. Each part is annoying. Long examples cost more to create. Diverse examples require breadth. Challenging examples cannot be solved by shallow keyword matching. Verifiable examples need answers that can be checked without another vague model judgment.
LongZero’s pitch is that external data may not scale cleanly. Human annotation is expensive. Naturally occurring long-context tasks are scarce. Synthetic data from external corpora or stronger teacher models gets harder as the target model improves. If your training recipe depends on a better model teaching a worse one, eventually you hit the teacher supply problem.
How does the zero-data trick work?
LongZero does not start by asking a model to write questions over existing documents. That matters.
According to “LongZero: Enhancing Long-Context Reasoning in LLMs from Zero Data,” the method first has the model synthesize the question, answer, and supporting evidence in a compact structured form. Only after that does it expand the evidence into a long multi-document context.
That order is the clever bit. If you generate the long documents first, you can lose control of the answer. If you generate the reasoning skeleton first, you know what evidence is supposed to support the answer before the context gets inflated.
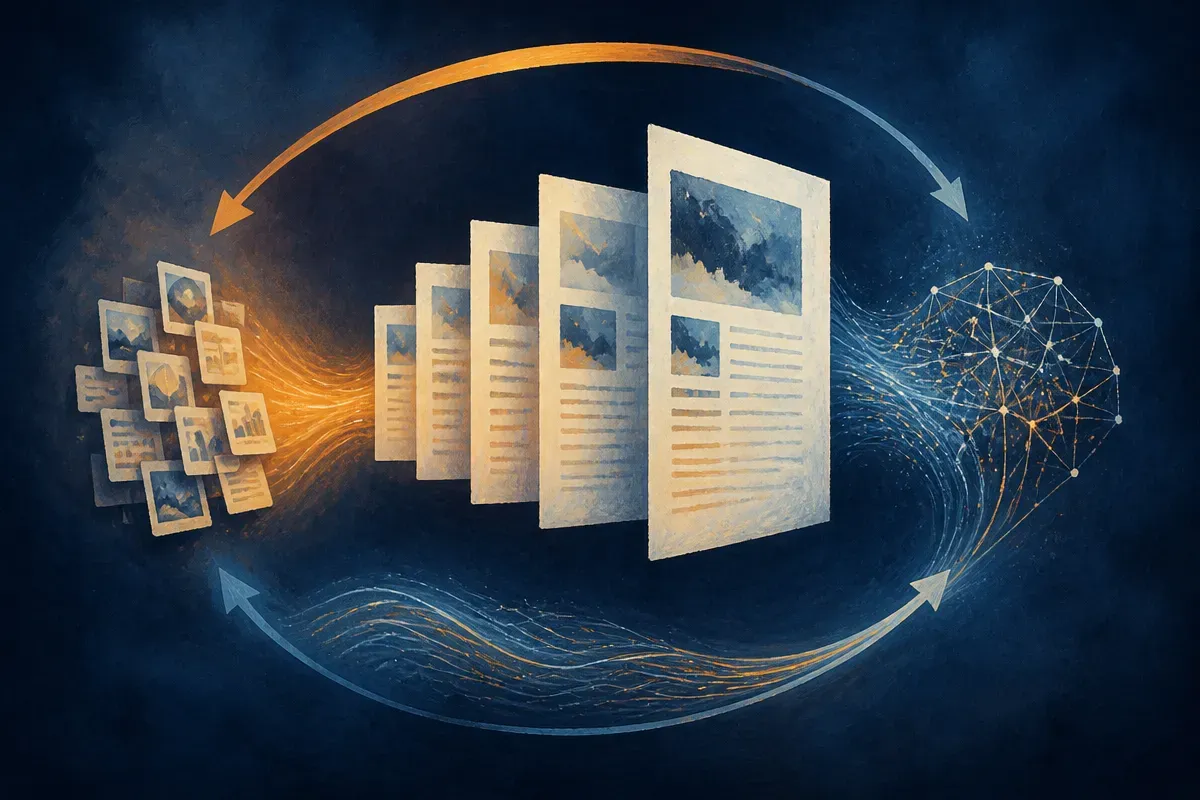
The paper combines self-written multi-hop reasoning tasks with self-written multi-round retrieval tasks, then trains with GRPO. The abstract says LongZero was evaluated on two LLMs across five long-context reasoning benchmarks and compared with reinforcement learning on data synthesized from external corpora. It reports that LongZero generalized to real tasks and outperformed both baselines.
That is promising. It is not yet enough to treat this as settled. The provided abstract does not name the two models, the five benchmarks, the baseline details, or the size of the gains. Those details matter a lot. Long-context benchmarks can be gamed by data format, retrieval shortcuts, or answer patterns. I would want to see whether the gains hold on messy enterprise-style corpora, not just benchmark suites.
Why should builders care?
The useful idea is not “models can teach themselves everything.” That is the hype version.
The useful idea is staged synthetic task creation. First create a compact ground truth structure. Then expand it into the messy form the model will face at inference time. Then train or evaluate against the original structure.
That pattern applies outside frontier model training. If you are building a RAG system, you can create synthetic test cases by first defining the answer, citations, distractors, and required reasoning steps. Then you can expand those into realistic documents, policies, tickets, transcripts, or product pages. The key is not generating more text. The key is preserving checkability while adding context noise.
This is where “zero data” needs a sober read. LongZero may not need external documents for its training tasks, but it still depends on the base model’s existing knowledge and generation ability. Self-generated tasks can inherit blind spots. They can also become too neat. Real customer documents are ugly: duplicates, contradictions, outdated policies, screenshots, tables, missing metadata, and weird naming conventions.
For builders, I would try the LongZero shape before copying the exact training method. Build a small eval set where each item starts as a compact evidence graph, then gets expanded into long documents with distractors. Test whether your model can recover the answer and cite the right evidence. The catch most readers miss: long-context quality is less about fitting more tokens and more about making the model practice finding the few tokens that actually matter.