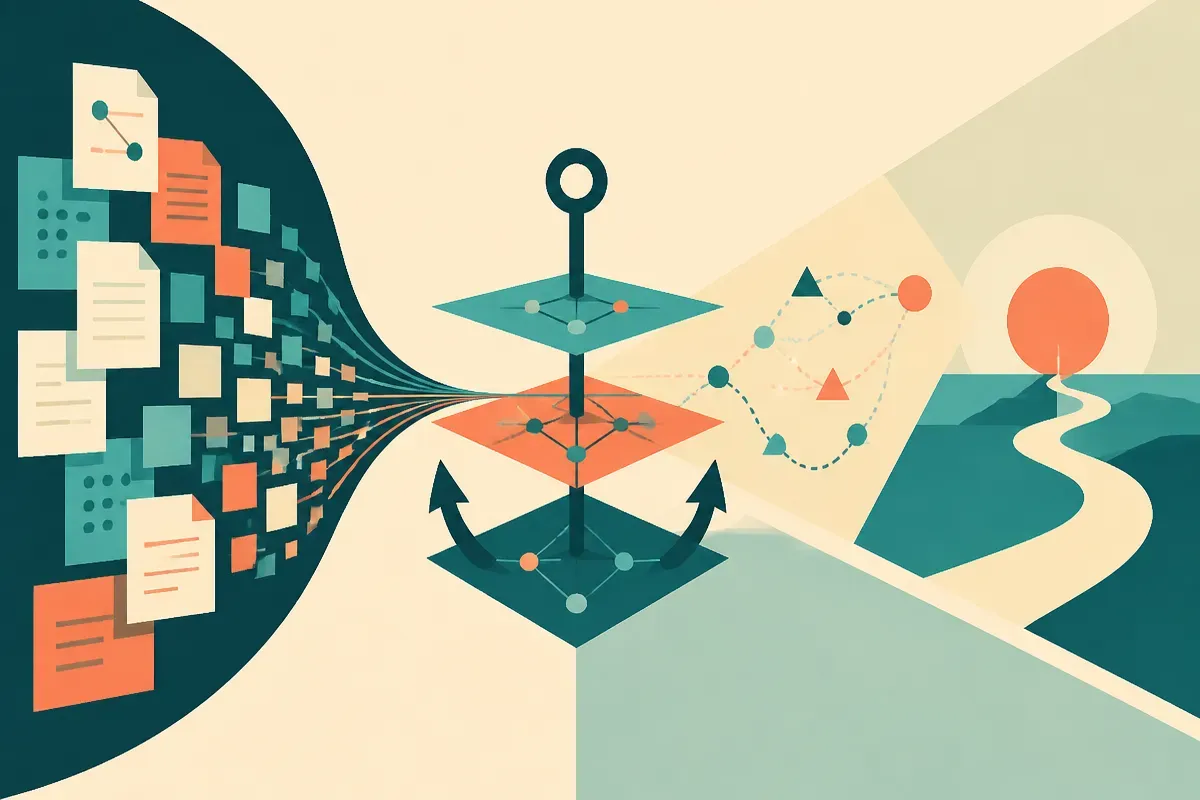
IdeaAnchor Trains Models on the Shape of Research Ideas
IdeaAnchor points to a practical shift in AI research assistants: stop asking models to brainstorm from papers, and train them on the hidden structure that turns prior work into a credible new direction.
TL;DR: IdeaAnchor suggests better research ideation comes from teaching models the structure of synthesis, not just giving them more papers and asking for ideas.
What is IdeaAnchor actually training?
The primary source here is the arXiv paper “IdeaAnchor: Teaching LLMs to Turn Literature into Research Ideas,” listed under cs.AI and cs.CL. Its core claim is simple and useful: research ideas are not born from paper summaries alone. They come from relationships between papers, roles those papers play, and a target shape for the new contribution.
That matters because a lot of current AI research workflows still look like this: dump five papers into a long-context model, ask for gaps, then ask for project ideas. Sometimes that works. Often it produces plausible fog. The model notices topical overlap, but not why one method should be borrowed, where another paper fails, or what a third paper can supply as an evaluation setup.
IdeaAnchor tries to supervise that middle layer. Each training instance includes structured specifications that encode how input papers should be synthesized into a successful idea. The paper describes those specs as covering functional roles, relationships, and target synthesis criteria. In plain English: one paper might supply the problem, another the method, another the missing evaluation lens, and the model is trained to see that pattern.
That is the interesting part. Not “AI invents science.” More like: can we teach a model to recognize the scaffolding behind a publishable research direction?
Why not just use retrieval?
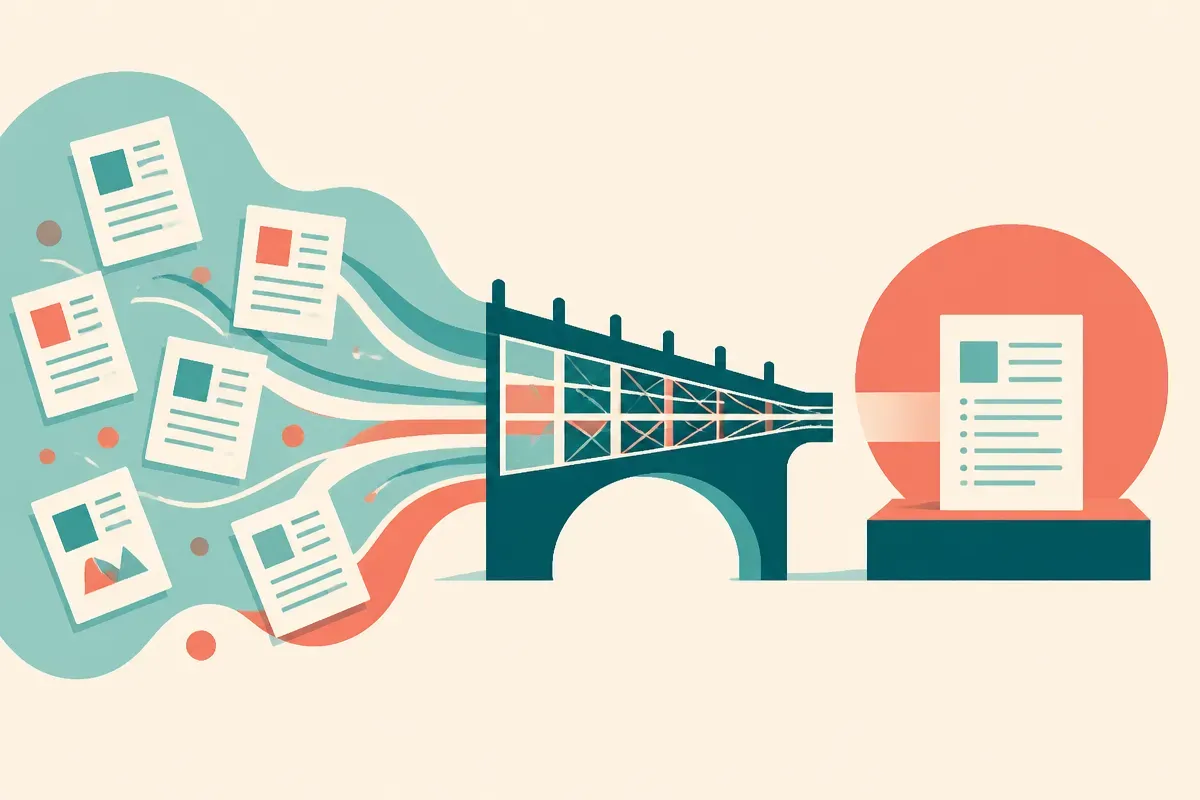
Retrieval still helps. The IdeaAnchor paper reports that adding retrieval at inference time improves detail elaboration. That tracks with what I see in applied workflows. Retrieval is good at grounding, specifics, citations, and filling in the texture that a generated idea needs to be more than a slogan.
But the paper’s analysis separates two jobs. Anchor-based training strengthens creative synthesis. Retrieval enhances detail elaboration. Combining both works best, according to the reported experiments.
That distinction is useful. RAG is often treated as a cure-all for knowledge work. It is not. Retrieval can bring in the right paragraphs, but it does not automatically tell the model what role each paragraph should play. A stack of related papers is still just a stack.
IdeaAnchor is closer to training the model on research moves. Contrast, extend, transfer, combine, stress-test. The abstract does not give us enough detail to judge the size of the gains, the evaluation setup, or whether the ideas survive expert review beyond the reported benchmarks. So I would not read this as proof that models can autonomously generate high-quality research agendas. I would read it as evidence that structured supervision beats vibes when the task is synthesis.
What should builders copy from this?
The operator lesson is bigger than academic research. If you want an AI system to produce better ideas, stop storing only source material. Store the rationale layer.
For a literature agent, that means keeping fields like: what problem this paper attacks, what method it introduces, what assumption it depends on, what limitation it admits, what evaluation it uses, and what another paper could contribute. For a product strategy agent, the same pattern applies: customer pain, current workaround, failed competitor approach, distribution constraint, open wedge.
The catch is that this structure is expensive to create. IdeaAnchor mines instances from published papers, using finished research as evidence of how prior work turned into a new contribution. That is clever, but it also brings survivor bias. Published papers show what made it through, not every dead end, bad synthesis, or politically convenient citation chain.
Still, I like the direction. It shifts the question from “Can the model brainstorm?” to “What hidden representation would make brainstorming less random?”
For a builder, I would try this manually before training anything. Take 20 strong examples in your domain. For each one, map the inputs, roles, relationships, and final synthesis criteria. Then prompt a model to produce ideas using that schema, with retrieval only after the structure is formed. The missed catch: better context is not enough. You need to teach the model what each piece of context is supposed to do.