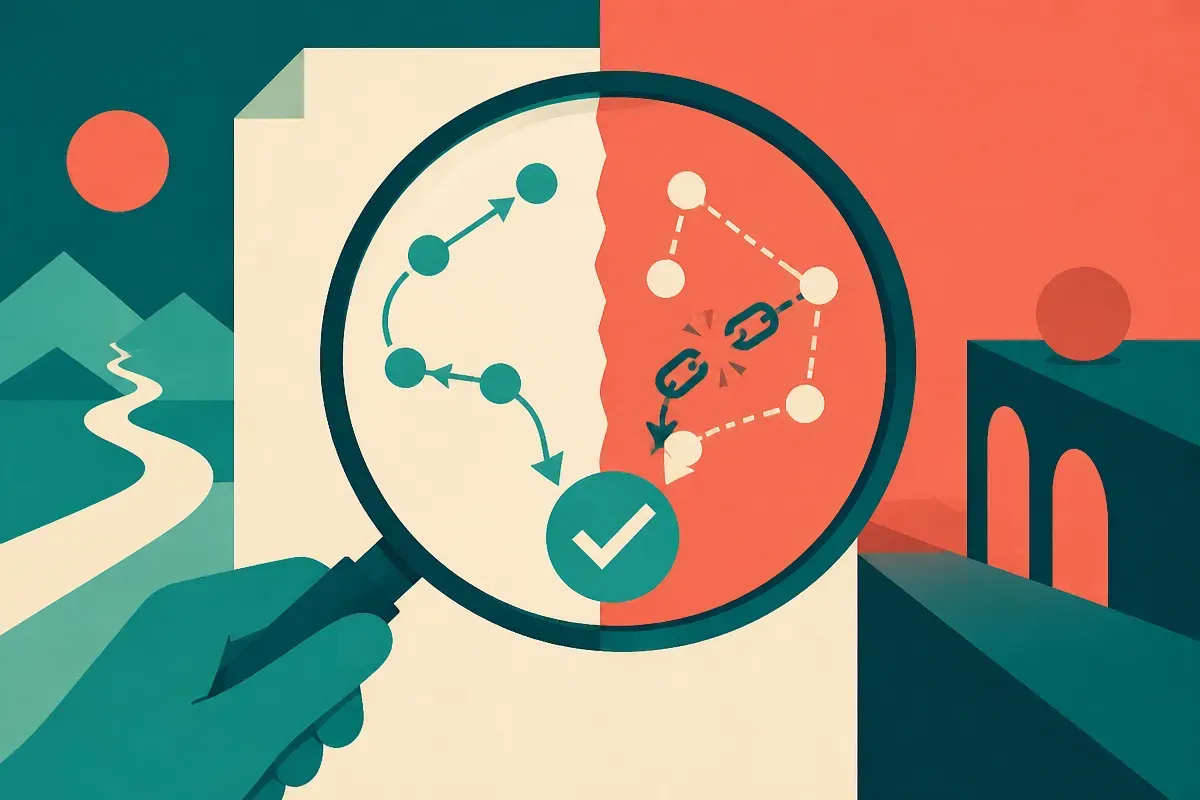
Correct math answers can hide broken reasoning traces
A verifiable grade-school math benchmark shows that chain-of-thought traces can look clean while using the wrong dependencies, which matters for agent audits, model debugging, and safety claims built on readable reasoning.
TL;DR: Chain-of-thought is useful as a debugging artifact, but this paper shows it is not reliable evidence that a model actually reasoned the way it says it did.
Can a correct answer still have a bad chain of thought?
Yes. That is the uncomfortable result in the arXiv paper “Correct Answers, Invalid Traces: What Verifiable Grade-School Math Reveals About Chain-of-Thought Traces.”
The paper looks at iGSM, a synthetic grade-school math benchmark built so the hidden structure of a problem is mechanically checkable. That matters. Most chain-of-thought traces are natural language. They sound plausible, but you cannot easily verify whether every step used the right facts for the right reason. iGSM exposes the exact quantities and dependencies a correct solution should use, so the trace can be checked step by step.
The key finding: answer accuracy and trace validity can travel together in-distribution, then split out-of-distribution. On the hardest cases, 31.6% of correct answers had invalid traces. More interesting, more than half of those invalid traces passed syntactic and arithmetic checks, but failed semantic dependency checks.
That is the important distinction. The model did not merely make a typo or botch arithmetic. It produced reasoning that looked locally valid while depending on the wrong underlying quantities.
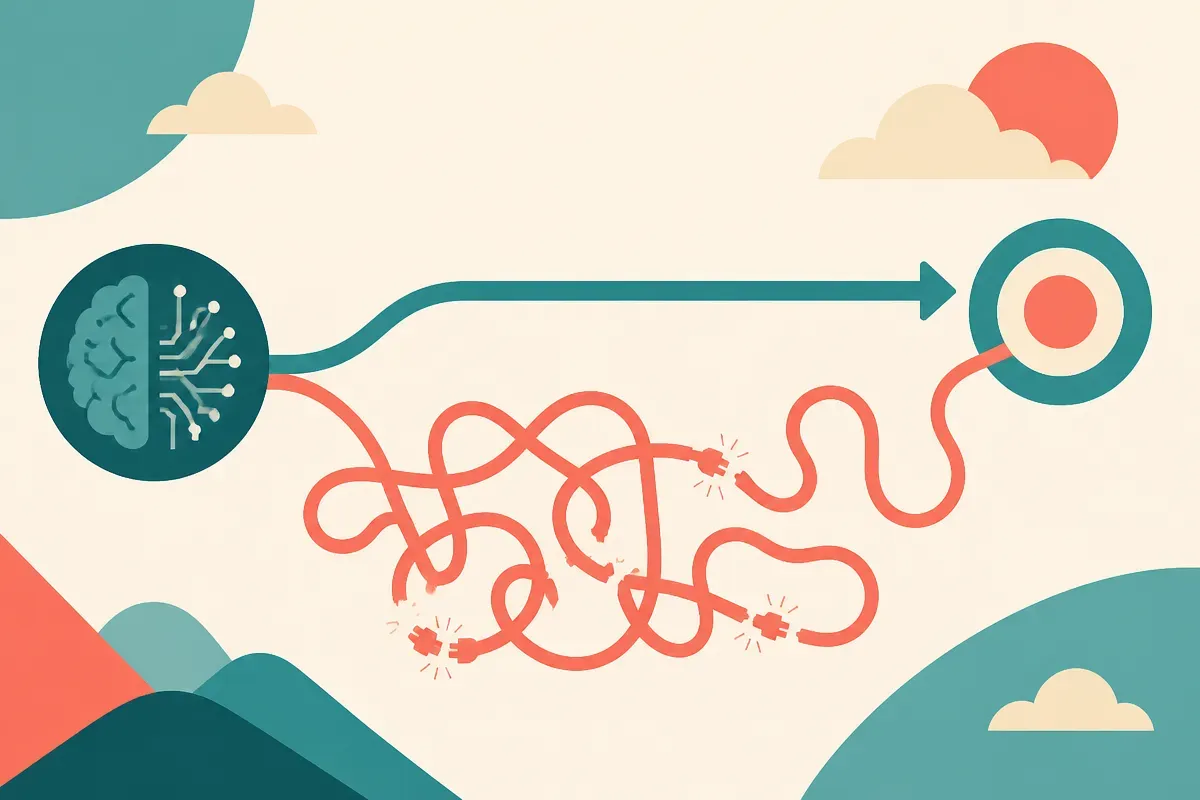
This is why “show your work” is a weaker audit than it feels. A trace can be tidy, formatted, arithmetically consistent, and still not reflect the computation that produced the answer.
What does this break for agent auditing?
A lot of current agent evaluation assumes that readable intermediate reasoning gives us a window into behavior. Not a perfect window, but at least a useful one. This paper narrows that claim.
The iGSM result does not prove all chain-of-thought is fake. It also does not say traces are useless. It says validity is conditional. If the task distribution shifts, or if the model has learned surface patterns in the trace format, then correct output can decouple from valid reasoning.
The intervention results make this sharper. “Correct Answers, Invalid Traces” reports that training on non-minimal traces led models to produce non-minimal outputs. Re-asking the same problem with a different query revealed computations inherited from the original query, which weakens the idea that minimal traces prove selective planning. Even stranger, shuffling tokens in 10% of training trace sentences preserved near-clean accuracy, including out-of-distribution, despite no trace passing verification. Swapped training traces also retained high in-distribution accuracy.
That is not how we would expect a model to behave if the trace were the load-bearing reasoning process. It looks more like traces can become a learned reporting style, sometimes aligned with computation, sometimes not.
For agents, this matters because audits often read logs: plans, thoughts, tool rationales, scratchpads, self-critiques. Those logs may still help diagnose failures. But if the question is “did the agent do the thing for the reason it claimed,” the log is evidence, not proof.
What should builders test instead?
The practical lesson is to stop grading only the final answer and stop trusting the explanation because it sounds reasonable.
If a workflow depends on reasoning traces, add checks that target dependencies. For math, that might mean verifying which variables were used. For retrieval workflows, check whether the cited documents actually support each claim. For coding agents, compare the explanation to the diff, tests, and runtime behavior. For tool-using agents, verify that the stated plan matches the actual tool calls and data flow.
I would also separate three scores: final answer correctness, local trace validity, and semantic trace validity. The last one is usually the missing piece. A trace can be grammatical and internally consistent while still using the wrong source fact, stale context, or irrelevant tool result.
The catch most readers miss: better-looking reasoning can make the problem worse, not better. Long, polished traces can increase confidence without increasing truth. For a builder, the move is not to ban chain-of-thought from evaluation. The move is to treat it like an untrusted log. Useful, inspectable, sometimes revealing. But when the stakes matter, wire it to external checks that can prove the claimed dependencies, not just admire the prose.