When a Model Gets Math Right but Reads the Same Problem Differently
A new arXiv paper shows language models can produce the same correct math answer under reordered rules while representing each ordering distinctly inside, and the better solvers are the ones that separate orderings more, not less.
TL;DR: The same math problem, shuffled into an equivalent order, can produce the same right answer while the model represents each version differently inside, and the models that keep those versions most distinct are the ones that score highest.
The paper is “Order-Invariant Answers, Order-Sensitive Representations in Mathematical Reasoning,” posted to arXiv under cs.AI, cs.CL, and cs.LG. It asks a question that sounds trivial until you sit with it. If you reorder a set of math rules without changing what they mean, the answer should not change. Fine. But should the model’s internal state also stay the same? The intuition from a lot of interpretability work is that a “clean” reasoner would collapse equivalent inputs into one representation. This paper says the opposite happens, and the opposite is a good sign.
What did the paper actually test?
The setup is deliberately synthetic. The authors built multi-step function-composition problems, the kind where you apply a chain of rules to get a result. Each problem was presented under multiple rule orderings that all lead to the same correct answer. So the semantic content is fixed, only the presentation order moves.
Then they measured two things. Accuracy, obviously. And something they call permutation signal-to-noise ratio, or permutation SNR. That metric quantifies how distinctly a model’s internal activations encode the ordering pattern, relative to the normal variation you see across different problem instances. High SNR means the model’s internals clearly “know” which ordering it received. Low SNR means the orderings blur together inside the network.
They ran this across 16 language models from 1B to 8B parameters. Small models, which matters, because you can actually probe these and the compute is tractable.
Why is order-sensitive internally a good thing?
Here is the finding that flips the intuition. Layer-averaged permutation SNR was positively rank-correlated with accuracy in every synthetic setting they tested. Spearman correlations reached 0.86. That is a strong monotonic relationship for this kind of probing work.
Read that plainly: the models that solved reordered problems more accurately were the ones that represented the different orderings more distinctly, not less. The better reasoners were not the ones smoothing everything into a single order-blind representation. They were the ones tracking the specific order they got.
That makes sense once you stop assuming invariance is the goal. To correctly compose functions, a model has to respect the actual sequence of operations it was handed. It needs to know which rule came first in this presentation so it can apply the composition in the right way and still arrive at the order-independent answer. Losing the ordering information early would throw away exactly what it needs to do the work. So distinctness inside is a feature of a model doing the computation properly, not a bug in a model that failed to generalize.
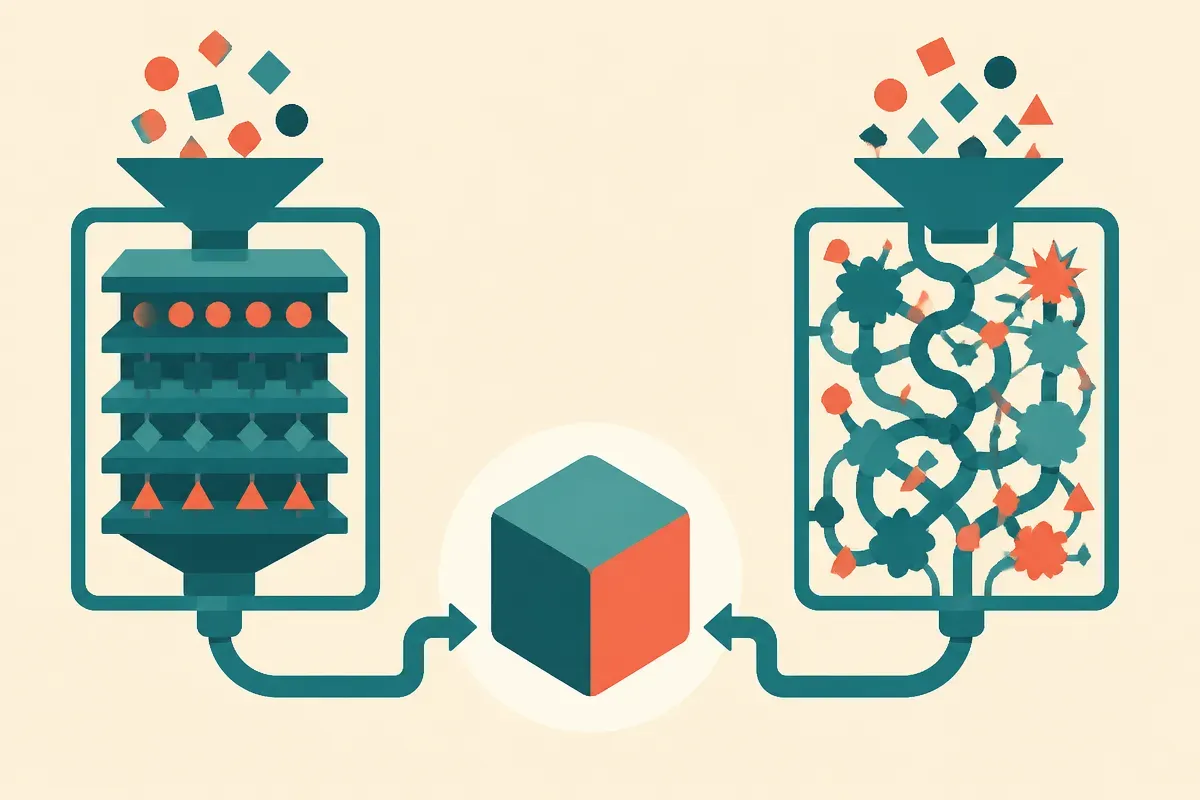
The authors frame this as a distinction worth naming: answer invariance versus representation invariance. Your output can be invariant while your internals are highly sensitive. Those are two separate properties, and this paper is arguing we have been conflating them.
Why does this matter beyond the benchmark?
Most of us judge reasoning models on one number: did it get the answer right. This paper is a reminder that the same answer can come from very different internal processes, and the process tells you something the answer alone cannot.
Think about what “the same correct answer” hides. Two models both score 90 percent on a reordered math set. One of them tracks ordering cleanly and composes step by step. The other might be pattern-matching to a memorized answer shape and getting lucky on the reorderings. Accuracy cannot tell those apart. Permutation SNR starts to. It gives you a representational signal that correlates with genuine competence, which is the kind of thing you want when you are deciding whether a model actually reasons or just performs reasoning-shaped output.
There is a caution here too, and the authors are honest about the scope. This is synthetic function composition, not real-world math word problems or agentic multi-step tasks. It is 1B to 8B models, not frontier scale. The correlation is strong and consistent across their settings, but “consistent across our synthetic settings” is not “proven universal law.” I would treat this as a well-supported directional finding, not a metric you bolt onto production tomorrow. The value is conceptual: it separates two things we treat as one, and it gives a concrete way to measure the separation.
Does this change how we should build evals?
I think it points somewhere useful. Right now most eval suites are output-only. You feed inputs, you grade answers, you get a score. That is cheap and it scales, and it will remain the backbone. But it is blind to the failure mode where a model gets the right answer for the wrong internal reason, which is exactly the kind of thing that breaks under distribution shift.
Representational probes like permutation SNR are a second lens. They are more expensive, they require access to activations, and they are harder to standardize. You are not going to run them on a closed API model you cannot instrument. But for open-weight models you own, in domains where you actually care whether the reasoning is real, a probe that correlates with accuracy at 0.86 is a diagnostic worth having. It could flag two models that look identical on accuracy but differ on whether they are tracking structure or memorizing shortcuts.
The honest gap: nobody has shown yet that permutation SNR predicts out-of-distribution robustness. The paper shows in-distribution correlation with accuracy. The interesting causal claim, that order-distinct representations make a model more robust to harder or shifted problems, is the follow-up work, not this result. Do not oversell it before that is done.
Practitioner’s take: if you run open-weight small models for structured reasoning, this is a nudge to look inside, not just at the scoreboard. The concrete move is to take a task where order should not change the answer, generate equivalent reorderings, and check both that accuracy holds and that the internal representations stay coherent with the ordering. Two models tied on accuracy can be pulled apart by how cleanly they represent the input structure, and the one that keeps orderings distinct is the better bet for anything that will drift out of your test distribution. The catch most readers will miss: the win here is not “make your model order-invariant inside.” That is the wrong target. The finding says the strong reasoners are order-sensitive internally and order-invariant only in their answers. If you train or prune toward internal invariance because it sounds cleaner, you may be sanding off the exact structure that makes the model good.