What Revolut's Codex rollout actually tells us about agent adoption in a bank
OpenAI says Revolut cut coding time 30 to 60 percent and runs an autonomous financial crime agent. Here is what holds up, what is marketing, and how an operator should read a customer story from a model vendor.
TL;DR: Revolut’s numbers (30 to 60 percent less coding time, an autonomous fin-crime agent) are a useful signal that agents are moving into regulated workflows, but they come from an OpenAI customer story, so treat them as a vendor-shaped claim and copy the structure, not the stat.
The story comes from two sources, both first-party to OpenAI: the blog post “How Revolut raises ambition without lowering the bar” and a companion video, “How Revolut’s lean teams take on bigger challenges with OpenAI.” Same campaign, same framing. That matters for how you read every number in it.
What did Revolut actually claim?
Three concrete things, all attributed to Revolut people speaking in OpenAI’s material.
First, a coding productivity claim: 30 to 60 percent reduction in coding time once teams used Codex regularly, plus less time spent hunting through internal knowledge bases. One engineer described building an internal code service by launching multiple agents, assigning each a task, and waiting for the implementation instead of staffing a full team.
Second, a shipping-speed claim: Revolut now thinks it can deliver to market “probably 3x faster than what is reasonable by market standards,” and says that often happens. The quote that stuck with me: “the bar keeps moving up but AI is making that all possible.”
Third, and most interesting, an agent-in-production claim. Revolut’s Fin Crime Agent is described as an autonomous agent doing transaction screening, monitoring, and investigation. The specific detail: they saw a shift “around the time of GPT-5.5” where the agent had “enough intelligence for cost that were reasonable” to delegate initial investigation and screening. You give the agent rules, sources, and tools, and it runs the investigation on its own.
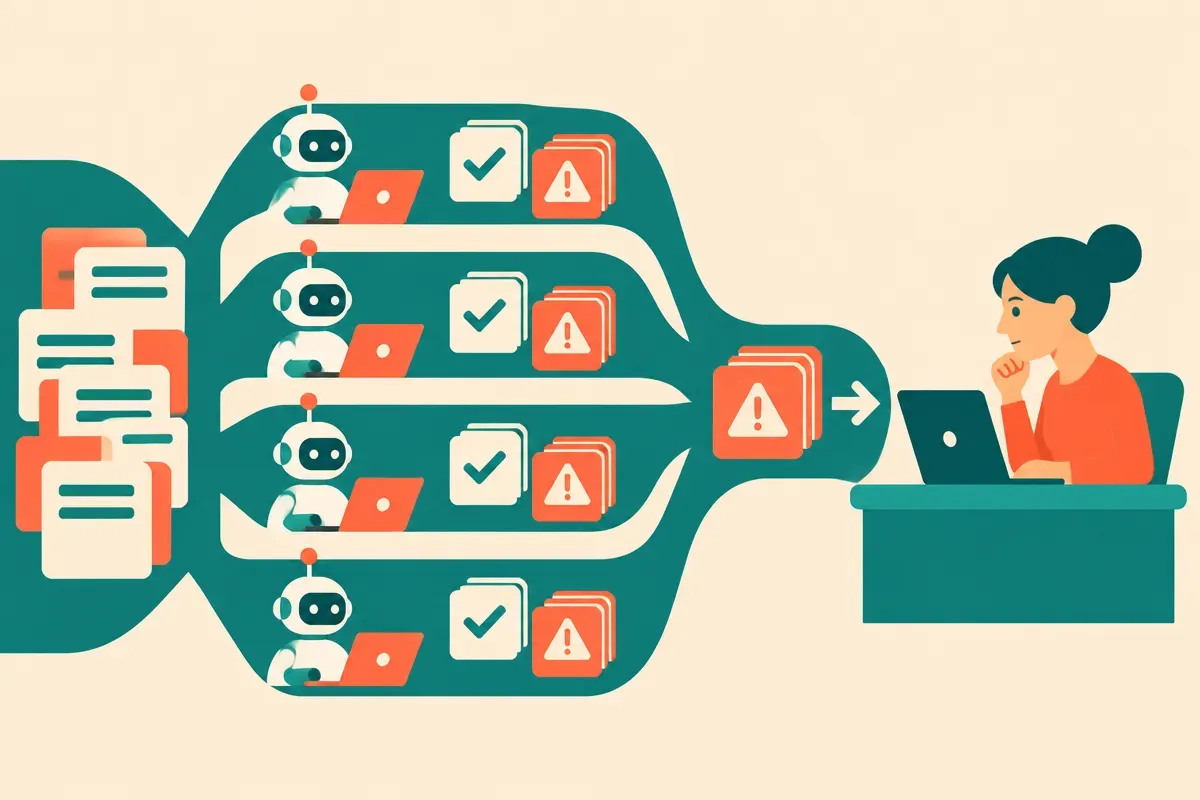
That GPT-5.5 reference is the part worth pausing on. The claim is not “AI got better.” It is “the price per unit of reasoning crossed a threshold where delegating a first-pass investigation became economically sane.” That is the real mechanism behind most agent adoption right now, and it is more honest than the usual capability hype.
How much of this should you believe?
Here is the discipline. This is a vendor customer story. OpenAI published both the blog and the video. The numbers come from Revolut employees, but they were selected, edited, and framed by the model vendor whose product is being sold. None of that makes them false. It makes them unaudited and optimistic by construction.
A few things are missing that I would want before treating the headline numbers as fact:
The 30 to 60 percent coding-time reduction has no denominator. Reduction across which teams, measured how, over what baseline? Self-reported coding-time savings are notoriously soft. People feel faster. Cycle time to production, defect rates, and rework often tell a different story. GitHub’s own earlier Copilot studies showed task-completion speedups in controlled settings, but “coding time” is not the same as “software delivered,” and a bank ships through review, compliance, and release gates that a code assistant does not touch.
The “3x faster than market standards” line is a vibe, not a metric. “Reasonable by market standards” is undefined. I would read it as directional enthusiasm, not a benchmark.
The Fin Crime Agent claim is the one I take most seriously, because it is specific about what changed (cost per reasoning step) and what the agent does (initial investigation and screening, with a human implied downstream). Revolut frames success as “catching meaningful issues earlier,” not “replacing analysts.” That is the right framing for a regulated environment, and the fact that the agent handles initial screening rather than final disposition is the tell: a human still owns the decision that carries regulatory weight.
So: believe the shape of the story. The direction is real and consistent with what I see elsewhere. Hold the exact percentages loosely.
Why is the GPT-5.5 cost threshold the real story here?
Strip away the testimonial and the interesting claim is economic, not technical.
Agents did not become possible because a model got smarter in some abstract sense. They became deployable because a capable-enough model got cheap enough that you could point it at a boring, high-volume task (first-pass transaction screening) and have the math work. That is the pattern across almost every serious agent deployment I trust: the unlock is cost-per-competent-decision falling below the cost of a human doing the same first pass.
This reframes how you should evaluate agents for your own work. Do not ask “is the model smart enough.” Ask “is the model smart enough at a price where delegating the first 80 percent of this task beats the status quo.” Fin-crime screening is a perfect candidate: enormous volume, rules-based scaffolding, clear escalation path to a human, and a cost of false negatives high enough that early catching has real value.
Coding is the other candidate for the same reason. Codex is not writing Revolut’s whole platform. It is compressing the time between intent and a working first draft, which is exactly the part of software work that is expensive in human attention and cheap to redo if wrong.
What should an operator actually copy from this?
Not the number. The structure.
The reusable pattern in the Revolut story is: pick a high-volume task with a rules scaffold, delegate the first pass to an agent, keep a human on final disposition, and measure the thing that matters downstream rather than the thing that feels faster.
If you want to run this at your own shop, start where Revolut did implicitly. Give the agent explicit rules, a defined set of sources, and the tools it needs, then scope it to initial investigation and screening only. Do not hand it the final call on anything with legal or financial consequence. Measure cycle time to a shipped, reviewed outcome, measure escape rate (issues the agent missed that a human caught), and measure rework. If coding-time savings do not survive contact with your review and release process, you have a demo, not a deployment.
The catch most readers will miss: this is a story about a company that already had the scaffolding. Revolut has defined fin-crime rules, internal tooling, and engineering process to plug an agent into. The 30 to 60 percent did not come from the model. It came from a model dropped into a system that was ready to receive it. If your workflows are undocumented and your rules live in people’s heads, buying GPT-5.5 or Codex gets you a fraction of this, because there is nothing for the agent to stand on. Build the scaffold first. The agent is the easy part.