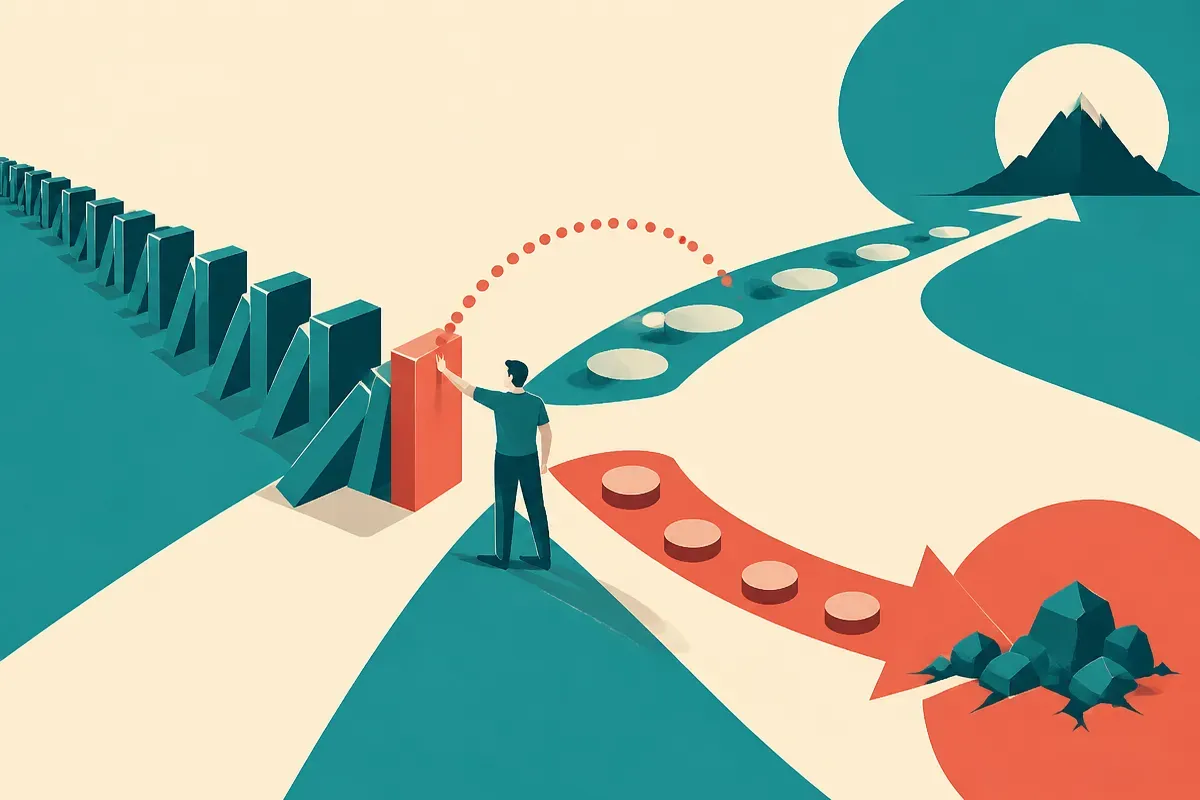
StepBack targets the first bad reasoning step instead of rerunning the whole chain
StepBack is a test-time reasoning method that tries to keep self-consistency gains while cutting wasted tokens by resampling only the likely error point and the reasoning that follows.
TL;DR: StepBack is useful because it treats reasoning failures as local repair problems, not as a reason to regenerate full chains over and over.
What problem is StepBack actually solving?
My primary source here is the arXiv cs.AI/cs.CL paper, “StepBack: Step-Level Error-Localized Resampling for Efficient Test-Time Reasoning.”
The target is self-consistency, the familiar trick where a model samples multiple chain-of-thought paths, then votes on the final answer. It often helps reasoning accuracy because one bad path can be outvoted by several good ones. The catch is cost. You pay for every full trajectory, including all the prefixes that were already fine.
That is the waste StepBack goes after.
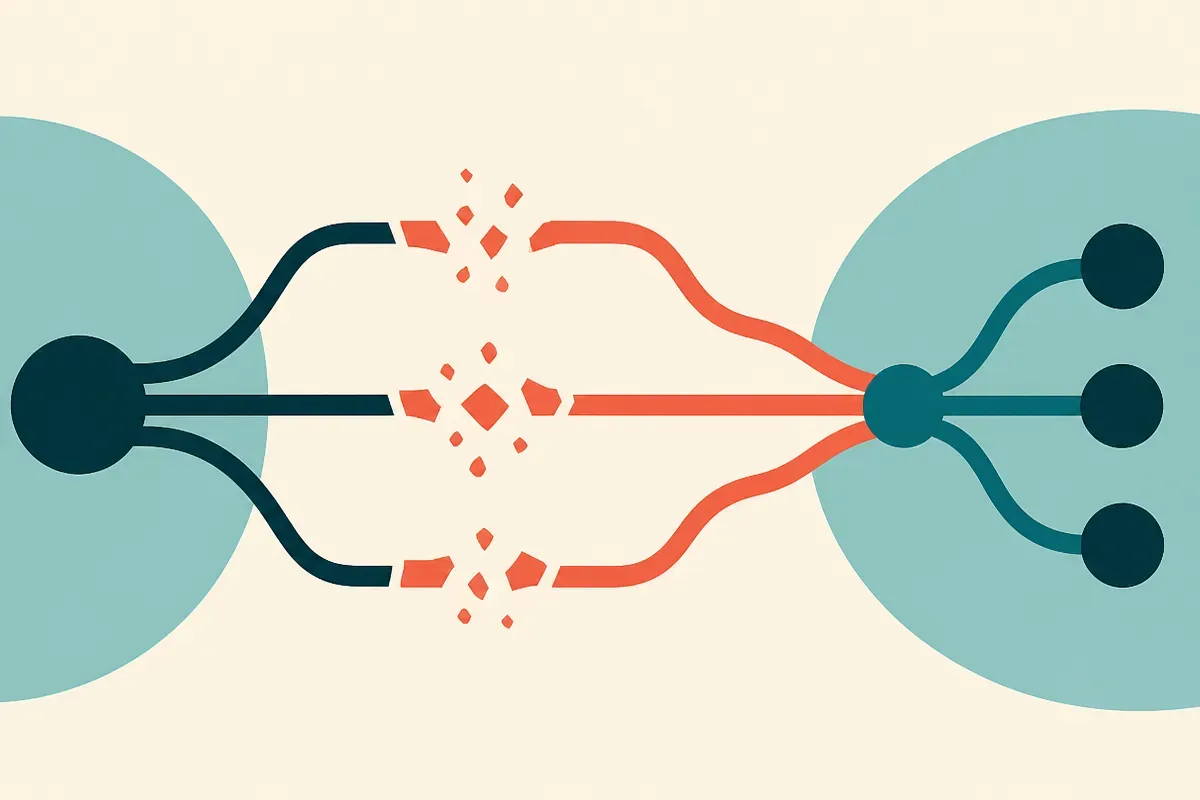
Instead of sampling many complete reasoning chains with a fixed budget, StepBack starts with a small set of draft trajectories. It then tries to locate likely first error positions using lightweight signals. Once it finds that point, it resamples the suspect step and the suffix after it. Then it uses majority voting on the answers.
That sounds small, but it changes the unit of retry. Self-consistency retries the whole argument. StepBack retries the broken part of the argument.
Why does local repair matter at inference time?
The paper reports that StepBack matches self-consistency accuracy on average across seven mathematical reasoning and multi-hop QA benchmarks, while reducing token usage by up to 41.26%.
That “on average” matters. So does “up to.” This is not a claim that every task gets cheaper by 41%. It is a claim that, across the reported benchmark set, the method can preserve the accuracy profile of self-consistency while cutting a meaningful chunk of inference spend.
For builders, that is the interesting part. A lot of reasoning work right now is stuck between two bad options: run the model once and accept brittle answers, or sample a pile of full chains and watch latency and cost climb. StepBack suggests a middle path: generate enough diversity to detect trouble, then spend extra tokens only near the likely fault line.
This also fits how many real reasoning failures look. The model may set up the problem correctly, make one bad algebra move, then confidently continue from a poisoned state. Or it may retrieve the right facts for a multi-hop question, connect them in the wrong order, then produce a plausible answer. Regenerating the whole chain is blunt. Repairing the first bad turn is closer to what a human reviewer would do.
Where should builders be skeptical?
The open question is error localization. StepBack depends on detecting the likely first error position with lightweight signals. If that detector is weak, biased toward the wrong step, or confused by problems where several mistakes interact, the savings can evaporate or accuracy can slip.
The benchmark mix also matters. Mathematical reasoning and multi-hop QA are good testbeds because intermediate steps have structure. The same idea may be harder to apply to open-ended planning, legal drafting, code architecture, or product strategy, where “the first error” is less crisp. Sometimes the issue is not a single bad step. Sometimes the whole framing is wrong.
I also would not treat this as a replacement for better models or better task design. It is an inference-time tactic. Useful, but not magic. It sits in the same family as adaptive inference methods, and the paper says StepBack can be combined with Adaptive Consistency for more efficiency. That combination is where this may become more practical: spend little on easy questions, spend more on hard ones, and spend the extra budget near the suspected break.
Practitioner’s take: if you are already using self-consistency in a reasoning workflow, StepBack is the kind of idea worth prototyping before you scale sampling budgets. Log intermediate steps, compare multiple draft traces, mark where they first diverge or lose confidence, and retry from that point instead of restarting everything. The catch most teams miss is measurement. You need token cost, latency, final accuracy, and failure-type labels side by side, because a cheaper reasoning loop that silently misses rare hard cases is not actually cheaper.