Same outputs are not enough for AI mechanism audits
The arXiv paper on integrated information is a useful warning for AI audits: finite experiments can certify some mechanism claims, but behavior alone and partial access can make the important differences invisible.
TL;DR: If you want to certify how an AI system works, not just what it does, output tests are not enough. You need designed interventions, internal access where possible, and claims narrow enough to survive finite data.
Can identical behavior hide different mechanisms?
The primary source here is the arXiv cs.AI/cs.LG paper, “Same Behavior, Different Mechanism: What Finite Experiments Can Certify About Integrated Information.” It studies a hard version of a problem that shows up all over AI auditing: can finite experiments tell us something true about a system’s internal mechanism?
The paper uses integrated information, written as $\varphi$, from integrated information theory. That is not everyone’s favorite lens, and I am not treating it as a settled consciousness meter. The useful part is the setup. $\varphi$ is a mechanism-level quantity. It depends on the causal transition law of a system, not just input-output behavior.
That distinction matters.
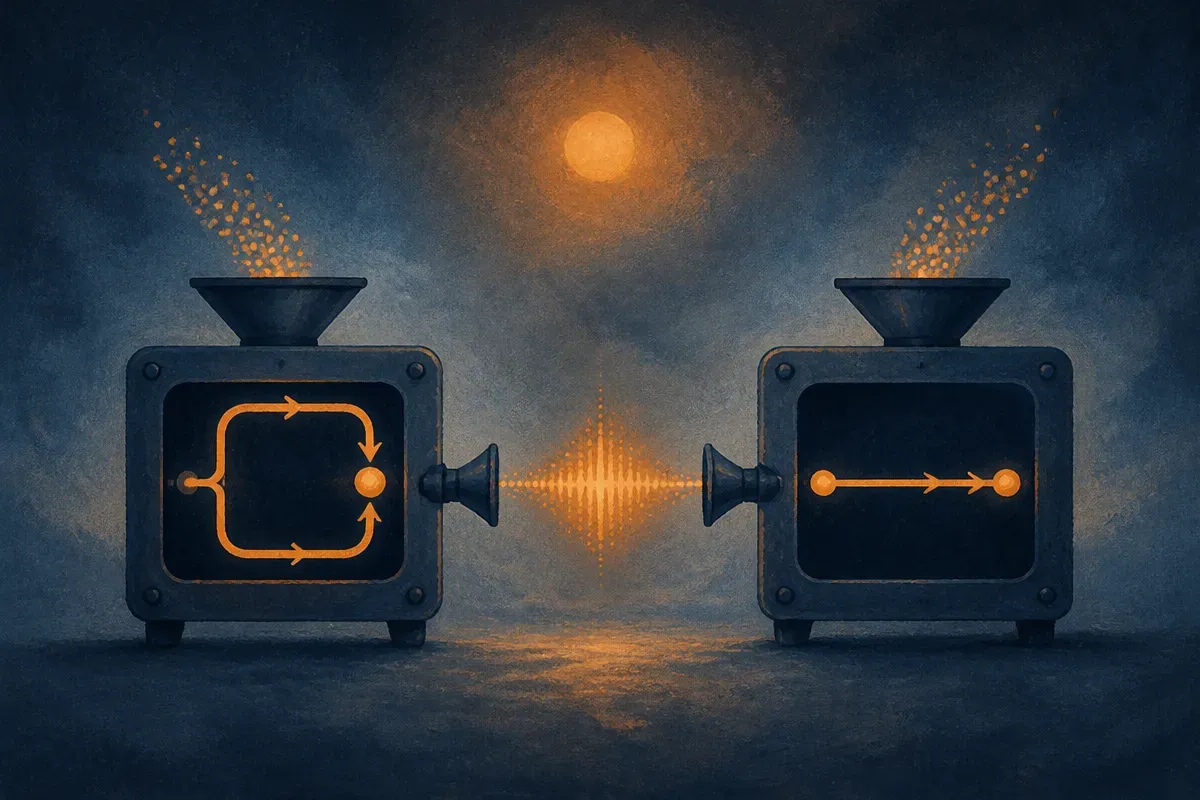
The paper reports an example where a recurrent network and a feed-forward network have identical input-output laws at the relevant response delay. Same observed behavior. Different mechanism. One carries 0.28 bits of integrated information, the other 0 bits. Internal recordings separate them within 4 to 53 trials.
That is the core lesson. Behavioral equivalence can be real, not just a testing failure. Two systems can look the same from the outside and still compute in meaningfully different ways.
For AI evaluations, this pushes against a common shortcut. We run task suites, compare answers, and then make claims about reasoning, planning, situational awareness, deception, or agency. Sometimes that is fine as product testing. It is weaker as mechanism certification.
What breaks when you only observe part of the system?
The paper’s harder result is about partial access. In several examples, leaving units out of a one-step recording creates precision floors of 0.30 to 1.02 bits. No amount of extra sampling fixes that. More data cannot recover what the experiment was not designed to observe.
That should sound familiar to anyone auditing closed models, API-only systems, or agent stacks where logs are incomplete. If you only see prompts, outputs, and a few tool calls, there may be internal distinctions you simply cannot identify.
The parity-network example makes this sharper. In all-but-self parity networks, recordings of any length see several hidden units only through the product of their fidelities. In plain English: the observations collapse multiple internal possibilities into the same visible pattern. The paper says one intervention broke that symmetry in exact checks.
So the issue is not just “collect more traces.” It is “collect the right traces under the right interventions.” That is a different operational standard.
The paper also reports that $\varphi$ has sharp edges. Because it selects a partition, cause, and effect by one criterion and reports another, tiny mechanism changes across an edge can change the result by 25% to 100% at 99% of the edges found in random networks. About 1% of surrogate models that fit interventional data almost perfectly still misreport $\varphi$ by more than 20%.
That is a warning label for proxy models. A surrogate can match data well and still be wrong on the mechanism-level quantity you care about.
What can an auditor actually certify?
The paper is not saying mechanism audits are hopeless. It is more useful than that.
It says one-sided claims survive. The arXiv paper proves $\varphi > 1.004$ bits throughout a 64-dimensional region of mechanisms and says that claim can be certified from about $10^7$ controlled transitions with false-certificate probability at most $α$.
That number is not cute. Ten million controlled transitions is expensive, even in small synthetic systems. For frontier AI systems, the direct analog may be impossible. But the pattern is practical: certify lower bounds or bounded claims, not sweeping labels. Design experiments around identifiability. State where partial observability creates a floor you cannot beat.
This is where I think AI safety and product evals should borrow more from experimental design. Before asking “does the model have capability X,” ask what observations would distinguish the mechanism you mean from a cheaper imitation. If the answer is “only the final answer,” you probably have a behavior test, not a mechanism audit.
For builders, the move is to separate three claims in your eval docs: what the system did, what internal evidence you observed, and what mechanism claim you think follows. Try paired systems or ablations that preserve behavior while changing architecture, memory, tools, or recurrence. Then see if your eval can tell them apart. The catch most readers miss: adding more test cases will not fix a blind measurement setup. Sometimes the only honest answer is that your experiment cannot certify the thing you want to claim.