FPGA coding agents need boring toolchains before they need autonomy
An arXiv paper on AWS Cloud FPGA development shows a more useful path for coding agents: not magic chip design, but layered tests, reproducible workflows, and honest limits when hardware performance disappoints.
TL;DR: Coding agents become more useful for FPGA work when the workflow is broken into verifiable stages, not when we pretend they can jump straight from a prompt to good hardware.
What did the AWS FPGA paper actually build?
The primary source here is the arXiv cs.AI and cs.LG paper titled “Enabling AWS Cloud FPGA Development Using High-Level Vitis HLS.” The claim is narrow, and that is why it is interesting.
The work builds a toolchain for developing ML models on AWS EC2 F2 cloud FPGA infrastructure from a higher-level language flow. More specifically, it connects Vitis HLS to the AWS HDK and AFI deployment workflow. The paper says this bridge has been absent from the academic literature despite eight years of AWS FPGA availability.
That matters because FPGA development is usually where “just ask an AI agent” goes to die. The environment is picky. The compile cycles are long. Bugs can live at several layers at once: model math, quantization, HLS translation, timing, memory movement, or the physical FPGA implementation.
The paper’s practical contribution is not that an agent magically designs an accelerator. It is that the toolchain gives the agent, and the human supervising it, a path with checkpoints.
The validation target was TinyBERT fine-tuned for address Named Entity Recognition. The implementation put the embedding layer and the first of four encoder layers on FPGA hardware. That is not a full production accelerator. It is a constrained proof that the path can carry a real ML model from software into deployed FPGA hardware.
Why is the four-stage workflow the real story?
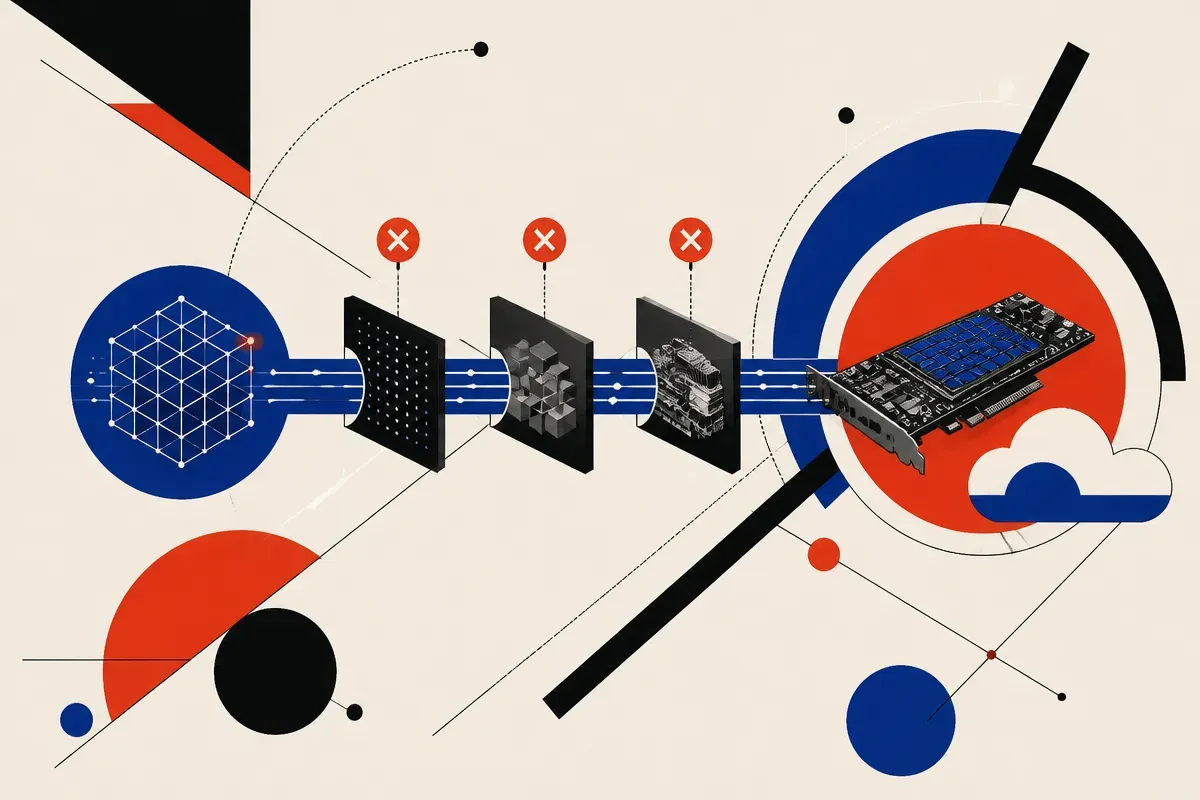
The paper introduces a four-level methodology: FP32 PyTorch, bit-accurate quantized Python, HLS C-simulation, and physical FPGA. That stack is the part builders should pay attention to.
Each stage answers a different question. Does the model work in normal floating point? Does the quantized version still match expectations? Does the HLS version behave like the quantized reference? Does the deployed FPGA do what the simulated design said it would do?
That is exactly the kind of scaffolding coding agents need. Agents are better when they can run tests, compare outputs, inspect diffs, and localize failure. They are worse when the task is “make it work” across an opaque hardware/software boundary.
This is also a useful reminder for AI infrastructure work generally. Autonomy is not one switch. It is often the result of making the environment testable enough that an agent can take small steps without silently destroying the project.
What does the poor performance result tell us?
The honest part: the FPGA implementation performed poorly compared with CPU and GPU implementations. The paper attributes this to streaming weights from host DRAM.
That is not a footnote. Memory movement is the work. Especially for transformer-style models, the accelerator story is usually less about raw compute and more about where weights and activations live, how often they move, and whether the hardware is fed efficiently.
So the result cuts both ways. The toolchain worked, but the first implementation did not produce a competitive accelerator. That is a useful outcome. It separates “we can deploy” from “we should deploy.”
For operators, this is the right mental model for specialized hardware. FPGAs can make sense when you have stable workloads, tight latency or power constraints, custom data paths, or enough volume to justify engineering time. They are less compelling when the model changes constantly or when the memory architecture cancels out the compute gains.
Practitioner’s take: I would use this kind of workflow as an agent harness, not as a promise of push-button FPGA acceleration. Pick one small model component, build golden outputs at each stage, force the coding agent to prove equivalence before moving down the stack, and measure memory movement early. The catch most teams miss is that “runs on FPGA” is not the finish line. If the design streams weights the wrong way, the expensive hardware can still lose to the boring CPU.