What JavaScript Frameworks Cost You When the Reader Is an AI
Client-side rendering saves developer effort but hands AI crawlers a blank page, and as agents become a real slice of traffic, the framework choice you made for humans now quietly taxes every bot that visits.
TL;DR: Heavy client-side JavaScript frameworks make your site cheap to build and expensive for AI to read, and as more of your traffic comes from crawlers and agents, that tradeoff is quietly getting worse.
The primary source here is a discussion that ran on Hacker News under the title “The AI cost of JavaScript frameworks.” I want to be upfront: this is a community thread, not a benchmarked study from a named lab, so I’m treating the specific claims as arguments to test rather than settled numbers. But the core idea is real and worth working through, because it sits exactly where a lot of builders are not looking.
Why does a JavaScript framework cost anything for AI at all?
Start with how a modern single-page app works. You ship a mostly empty HTML shell, then a pile of JavaScript executes in the browser and builds the actual content on the fly. A human with Chrome never notices. The page fills in, it looks great, everyone’s happy.
Now send a crawler.
A lot of bots do not run JavaScript. They fetch the HTML, see a near-empty <div id="root">, and leave with nothing. The ones that do render JavaScript, like Google’s and some of the better-funded AI crawlers, have to spin up a headless browser, execute your bundle, wait for network calls to resolve, and only then read the page. That is dramatically more expensive per URL than parsing static HTML.
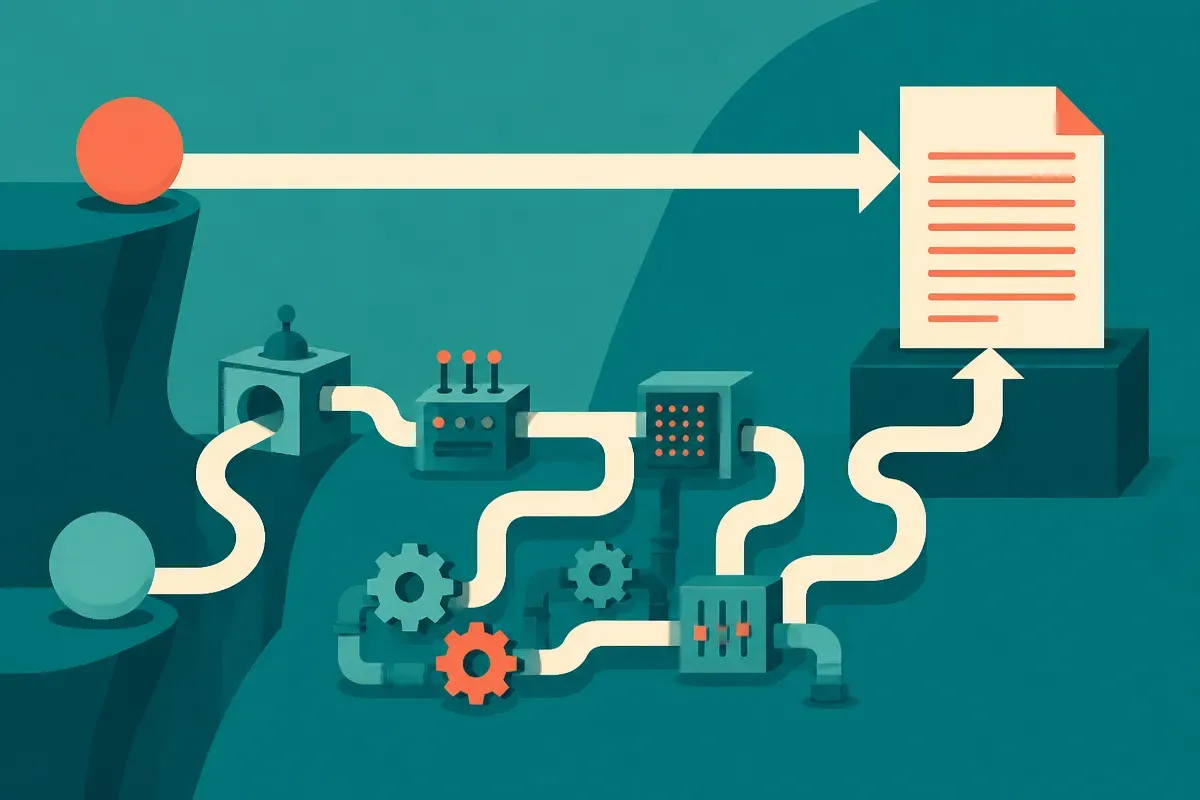
The “AI cost” framing in the thread is really about who pays for that rendering. For a human, the browser pays, on their device, once. For an AI crawler trying to index or answer questions across millions of pages, rendering JavaScript at scale is a budget line. When something gets expensive, it gets rationed. That is the part builders miss: a crawler that technically can render your site may choose not to render all of it, or render it less often, because you are not worth the compute.
Is this actually new, or just old SEO advice with a fresh coat?
Honest answer: mostly the second, and that is not a knock.
We have known for a decade that client-side rendering is rough on search engines. Google got better at executing JavaScript, so a lot of teams concluded the problem was solved and moved on. The Hacker News argument is that the audience changed underneath us. It is no longer just Googlebot you are optimizing for. It is ChatGPT’s browsing, Perplexity, Claude’s retrieval, and a growing set of agents that fetch pages on behalf of a user mid-task.
Those systems have very different rendering budgets and tolerances, and most of them are younger and less patient than Google’s crawler. Some grab raw HTML and call it done. If your content only exists after hydration, you are invisible to them even when you rank fine in traditional search.
So the mechanics are old. The stakes are new, because the share of your traffic that is a machine reading your page, not a person, is climbing. When an AI assistant summarizes “the best options for X” and your page never made it into the model’s view, you do not get cited, you do not get the referral, and you never see why.
How much does this really matter for a given site?
Depends entirely on what the site is for, and this is where I push back on the thread’s more absolute takes.
If you run an internal dashboard, a logged-in app, or a tool nobody needs to discover through search or an assistant, the AI cost of your framework is roughly zero. Render however you like. React, Vue, Svelte, whatever ships fastest for your team. Nobody is crawling your billing settings.
If you run anything that lives or dies on being found, like content, docs, product pages, local business pages, a marketplace, the calculus flips. Every layer of JavaScript between a fetch and your actual text is a tax on discoverability, and now it is a tax paid by both search engines and the AI layer sitting on top of them.
The frustrating middle is the site that was built as an app but needs to be found like content. That is most startup marketing sites, honestly. Built in Next.js or similar because the team already knew React, shipped with client-side rendering on the pages that most need to be machine-readable. The fix is not “stop using frameworks.” It is using the server-rendering and static-generation paths those frameworks already give you, so the HTML that leaves your server already contains the words.
This is the part I deal with directly. I run Lucky Domains, where part of the work is building sites that actually have to rank (https://luckydomains.io/services.html#websites), and the single most common own-goal I see is a beautiful site whose content does not exist until JavaScript runs. It looks perfect to the person who approved it. It is a ghost to half the things trying to read it.
What should a builder actually check this week?
Stop theorizing and look at your own HTML. Three quick tests tell you most of what you need.
First, curl your most important page, or use “view source” rather than “inspect element.” View source shows the raw HTML the server sent. Inspect shows the DOM after JavaScript ran. If your headline, body copy, and key links are missing from view source, every non-rendering bot sees that same emptiness.
Second, check Google Search Console’s URL inspection and the rendered-HTML preview. If Google struggles, assume the thinner AI crawlers struggle more.
Third, fetch a few pages the way a simple crawler would, no JavaScript execution, and read what comes back. If it is a shell, you have found your problem.
The catch most people miss: this is not a binary where you rip out your framework. Next.js, Nuxt, SvelteKit, Astro, and the rest all support server-side rendering or static generation. The content can live in the initial HTML and you can keep the interactive niceties on top. The failure is almost always a default config choice, made for developer convenience, that quietly opted your most discoverable pages into client-only rendering.
Practitioner’s take: treat “what does the raw HTML contain” as a first-class metric for any page meant to be found, right next to load time and Core Web Vitals. Audit your top twenty URLs by view-source this week, flag any where the main content is missing, and move those to server rendering or static generation. You do not need a rewrite. You need your words to exist before the JavaScript does, because a growing share of your readers, the machine ones, never wait for the JavaScript at all. And since this is a community thread rather than a measured study, verify the effect on your own stack before you treat any single claim as gospel.