TextSeal2 keeps watermarks alive under speculative decoding
A new distortion-free watermarking scheme for LLMs survives the speed trick most labs now use in production, and does it without touching output quality or adding latency, which is exactly the gap that killed earlier watermarks in practice.
TL;DR: TextSeal2 is a text watermark that keeps detecting machine-generated text even when the model uses speculative decoding to run faster, without changing what the model would have said or slowing it down, which is the combination earlier schemes never managed.
Watermarking LLM output has always had a credibility problem. Every scheme promises you can tell machine text from human text after the fact. Most of them quietly break the moment you run the model the way anyone actually runs it in production: fast, diverse, and with speculative decoding turned on. The primary source here, “TextSeal2: Distortion-Free LLM Watermarking with Copula Mixing and Memoryless Races” (arXiv cs.CL / cs.AI), goes straight at that gap. It is a distortion-free watermark that holds its signal under speculative decoding and adds no measurable inference latency. That last part is why I think it matters more than the usual watermarking paper.
What problem does TextSeal2 actually solve?
Start with what “distortion-free” means, because the whole thing hinges on it. A distortion-free watermark does not change the distribution of text the model produces. The output you get is statistically identical to the output you would have gotten with no watermark at all. You are not trading quality for traceability. The signal is hidden in how tokens are sampled, using a secret key, not in which tokens get boosted.
The classic way to do this is the Gumbel-max scheme. You turn the model’s next-token probabilities into a race between noisy scores, and the key controls the noise. A detector that knows the key can later look at the text and see the fingerprint. Clean idea. The catch: a single fixed key makes output deterministic and kills diversity. Ask the same question twice, get the same answer twice.
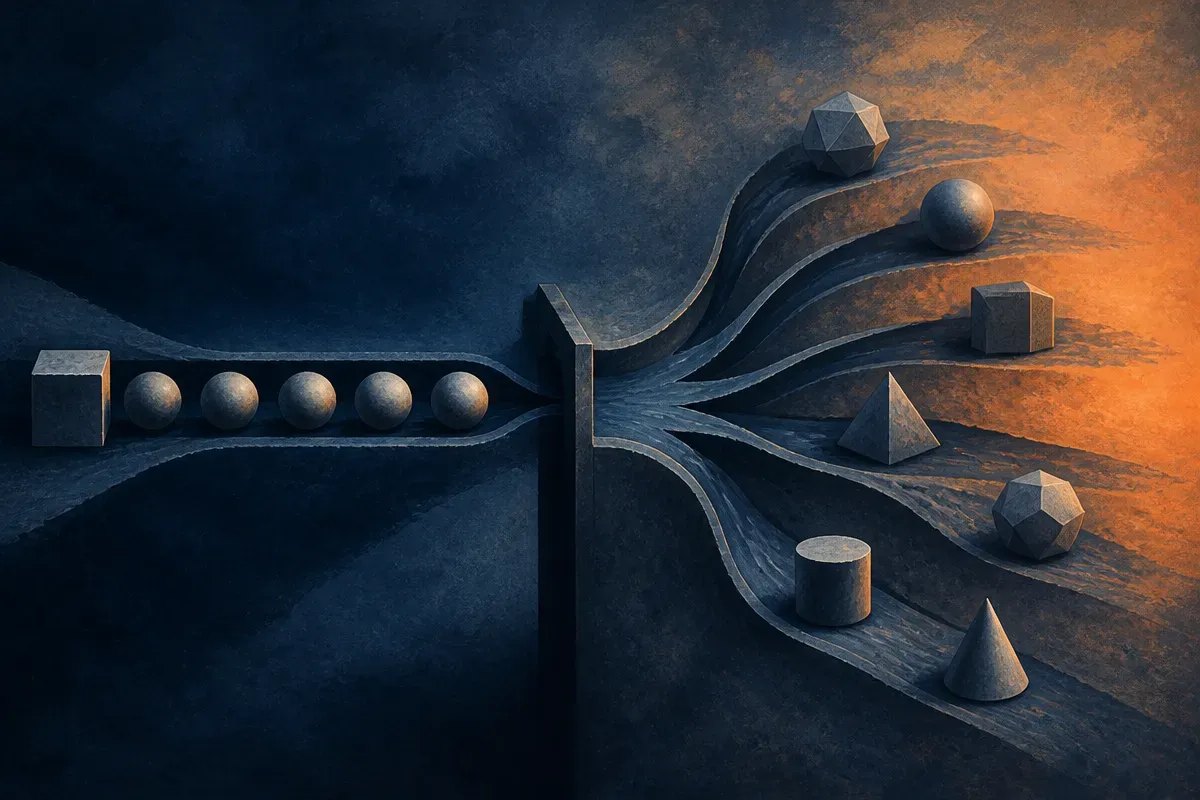
TextSeal, the predecessor, patched this by flipping a coin per token and routing to one of two keys. Diversity comes back. But the authors are blunt that this is suboptimal: the detector does not know which key was used for each token, so it averages the scores from both keys. Averaging dilutes the signal. You pay for diversity in detection strength. That tradeoff is the real subject of this paper.
How does copula mixing beat the two-key coin flip?
Instead of flipping between two keys and hoping, TextSeal2 merges two or more keys into a single virtual key. Then it couples that virtual key to fresh noise through a Gaussian copula borrowed from a scheme the authors call AutoMark. The copula is the mechanism that lets you blend multiple keys into one coherent signal the detector can read directly, instead of reading each key separately and averaging.
The practical payoff: you can merge any number of keys, including publicly shared ones, without diluting detection. That public-key angle is underrated. A lot of watermark deployments want to let third parties verify text without handing over the master secret. If merging keys cost you detection power, public verification would always be the weak version. Here it is not supposed to be.
The numbers they report back this up. At equal output token diversity, TextSeal2 detects 8 to 22 percentage points more 100-token answers than TextSeal, measured at a false-positive rate of 10 to the minus 3. That false-positive bar matters as much as the detection rate. One in a thousand is the kind of threshold you need before you would accuse real text of being machine-generated, and short text is the hard case because there is less signal to find. The authors also report it as comparable to a scheme called textGrain while requiring no post-logits optimization, meaning you do not have to run an extra tuning step on the model’s output probabilities to get there.
Why does speculative decoding break other watermarks?
This is the part I care about most, because it is where theory meets what labs actually ship.
Speculative decoding is the dominant speed trick for serving LLMs now. A small, cheap draft model proposes several tokens ahead. The big target model checks them in parallel and accepts the ones it would have produced anyway, rejecting and replacing the rest. You get the target model’s exact distribution at a fraction of the latency. Everyone serving at scale uses some version of it.
The problem for watermarking: when the target model rejects a drafted token and substitutes its own, where does the watermark signal go? Naive schemes lose it. The replacement tokens are not keyed, so your watermark gets punched full of holes exactly where the target model intervened, and detection collapses.
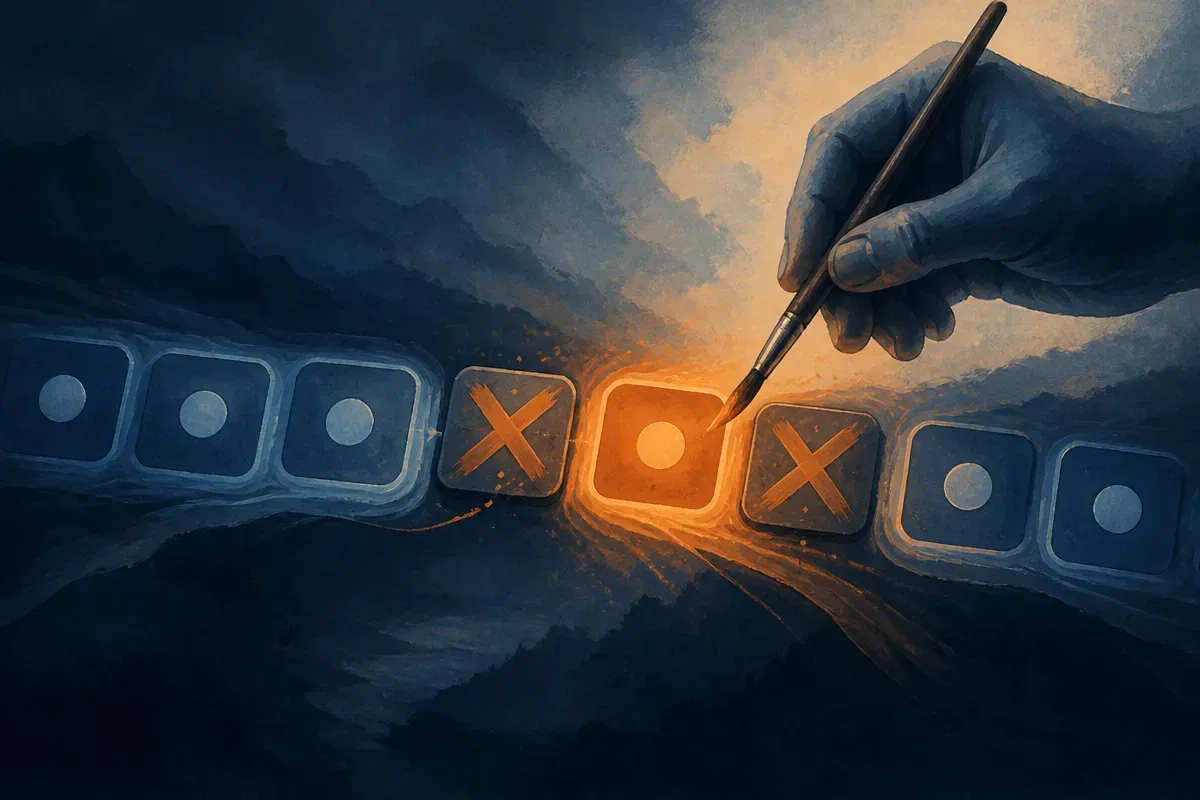
TextSeal2’s answer is the “memoryless races” half of the title. Keyed drafts get verified with one more exponential race, run on the leftovers of the draft races. Because the exponential distribution is memoryless, that extra race reproduces block verification exactly: the output still follows the target model precisely, the acceptance rate is unchanged, and the replacement tokens stay watermarked with the same keys. You keep the speed, you keep the fidelity, and the watermark survives.
The reported gains under speculative decoding are the headline: 18 and 22 percentage points more 200-token answers detected than TextSeal and textGrain respectively, at the same acceptance rate. In other words, under the serving setup most people actually use, the gap over prior work widens rather than narrows. That is the opposite of how most watermarking claims age.
What’s the catch?
A few honest caveats before anyone treats this as solved.
First, scope. This is an inference-time, sampling-based watermark. It assumes you control decoding and hold the keys. It does nothing about text that was paraphrased, translated, or run through another model to launder the signal. Robustness to that kind of attack is not what these numbers measure, and the abstract does not claim it.
Second, these are the authors’ own evaluations on three LLMs at specific token lengths and a specific false-positive rate. Watermark detection curves are sensitive to all three. Ninety-plus percent detection on 200-token answers tells you little about a 30-token reply, and short replies are where a lot of real abuse lives.
Third, watermarking only works if the generator opts in. It is a tool for a model provider who wants its own output traceable. It is not a detector you can point at arbitrary text from a model that never watermarked anything. The entire adversarial case, someone deliberately avoiding detection, sits mostly outside this design.
Practitioner’s take: if you serve an open model and you have been telling yourself you will add watermarking later, the speculative-decoding result is the reason to look now rather than after you have optimized latency. The old excuse was that any watermark worth having would either cost you output diversity or break under the exact speed optimizations you depend on, so why bother. TextSeal2’s claim is that you no longer have to choose: distortion-free, no measurable latency, signal intact through draft-and-verify. What to actually try: stand it up on your own stack, then test detection at the token lengths your product really produces, not the paper’s 100 and 200, and hold the false-positive rate at 10 to the minus 3 or stricter. The catch most readers will miss is that detection strength lives or dies on short outputs, so a chatbot that answers in two sentences is a very different deployment than one writing long documents. Measure your own distribution before you trust anyone’s percentage points, including these.