Project ProtoStar puts the boring data layer under science AI
Hugging Face’s Project ProtoStar is less about flashy model demos and more about preparing publicly funded science for AI systems. The real test is whether it improves licensing, provenance, structure, and reuse without turning public research into another messy training dump.
TL;DR: Hugging Face’s Project ProtoStar points at the right bottleneck for science AI: public research data needs to become usable, traceable, and legally clean before models can reliably build on it.
What does “AI-ready” science actually mean?
Hugging Face announced “Announcing Project ProtoStar: Making Publicly Funded Science AI-Ready,” and the important phrase is not “AI.” It is “ready.”
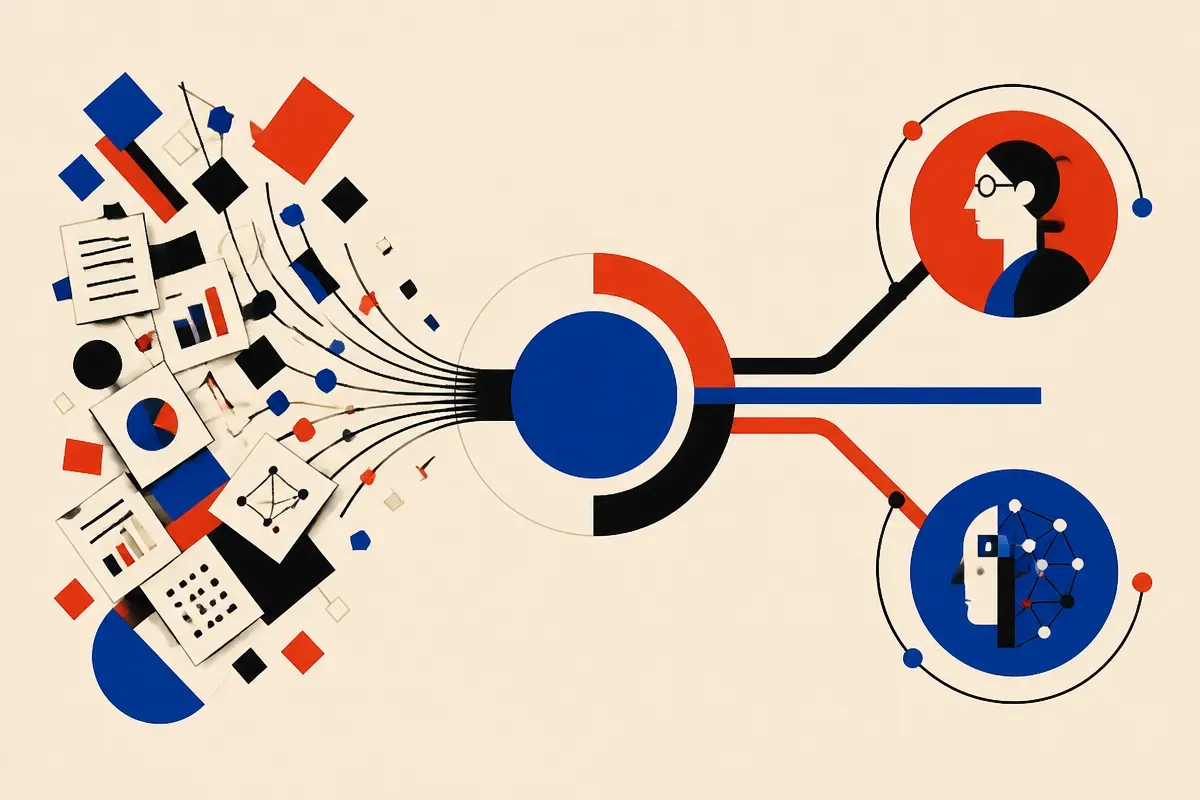
Most science data is not ready. It lives across PDFs, lab portals, supplementary files, institution pages, government repositories, spreadsheets, scanned tables, and formats that made sense to the person uploading them in 2017. A human graduate student can fight through that. A model pipeline usually cannot, at least not without dropping context, mangling units, losing provenance, or silently mixing incompatible records.
So the practical reading of Project ProtoStar is not “let’s train a science model.” It is closer to “let’s make publicly funded scientific output easier for models and people to use without guessing what anything means.”
That means boring things. Stable identifiers. Clear licenses. Machine-readable metadata. Version history. Dataset lineage. Known collection methods. Links between papers, code, data, and experiments. Formats that can be parsed without custom archaeology. Benchmarks that distinguish retrieval from reasoning from hallucinated lab confidence.
Boring is good here. Boring is where reliability comes from.
Why public funding changes the stakes
Publicly funded science has a different moral and operational shape than private data. Taxpayers already paid for much of it. Researchers cite it. Agencies archive it. Startups build near it. Universities train people on it. If AI systems are going to accelerate scientific work, public research data should not sit behind accidental friction.
But “public” does not mean “free-for-all training sludge.”
That is where projects like ProtoStar need discipline. The failure mode is easy to see: scrape first, normalize later, hope consent and attribution can be cleaned up downstream. That path is how we got a lot of today’s data fights.
The better path is slower and more useful. Make the rights machine-readable. Preserve attribution. Keep dataset versions visible. Mark limitations. Separate raw observations from processed summaries. Make it possible to exclude sensitive or restricted material before it enters a model workflow, not after the fact.
Hugging Face has credibility in open model and dataset distribution, but this category needs more than a hosting surface. Science data has weird edges: negative results, retracted papers, duplicated measurements, lab-specific notation, conflicting taxonomies, and methods sections that carry half the meaning. A dataset card is a start. It is not the whole job.
The model is not the product yet
The temptation will be to judge ProtoStar by the models it enables. I think that is too narrow.
The better test is whether a small lab, public agency, nonprofit, or builder can answer simple questions faster: Can I find the relevant dataset? Can I tell if I am allowed to use it? Can I reproduce the transform? Can I cite the original source? Can I compare two versions? Can I feed it into an agent or retrieval system without writing a custom parser every time?
If the answer becomes yes more often, the value compounds. Not in a press-release way. In a weekly workflow way.
Science AI does not only need bigger context windows and better reasoning models. It needs cleaner inputs. A brilliant model pointed at broken provenance and inconsistent metadata still produces fragile work. Sometimes faster fragility.
For builders, I would treat ProtoStar as a signal to audit your own scientific or technical data pipeline before chasing model upgrades. Pick one public dataset your workflow depends on. Track where it came from, what license covers it, what changed across versions, what fields are ambiguous, and what your model or agent does when those fields are missing. The catch most readers miss: AI-ready is not a file format. It is an operating practice.