What Samsung's On-TV TensorFlow Lite Tracker Tells You About Edge AI
A single Hacker News thread about a Samsung TV running a TensorFlow Lite model on a low-res frame says more about where inference is heading than most product launches. Here is what the on-device tracking claim actually means for builders and buyers.
TL;DR: A low-resolution model running quietly on your TV is not a scandal of scale, it is a preview of how much useful inference now happens on cheap hardware you already own, and that shift is the real story for anyone building with AI.
The primary source here is thin on purpose: a Hacker News (AI) thread titled “Samsung running a TensorFlow lite model on 960x540 image to track you.” That is all we have. No paper, no Samsung filing, no reproducible teardown attached. So I am going to be straight about what is claimed, what is plausible, and what you should not take as settled. The headline is a user claim, not a confirmed Samsung disclosure, and I am treating it that way throughout.
But the claim is interesting precisely because it is so mundane. A 960x540 frame. TensorFlow Lite. Tracking. None of those words are exotic anymore. That ordinariness is the point.
What is actually being claimed here?
The thread asserts that a Samsung device runs a TensorFlow Lite model against a downscaled 960x540 image to track something (a person, a face, a presence). I have not seen Samsung confirm this, and the Hacker News post does not link a teardown or packet capture that I can verify from the material given. So treat “Samsung is doing X” as reported-by-a-user, not documented fact.
What is technically credible, separate from whether this specific device does it:
TensorFlow Lite is Google’s runtime for running models on phones, TVs, and microcontrollers. It is built for exactly this: small models, low memory, no cloud round trip. A 960x540 input is deliberately cheap. That is roughly a quarter of 1080p, which keeps the compute and memory footprint low enough to run on a TV’s modest SoC without a dedicated GPU.
So the architecture described is not far-fetched. Running a lightweight vision model on a downscaled frame on an embedded chip is a 2019-era capability, not a 2026 breakthrough. If anything, the surprising part is that someone noticed and that it still reads as news.
Why does on-device inference change the privacy math?
Here is where the instinct (“they are tracking you”) and the engineering (“it runs locally”) point in different directions, and both can be true.
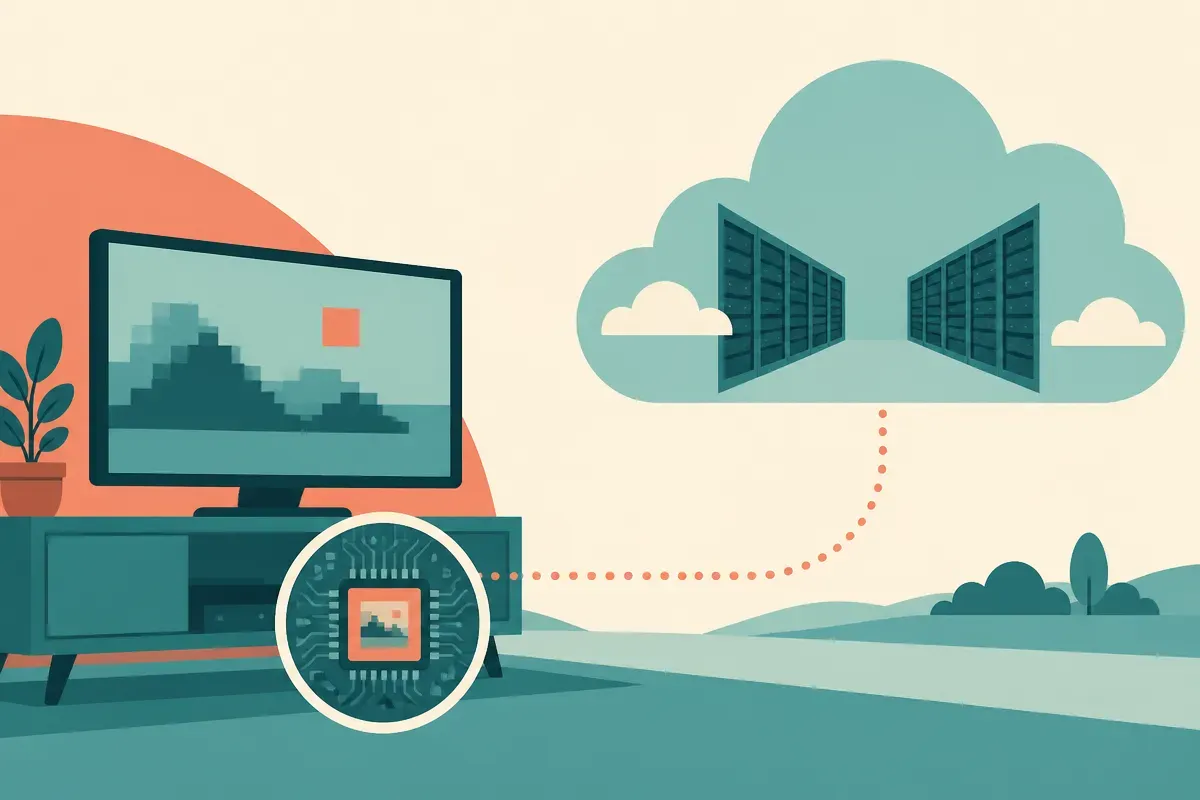
Running inference on-device is usually the privacy-preserving choice. The frame never leaves the box. No upload, no server-side storage of your living room. Apple has made this argument for years with on-device vision, and it holds: local processing means the raw data has fewer places to leak.
But “on-device” tells you where the math happens, not what happens to the output. A model can run locally and still emit a tiny signal (presence detected, viewer count, engagement state) that gets shipped off to an ad or analytics endpoint. The expensive, sensitive data (the actual image) stays home. The cheap, monetizable abstraction (a few bytes of metadata) travels. That is the pattern worth watching, and it is the one the Hacker News framing misses by focusing on the image resolution instead of the data flow.
So the honest read is: a local TFLite model is not inherently sinister, and it is not inherently safe. The question is always what leaves the device, not what runs on it. With only a forum post to go on, I cannot tell you which of those Samsung is doing. Neither can the thread.
What does this tell builders about where inference is heading?
Strip away the Samsung-specific anxiety and you are left with a genuinely useful signal for anyone building with AI.
The cost floor for “good enough” vision has collapsed. A model small enough to run on a TV SoC, on a quarter-resolution frame, can do real work: presence detection, coarse pose, person counting, gesture triggers. You do not need a datacenter. You do not even need a phone-class NPU. You need a quantized model and a cheap chip.
That reframes a lot of product decisions. If you are building something that senses the physical world, the default question used to be “how do I stream frames to the cloud affordably?” Now it is “how small can the model get so I never stream frames at all?” The second question is cheaper, lower latency, and easier to defend on privacy. TensorFlow Lite, along with ONNX Runtime and the broader edge stack, is why that flip is available to small teams and not just to a company with Samsung’s volume.
The catch: small and local does not mean accurate. A 960x540 model tracking a person in a dim room will have failure modes you cannot see from a spec sheet. If you ship edge inference, your eval burden goes up, not down, because you are now responsible for behavior across wildly varying hardware, lighting, and placement that you do not control. The convenience of local runs comes bundled with a longer tail of weird conditions.
How should you read claims like this one?
This is the part I care about most, because the thread is a case study in how edge-AI stories get told.
A single user observes a process name or a model file or a network blip. The claim becomes “device is tracking you.” It spreads because it confirms a prior we all hold about smart TVs. And it might be right. But the gap between “there is a TFLite model on this device” and “this device is tracking you and exfiltrating it” is enormous, and it is exactly the gap that a forum title papers over.
For an operator, the disciplined move is to separate three questions that usually get mashed together. One: is there a model running locally? (Often yes, and often benign.) Two: what is the model’s output? (Presence, count, identity, that is a huge range.) Three: what leaves the device, to whom, how often? (This is the only one that determines whether “tracking” is the right word.) The Hacker News post answers the first, guesses at the second, and never touches the third. So I would file it as plausible, unconfirmed, and useful mostly as a prompt to go look at your own devices’ outbound traffic.
Practitioner’s take: if you build anything that senses people or spaces, prototype on the assumption that the model runs on the edge, because in 2026 it probably can. Grab a quantized vision model, run it under TensorFlow Lite or ONNX Runtime on the cheapest board that will hold it, and measure accuracy across bad lighting and odd angles before you fall in love with the demo. Then do the thing every “they’re tracking you” thread skips: put the device on a network you monitor and watch what actually leaves it. The product lesson from this Samsung claim is not that edge AI is creepy. It is that the compute to sense the world is now so cheap it hides in a TV, which means your real design work is deciding what crosses the boundary off the device. That decision, not the model, is where trust is won or lost.