Nanbeige4.3-33B is really a small-model bet
Nanbeige’s 33B release is framed as stronger than a 27B Qwen baseline, but the more useful operator angle is its role as a teacher model for future 3B distillations.
TL;DR: Nanbeige4.3-33B is less interesting as another mid-size leaderboard model and more interesting as a teacher model meant to produce smaller, cheaper 3B models.
What did Nanbeige actually release?
The primary source is the Hugging Face model page, “Nanbeige/Nanbeige4.3-33B · Hugging Face.” Nanbeige frames Nanbeige4.3-33B as stronger than Qwen3.8-27B across a range of benchmarks, and says the 33B model lays the foundation for an upcoming small-model distillation pipeline, including Nanbeige4.3-3B.
That is the important part.
A 33B model is not tiny. It is not the kind of thing most teams casually run everywhere, especially if they care about latency, memory, cost, or private deployment on modest hardware. But a 33B teacher can be useful if it produces smaller students that retain enough task skill to be worth deploying.
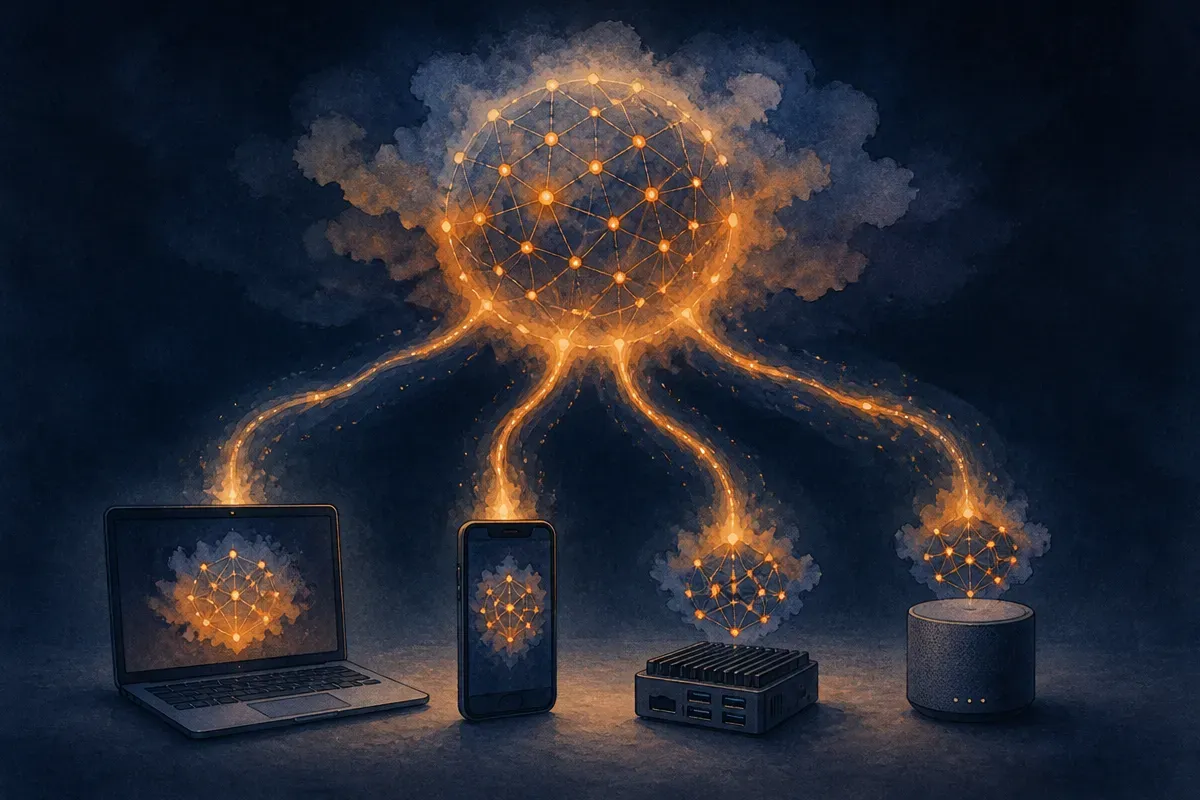
The r/LocalLLaMA reaction points in the same direction: the community interest is not only “new model beats older model.” It is “this may get distilled into 3B models, maybe other sizes too.” That is the practical open-source AI story right now. The big model is often the factory. The small model is the product people can actually ship.
Why does the 3B target matter?
A 3B model lives in a different operational category than a 33B model.
It can be easier to run locally. Easier to fine-tune. Easier to bundle into narrow products. Easier to test in high-volume workflows without turning inference into the whole budget. That does not make it magically good. Small models fail in very specific ways. They get brittle. They overfit task formats. They can look great on short evals and then fall apart when a user asks the same thing sideways.
But if Nanbeige can use a stronger 33B checkpoint to distill a capable 3B model, that matters more than another claim about beating a 27B baseline. Distillation is one of the more useful paths for teams that want model behavior without carrying full model cost. The teacher generates behavior, examples, reasoning traces, preferences, or target outputs. The student learns the pattern at a smaller scale.
The catch is that “distilled from a stronger model” is not the same as “good for your workflow.” A 3B code assistant, a 3B customer support classifier, a 3B extraction model, and a 3B local writing helper are different products. The distillation recipe matters. The data matters. The evals matter. So does the intended deployment surface.
What should builders watch before caring?
Benchmarks are a starting signal, not a buying decision. Nanbeige reports stronger performance than Qwen3.8-27B across a range of benchmarks, but the source material here does not give enough detail to judge which tasks improved, by how much, or whether the gains transfer to messy production use.
That is not a knock on Nanbeige. It is the normal state of model releases. Most leaderboard claims compress too much into one sentence. Builders need the boring layer underneath: exact benchmark names, prompt format, inference settings, contamination checks, license terms, quantization behavior, context handling, tool-use quality, and failure cases.
For me, the signal to watch is whether Nanbeige4.3-3B ships with usable artifacts around it. Not just a model file. I mean example prompts, eval reports, recommended quantizations, known weaknesses, and task-specific comparisons against other small models. A small model with clear limits is often more useful than a larger model with vague wins.
If I were testing this, I would not start with the 33B benchmark claim. I would wait for the 3B distillation, then run it against a narrow internal eval: 100 to 300 real examples from the workflow, with expected outputs and failure labels. Try extraction, classification, short generation, and whatever edge cases break your current setup. The catch most readers miss: small models do not need to be generally impressive. They need to be boringly dependable on one job you run a lot.