Cerebras Says It's Running Trillion-Parameter Models: What That Actually Means for Builders
Cerebras is claiming it can serve trillion-parameter models on its wafer-scale hardware, a direct shot at the GPU cluster. Here is what the claim means for inference speed, cost, and the builders who might care.
TL;DR: Cerebras says it can serve trillion-parameter models on its wafer-scale chips, and if the speed and cost hold up outside demos, the interesting part is not the parameter count but the latency: fast inference on huge models changes which agent workloads are actually practical.
The primary source here is thin. It is a Hacker News post pointing to a Cerebras announcement titled “Cerebras Deploys Trillion-Parameter AI Models.” That is worth saying plainly up front, because the specifics that matter (tokens per second, price per million tokens, which exact models, who gets access) are the kind of first-party claims that belong to Cerebras and should be read from Cerebras directly, not inferred from a headline. So this post is about what the claim means and how to pressure-test it, not a victory lap on numbers I cannot verify.
What is Cerebras actually claiming?
Cerebras builds wafer-scale chips. Instead of cutting a silicon wafer into many small GPUs, they keep the whole wafer as one enormous processor, the Wafer Scale Engine, with a huge amount of on-chip memory and bandwidth. The pitch has always been that this layout avoids the bottleneck that defines GPU clusters: moving weights and activations across many small chips over comparatively slow interconnects.
The trillion-parameter headline is the natural next escalation of that pitch. A model that size does not fit on a single conventional GPU. You shard it across dozens or hundreds of them, and a lot of your inference time goes to communication overhead between those chips. Cerebras is claiming its architecture lets it serve models at that scale with far less of that penalty, which is where their speed numbers in previous launches came from.
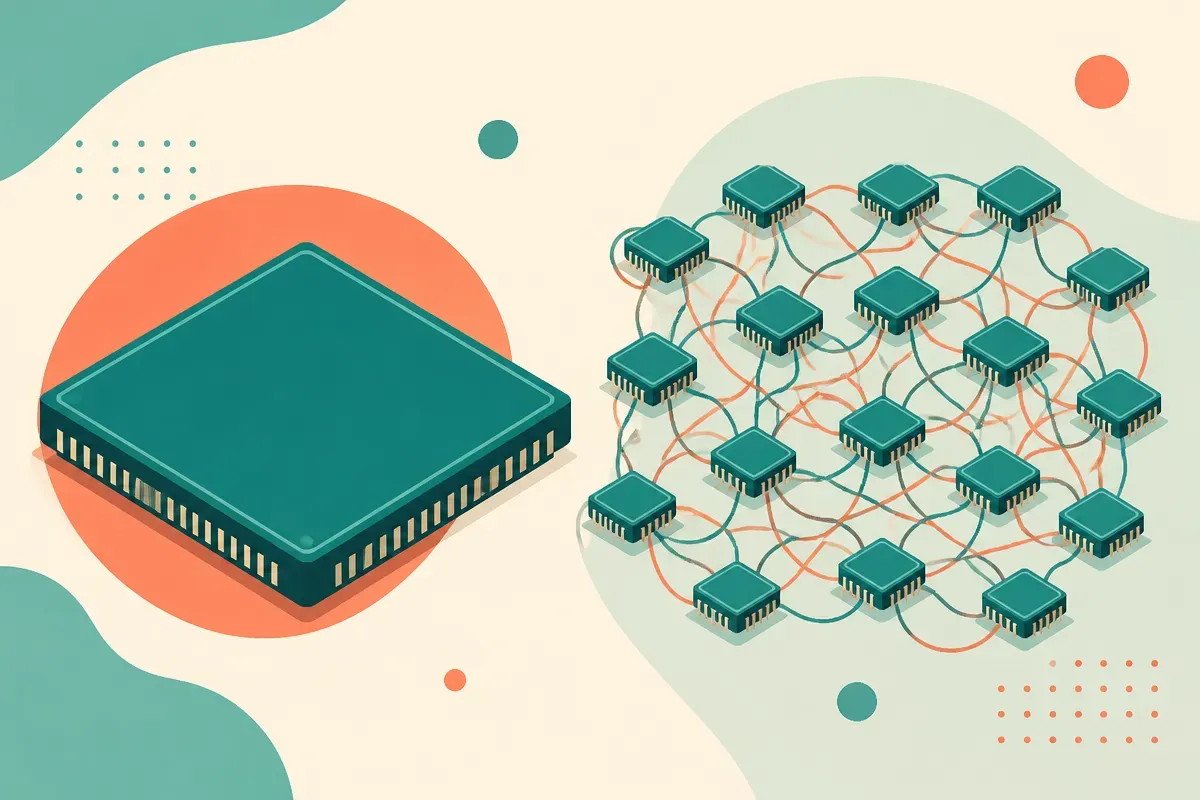
That is the mechanism to understand. Whether the trillion-parameter deployment delivers the same speed advantage Cerebras showed on smaller models is exactly the thing to check in their own benchmarks and, more importantly, in independent ones.
Why does inference speed matter more than the parameter count?
Here is the part the headline buries. Trillion parameters is a flex, but on its own it is not useful to most builders. Bigger models are not automatically better for a given task, and plenty of production work runs fine on much smaller ones.
The number that actually changes what you can build is tokens per second at acceptable cost. Cerebras has historically competed on raw inference speed, serving models at hundreds to over a thousand tokens per second where GPU-based APIs deliver far fewer. If they can do that on a frontier-scale model, the use cases that open up are the ones currently blocked by latency.
Think about agent loops. An agent that plans, calls a tool, reads the result, and plans again is paying the model’s latency on every single hop. At fifty tokens per second, a ten-step agent task feels like watching paint dry, and you start caching and cutting corners to make it bearable. At ten times that speed, the same loop finishes while the user is still looking at the screen. Long reasoning chains, where the model thinks for thousands of tokens before answering, have the same shape. Speed is not a nicety there. It decides whether the workflow is shippable.
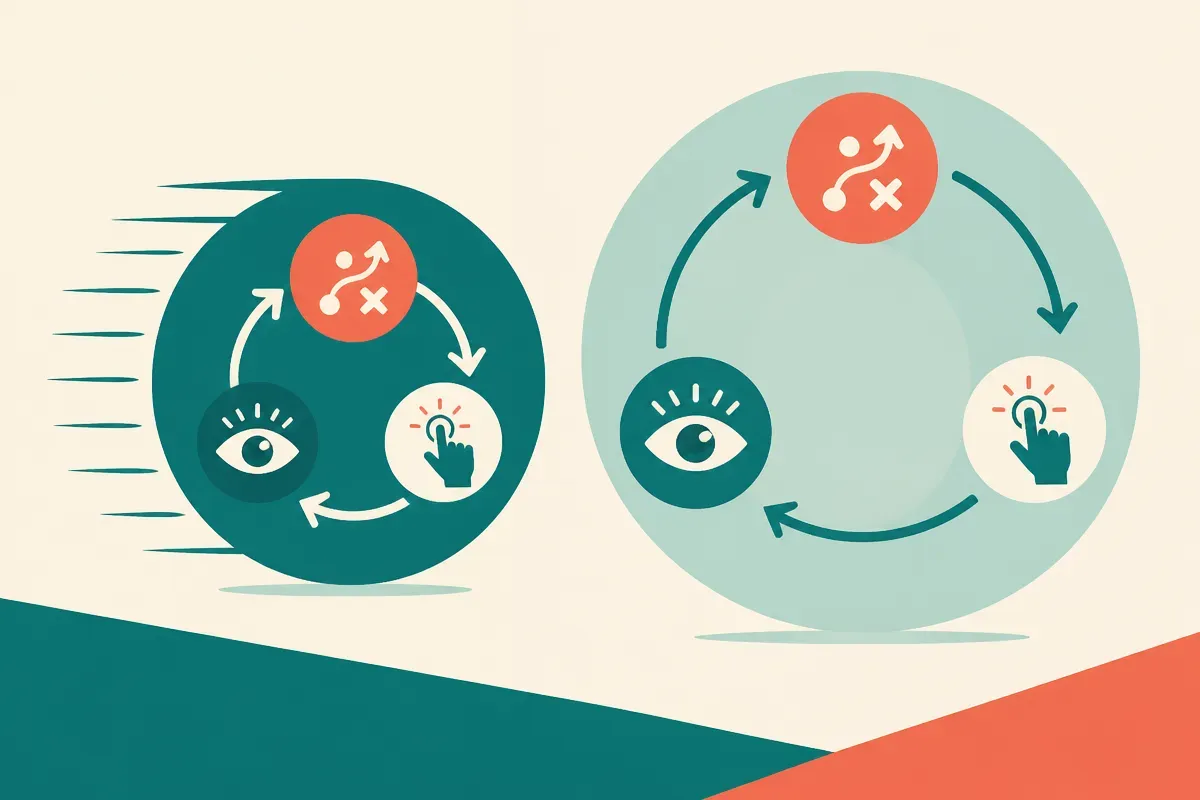
So the real question for a builder is not “can it run a trillion parameters” but “what does a reasoning-heavy, multi-step job cost and how fast does it return.” Those are the numbers to demand.
What should you not assume from this announcement?
A few things, because the gap between a deployment announcement and a dependable production dependency is wide.
Access and pricing are unknown from the material I have. Cerebras has run both a cloud inference API and sold on-prem systems to large customers. A trillion-parameter deployment could mean a public endpoint you can call tomorrow, or a flagship capability reserved for a handful of enterprise and government buyers. Do not assume the former. Read Cerebras’s own availability terms before you design around it.
Which models are deployed matters too. “Trillion-parameter” is a size class, not a specific model. Serving a particular open-weight model at that scale is a different thing from serving a frontier closed model, and the quality you get depends entirely on which one it is. The headline tells you nothing about this.
And benchmarks from a vendor are a starting point, not a verdict. Cerebras’s past speed claims have generally held up in third-party testing, which earns them some credibility here. But “generally held up at smaller scale” is not the same as confirmed at trillion-parameter scale. Throughput can degrade in ways that only show up under real concurrent load, long contexts, and messy production prompts. Wait for someone outside the company to run it before you bet a roadmap on it.
What would a builder actually do with this?
The honest answer right now is: watch and test, do not rebuild.
If you run latency-sensitive agent or reasoning workloads today and you are capped by how slow your current API returns tokens, Cerebras is worth a controlled bake-off the moment there is an endpoint you can hit. Run your actual traffic, not their demo prompts. Measure end-to-end time on your real multi-step tasks, cost per completed task rather than per token, and output quality against whatever model you ship now. Speed that comes with a quality drop you did not notice is a trap.
The catch most people will miss is the lock-in question. Wafer-scale is a genuinely different platform. If the speed is real and you build your product’s core loop around it, you are now dependent on one vendor’s hardware availability and pricing in a way you are not when you can swap between half a dozen GPU-based providers serving the same open model. That portability is worth something. Weigh the latency win against it honestly, keep an abstraction layer between your app and the provider, and make sure you could fall back to a GPU-served version of the same model if you had to. The fastest inference in the world is still a risk if there is exactly one door to it.
So: an interesting claim from a company with a track record of backing its speed numbers, aimed squarely at the thing that actually limits agent and reasoning products. Promising enough to test. Not yet proven enough to build on. Get the first-party specifics from Cerebras, run your own numbers, and keep an exit.