CausalCoT treats chain-of-thought as a dependency graph
CausalCoT argues that ordinary chain-of-thought can explain after the fact, because each step can still see too much context. Its fix is not a bigger model or longer prompt, but isolating reasoning steps so local corrections actually change downstream answers.
TL;DR: CausalCoT is useful because it attacks a real failure mode in chain-of-thought: the model can produce plausible reasoning while the answer actually comes from leaked global context.
Why can chain-of-thought look faithful when it is not?
The primary source here is “Causal Chain of Thought: Mitigating Attention Leakage via Context Isolation,” posted on arXiv in cs.AI and cs.LG. The core claim is simple and uncomfortable: chain-of-thought is not automatically a causal explanation.
That matters. A model can write a neat step-by-step rationale, but standard autoregressive generation gives each step dense attention over the full context. So an intermediate “reasoning” step may not be doing the work it appears to be doing. It can attend directly to information elsewhere in the prompt, land on the answer, then generate a rationale that looks sensible after the fact.
This is the gap between explanation as theater and explanation as mechanism.
The paper frames that failure as attention leakage. I like that term because it points to something operational, not philosophical. If every step can see everything, then you do not know whether step three depends on step two, or whether both are independently peeking at the same original evidence. For audit trails, agent workflows, grading systems, and high-stakes decision support, that is a problem.
What does CausalCoT change at inference time?
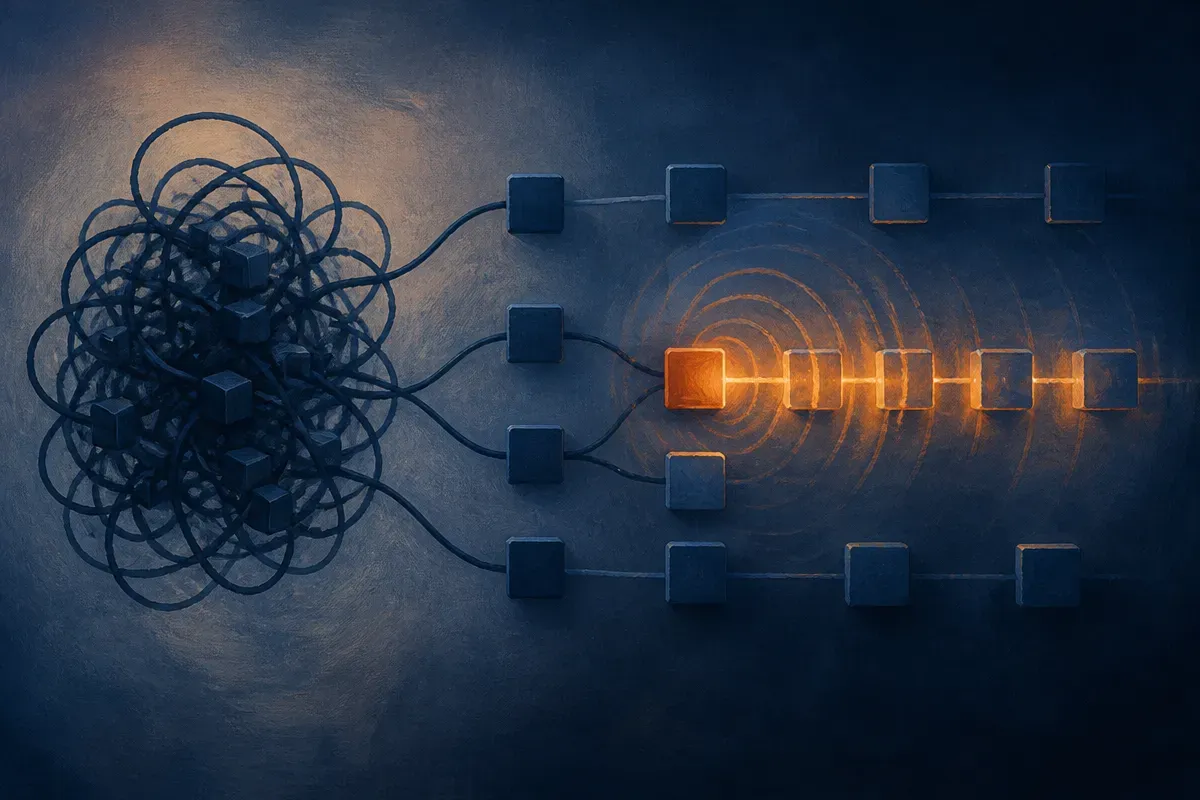
CausalCoT turns the reasoning process into a directed acyclic graph of atomic sub-questions. Each node is evaluated in isolation, with access only to its direct causal parents.
That is the important move. The framework does not just ask the model to “reason carefully.” It changes the context available to each piece of the reasoning process. If a node should only depend on two earlier conclusions, it only gets those two inputs. No full prompt. No hidden shortcut through all available evidence.
The arXiv abstract says this Markovian structure removes attention pathways to non-parent content, which should make later predictions more sensitive to local reasoning rather than global lookup. It also says CausalCoT preserved competitive predictive performance across a diverse suite of reasoning benchmarks while improving explanation faithfulness, with causal sensitivity of intermediate steps up by an average of 12 percentage points and as much as 21 percentage points over the strongest baseline.
That is a meaningful number, with one caveat: the provided material does not name the benchmark suite, models, tasks, or baseline. So I would treat the result as promising, not settled. The mechanism is the thing to pay attention to.
Where would this actually help builders?
The most practical piece is test-time intervention. If reasoning is represented as a dependency graph, a human or another model can correct one local node and watch the correction propagate downstream. That is much cleaner than asking the model to regenerate everything with “try again.”
This maps well to workflows where the answer is less important than the structure that produced it. Think legal issue spotting, medical triage summaries, financial document analysis, incident reports, enterprise policy QA, or complex research synthesis. In those settings, a plausible rationale is not enough. You want to know which intermediate claim changed the final recommendation.
There is a cost. Someone, or some system, has to decompose the task into atomic sub-questions and dependencies. That graph construction is itself a modeling problem. If the graph is wrong, the isolation can hide relevant evidence rather than prevent leakage. And if the model is weak at a required sub-question, the graph will faithfully propagate bad local work.
Still, this is the right direction. Chain-of-thought prompting has been treated too often as a magic transparency layer. CausalCoT treats it as an interface that needs constraints.
For a builder, I would try this first on one repeatable workflow where you already know the intermediate checks: claim verification, eligibility review, compliance screening, support escalation. Build a small dependency graph, run each node with only its parent outputs, then add a review point where a person can edit one node and rerun the affected downstream nodes. The catch most teams miss: this is not mainly a prompt trick. It is a workflow design pattern for making reasoning inspectable enough to debug.