Adaptive Depth in Recommenders: What LoopRec Changes
A new recommendation paper argues most items in a user's history need shallow processing while a critical few need full depth, and proposes a gate that decides per item. Here is what that means for anyone running a recommender in production.
TL;DR: A recommender does not need to think equally hard about every item in your history, and a paper called LoopRec shows you can learn, per item, when to stop computing and bank the savings without losing accuracy.
The paper is “Think Harder Where It Matters: Item-Level Adaptive Recursion for Sequential Recommendation,” posted across arXiv’s cs.AI, cs.CL, and cs.LG listings, with code at github.com/Elpmis117/LoopRec. It is a narrow, practical idea dressed in modest language. I think the idea travels further than recommendation, which is why I want to sit with it.
What is actually broken in a normal sequential recommender?
Sequential recommenders predict what you will click next by reading your interaction history in order. The standard design runs every item in that history through the same stack of layers. Same depth, same compute, whether the item is a throwaway impulse click or a strong signal about what you want.
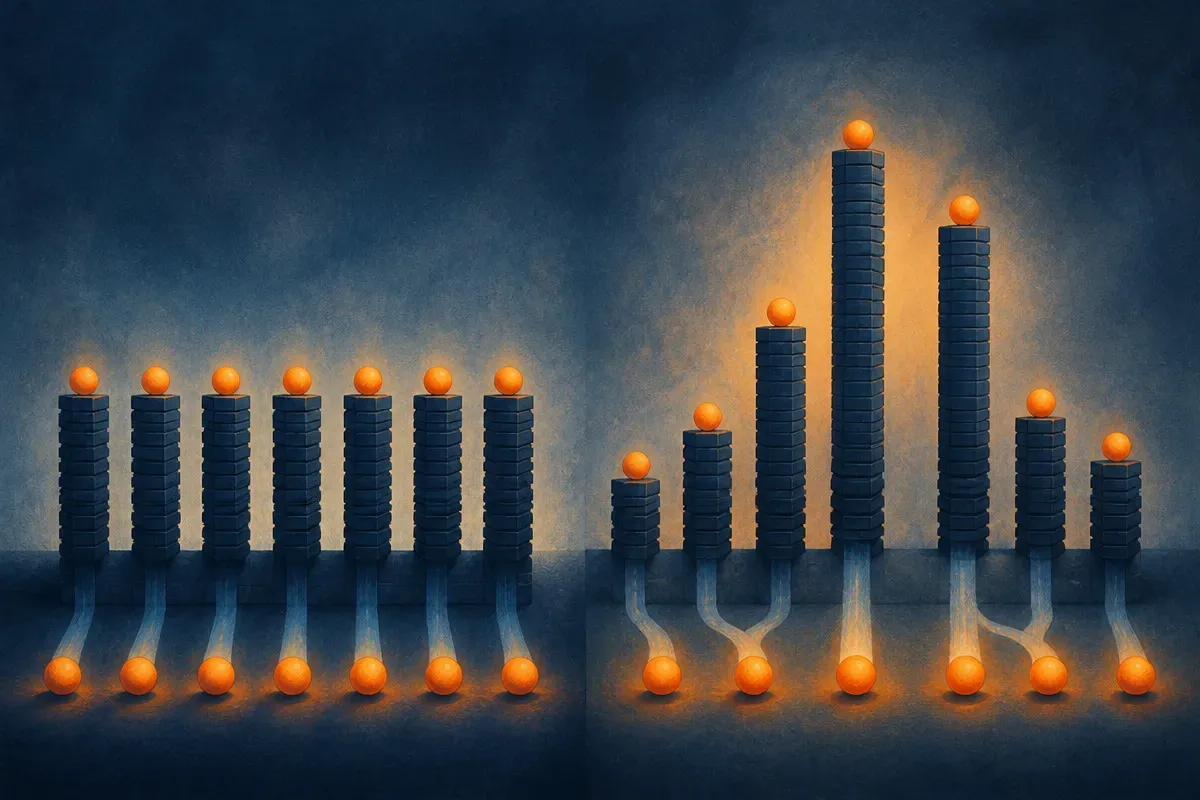
The authors call this out with two findings. First, non-uniform computational need: items in the same sequence vary a lot in how much processing they require. Most settle after shallow passes. A small minority only stabilizes at full depth. Second, suboptimality of fixed allocation: if you had an oracle telling you the target item, assigning depth non-uniformly consistently beats assigning it uniformly. So the fixed design is doing two things wrong at once. It burns compute on items that already converged, and it caps quality by not going deep enough on the items that matter.
That second point is the one people skip. This is not only an efficiency story. Uniform depth is leaving accuracy on the table, because the items that need more reasoning do not get it.
How does LoopRec decide when to stop?
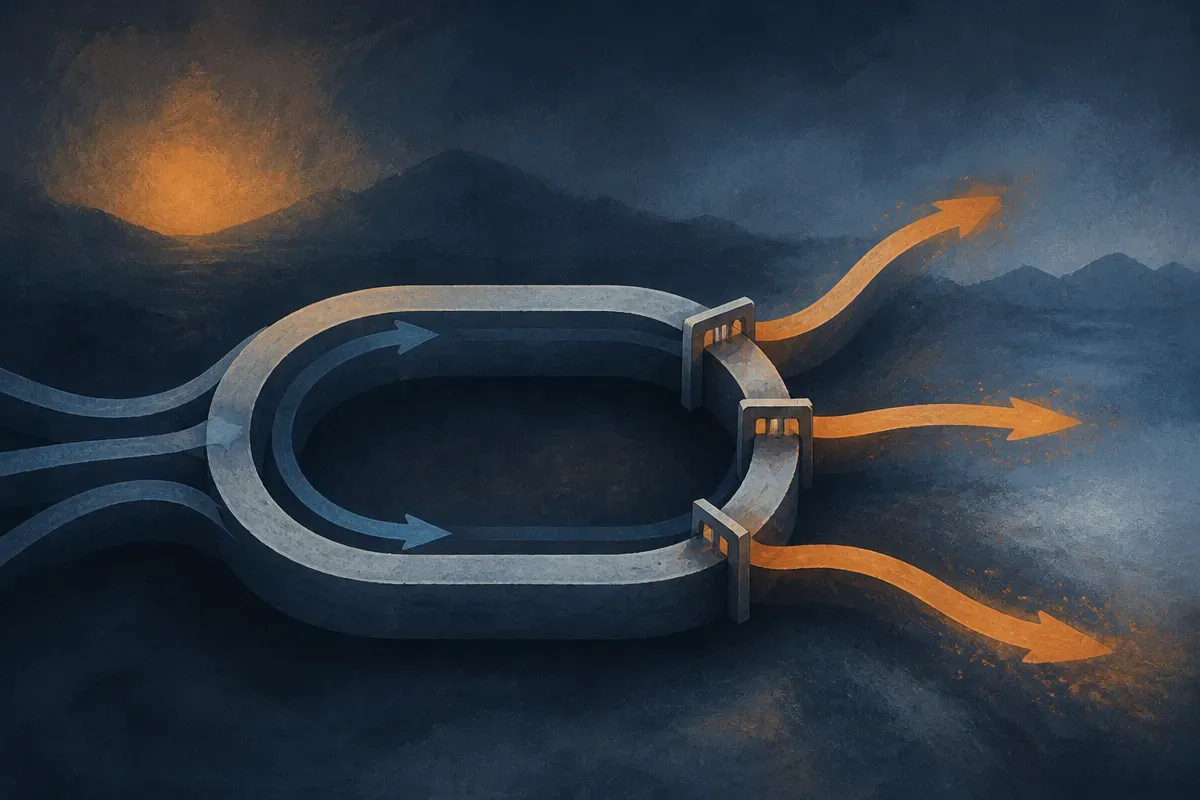
LoopRec takes a single block of weights and applies it recursively. Instead of stacking twelve different layers, you loop one shared block up to some maximum number of times. At each loop boundary there is a lightweight gate that makes a binary call for every item independently: exit now, or continue.
Items whose representations have matured drop out early. Items that still need work keep looping. The depth any given item gets is no longer a fixed global number. It becomes a learned, per-item property.
The part I find clever is that there are no depth labels. Nobody hand-annotates which items deserve deep processing. The gate learns the exit policy from the same training signal that trains the recommender. That matters because the alternative, supervising depth directly, would require exactly the oracle knowledge you do not have at inference time.
Weight sharing is doing quiet work here too. Because the same block runs every loop, the parameter count does not balloon with depth. You pay in compute for the items that loop more, not in model size. That is a very different cost curve from a deeper fixed network.
Is this different from early exit, and does it hold up?
Early exit is an old idea. Let easy inputs leave the network sooner. What is new here is the granularity and the framing. The exit decision is per item inside a sequence, not per whole input, and the depth is realized by looping a shared block rather than skipping over distinct layers. So an item’s final representation can come from one pass or many passes through the same weights.
The authors report that LoopRec beats matched fixed-depth versions across public benchmarks on four backbone families. The matched part is the right comparison: same backbone, same budget baseline, adaptive on top. And the learned allocation lines up with their oracle analysis. Lower-frequency items and more recent interactions get more depth. That is a sanity check I trust more than a raw accuracy delta, because it means the gate learned something interpretable rather than gaming a metric. Rare items are harder to pin down, so they should need more thinking. Recent interactions carry more signal about the next action, so spending on them pays off.
What the abstract does not give me: the actual numbers. No accuracy percentages, no FLOP savings, no latency figures, no per-dataset breakdown. So I am treating “consistently outperforms” as the authors’ claim, not a settled fact. The code is public, which is the right move and the only way anyone confirms this on their own data. Until someone reproduces it on a non-benchmark catalog, I would file this as a strong, testable hypothesis rather than a drop-in win.
Where else does per-item adaptive depth matter?
This is the part worth zooming out on. “Spend compute where the input is hard” is the same instinct behind reasoning models that think longer on harder prompts. LoopRec is that instinct pushed down to the token level inside a sequence model, with the budget controlled by a learned gate instead of a sampling trick.
For anyone running retrieval, ranking, or any pipeline that processes a list of things, the lesson generalizes. Most of your inputs are easy. A minority carries the outcome. If your system treats all of them the same, you are overpaying on the easy ones and underthinking the hard ones at the same time. The fix is not a bigger model. It is a cheap mechanism that routes depth to where it moves the answer.
That framing also connects to ranking problems outside recommendation. Search relevance has the same shape: most candidate documents are obviously off, a handful are genuinely close, and the close ones deserve the hard look. I spend a lot of time on search visibility through the website and SEO work I do at Lucky Domains, and the pattern holds there too. The marginal effort belongs on the few pages and queries where the ranking is actually contested, not spread flat across everything.
Practitioner’s Take
If you run a sequential recommender, the thing to try is not to rewrite your stack. It is to instrument it. Measure, per item, how much your representations change between layers. If most items converge early and a few keep moving, you have the exact condition LoopRec exploits, and a shared-block loop with a learned gate is worth prototyping against your current fixed-depth baseline on your own data. Clone the repo, reproduce one backbone on one public set first, then swap in your catalog.
The catch most readers miss: adaptive depth makes latency variable. A fixed network has predictable per-request cost, which is easy to capacity-plan. A gated loop can spike when a batch is full of hard items, and ragged compute across a batch is annoying to schedule on a GPU. The accuracy and average-compute story can be real while the tail-latency and serving story quietly gets harder. Budget for that before you fall in love with the average.