When Renaming a Tool Breaks Your Agent: What CIPR Fixes
A new arXiv paper shows LLM agents lose nearly 25% accuracy when you rename an action or change notation, even though the task is identical. Cross-Interface Policy Regularization recovers most of it. Here is why that matters for anyone shipping function-calling agents.
TL;DR: An LLM agent that aces your tool-calling suite can lose nearly 25% accuracy the moment you rename an action or tweak the notation, and a self-supervised training trick called CIPR recovers about 10.5% of that without hurting performance on the original interface.
The paper is “One Task, Many Interfaces: Simple Cross-Interface Consistency Training Improves LLM Agent Robustness,” posted across arXiv’s cs.AI, cs.CL, and cs.LG listings. It names the exact failure a lot of us have felt but never isolated: the agent did not learn the task, it learned the interface.
Why does renaming a tool make an agent worse at the same task?
Here is the uncomfortable part. You post-train an agent to call functions. It gets good. Then you rename search_flights to flight_lookup, or you swap JSON for a different notation, and accuracy drops. The task did not change. The flights are still the flights. But the agent’s competence was bound to the surface form it saw during training.
The authors call these “semantics-preserving perturbations.” Rename an action, change the notation, keep the meaning identical. On agentic function calling, held-out versions of these perturbations cut a post-trained agent’s accuracy by nearly 25%. That is not a rounding error. That is the difference between a demo and a product.
The reason is subtle and worth sitting with. When you train by scoring each sample on its own, the model has no pressure to treat two names for the same action as the same thing. It just memorizes that, in this distribution, this string maps to this behavior. The binding is to the token, not the function.
Doesn’t interface randomization already solve this?
This is the clever objection the paper heads off directly, and it is the part most people get wrong.
The obvious fix: show the agent many interfaces during training. Randomize the names, vary the notation, let it see variety. Surely then it generalizes.
No. The authors argue that scoring each sample independently means randomization only broadens the dependence. You go from being bound to one interface to being bound to the training interface distribution. The agent gets good at the names it saw, including the shuffled ones. But any out-of-distribution perturbation, a name or notation you did not sample, still degrades it. You widened the trap, you did not remove it.
That matters because interface randomization is the thing most teams would reach for first. It feels like data augmentation, which usually works. Here it treats the symptom and misses the mechanism. The mechanism is that nothing in the loss tells the model two interfaces are the same task.
What does CIPR actually do differently?
Cross-Interface Policy Regularization, CIPR, changes the objective instead of the data. Two moves.
First, it strips the meaning out of action names. It replaces them with uninformative identifiers, so the model cannot lean on a descriptive string to figure out what an action does. It has to reason from context and structure.
Second, and this is the core, it presents each training sample under two interfaces where equivalent actions are matched by construction. Then it penalizes the KL divergence between the action distributions the agent produces under each interface. In plain terms: if the task is identical, the agent’s choices should look identical, no matter how the actions are named or notated. CIPR makes “behave consistently across interfaces” an explicit part of what the model is optimized for.
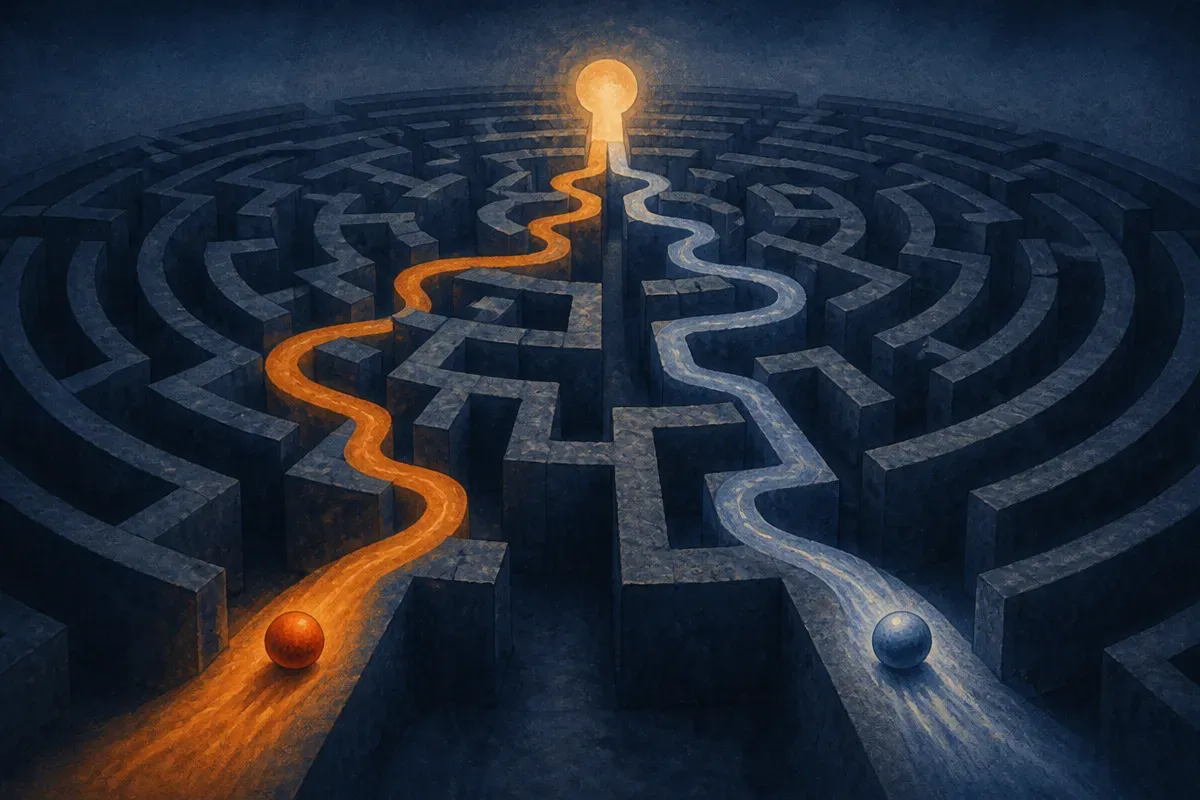
That is the difference from randomization. Randomization says “here are more interfaces, figure it out.” CIPR says “these two interfaces are the same, and I will punish you when your behavior diverges.” One hopes for invariance as a side effect. The other trains it as the objective.
It is self-supervised, which matters for cost. You are not hand-labeling equivalences. The two-interface pairing is constructed, and the KL term does the work. The authors test it in both supervised post-training and reinforcement-learning post-training, and report improved robustness in both settings.
How much does it recover, and what’s the catch?
The headline number: against held-out interface perturbations that knocked nearly 25% off accuracy, CIPR recovers 10.5%. And it does so while leaving accuracy on the unchanged interface intact. That last clause is the one I would underline. A lot of robustness methods buy generalization by sacrificing peak performance. This one, as reported, does not tax the original interface.
Now the honest accounting. Recovering 10.5% of a nearly 25% drop means you are still down. This is not a cure, it is a large partial fix. The agent is meaningfully more robust, not bulletproof. If your production interface drifts far enough from training, you will still see degradation.
Two more caveats worth stating. The results are on agentic function calling, which is the right place to test this but is one domain. I would want to see how the KL penalty behaves on longer, multi-step agent trajectories where errors compound, not just single function-calling decisions. And the paper, as posted, is the same abstract across three arXiv categories. I am reporting the recovery figures as the authors state them, not as independently reproduced.
Practitioner’s Take
If you ship function-calling agents, the first thing to do is not adopt CIPR. It is to run the diagnostic the paper implies you are skipping. Take your passing eval suite, rename every tool to a meaningless identifier, change the argument notation, and re-run. If accuracy craters, you now know your numbers measure interface memorization, not task competence. Most teams have never run this test and are quietly shipping the fragile version.
That diagnostic is free and tells you whether this problem is yours. If it is, the lesson generalizes even before any CIPR implementation lands in your stack: stop relying on interface randomization alone as your robustness story, because it widens the trap instead of closing it. The transferable idea is the consistency objective. When you have two representations of the same task, make matching behavior across them something you explicitly optimize or at least test for, not something you hope falls out of variety.
The catch most readers will miss: “semantics-preserving” is doing heavy lifting. In the real world, renaming a tool sometimes does change its meaning, or signals a different expected behavior to upstream systems. CIPR assumes a clean equivalence you construct. Your job is making sure the interfaces you pair really are the same task. Pair two things that are subtly different and you have trained your agent to be confidently, consistently wrong across both.