Temperature Should Read the Room
The arXiv paper 'Read the Room Before Your Model Generates' argues that LLM sampling temperature should adapt to the social and task setting, not sit as a fixed global knob. Useful idea, but the public summary leaves open the production questions builders actually need answered.
TL;DR: Fixed temperature is a blunt inference setting, and scenario-aware decoding looks like a practical path to models that shift tone, risk, and creativity based on what the task is asking for.
What changes if temperature is scenario-aware?
Most builders treat temperature like a personality dial. Set it low for factual answers. Raise it for brainstorming. Maybe pin it at 0.2 in production and call it a day.
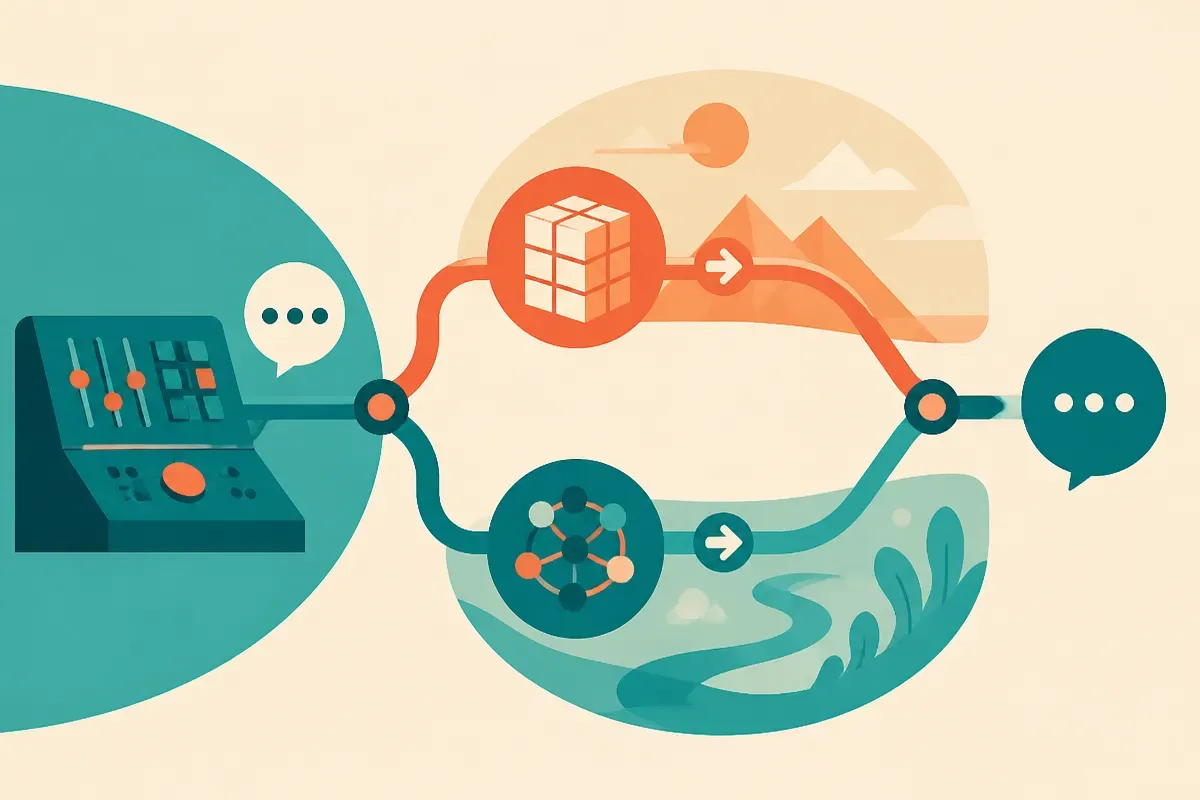
The arXiv paper “Read the Room Before Your Model Generates” argues that this is too crude. The paper introduces Scenario-Actor, a framework that chooses sampling temperature from an inferred representation of the communicative setting. In plain English: before the model generates, it tries to understand what kind of interaction it is in, then adjusts randomness to fit that situation.
That matters because “be creative” and “be careful” are not stable settings across a whole session. A support bot may need low variance while confirming a refund policy, then a little more flexibility when calming down an angry customer. A tutoring agent may need directness for arithmetic and more exploratory language when helping a student reason through an essay.
The useful shift here is from temperature as a global config to temperature as a local control policy. Not just “this app uses 0.7,” but “this moment in this conversation calls for this degree of sampling risk.”
What did Scenario-Actor actually test?
“Read the Room Before Your Model Generates” reports experiments on Llama-3.1-8B-Instruct. Scenario-Actor extracts scenario-relevant structures from Transformer hidden states, turns them into a scenario embedding, then determines temperature from that geometric representation.
The paper reports strong goal-completion performance in interactive social scenarios, significant gains on open-ended instruction following, and competitive performance on multi-turn conversation against multiple baselines.
That is promising. It is also where I want more receipts. The supplied arXiv summaries do not include effect sizes, benchmark names, latency cost, implementation details, or failure cases. Those details matter because decoding tricks can look great on open-ended tasks and get messy when shipped into real user traffic.
The central claim is still interesting: models already carry situational information in hidden states, and that signal may be good enough to drive generation controls. If true, this is a cleaner approach than piling more prompt instructions onto every request. Prompts can ask the model to behave differently. Scenario-aware decoding changes the mechanics of how it samples.
Where would this matter in production?
I would not start by replacing every temperature setting in a live system. I would test this where fixed decoding already hurts.
Customer support is an obvious case. You want consistency on policy, but not robotic repetition in empathy or troubleshooting. Sales assistants are another. Too little randomness and they sound canned. Too much and they invent promises. Education, medical triage, legal intake, and internal enterprise agents all have the same pattern: the acceptable variance changes inside the same conversation.
The bigger point is that inference-time control is becoming a product surface. We talk a lot about bigger models and better post-training, but many product failures are smaller than that. The model had the right capability, then answered with the wrong degree of confidence, creativity, or social awareness.
Scenario-aware temperature is not a full reliability solution. It does not guarantee truth. It does not solve prompt injection. It does not prove the model understands the user. But it gives builders another control point between “rewrite the prompt” and “fine-tune the model.”
For a builder, the practical move is simple: log where your system needs different response styles inside the same workflow, then run an eval with dynamic temperature policies against your current fixed setting. Start with two or three scenario classes, not twenty. The catch most teams miss: temperature is not just about creativity. It is about matching variance to user risk, task ambiguity, and the social shape of the moment.