When a hallucination enters the context, can the model talk itself out of it?
PHRBench studies what happens after a false premise lands in an LLM's context across 4820 controlled cases, and finds that models rarely correct course once they accept bad information. Here is what that means for anyone chaining LLM calls together.
TL;DR: Once a false premise lands in an LLM’s context, most models go along with it, and PHRBench shows successful recovery is rare enough that you should treat error-containment, not error-correction, as your real defense in any multi-step system.
Hallucinations get studied mostly at the output stage: did the model make something up, how often, how bad. But in any real system, outputs become inputs. One agent’s wrong answer gets fed to the next step as fact. A RAG pipeline retrieves a bad chunk and the generator treats it as ground truth. The interesting question is not “did the model hallucinate” but “what does a model do when a hallucination is already sitting in its context, presented as true?”
That is the question PHRBench goes after, and the answer is not comforting.
What is PHRBench actually measuring?
The primary source here is PHRBench: A Behavioral Evaluation of Post-Hallucination Reasoning in LLMs, posted to arXiv under both cs.AI and cs.CL. The authors build a controlled benchmark for what they call post-hallucination reasoning (PHR): the behavior of a model after erroneous information has entered its context and become part of the premise for later reasoning.
The design choice that makes this worth reading is that PHRBench scores the trajectory, not just the final answer. Most hallucination work collapses everything into “right or wrong at the end.” PHRBench instead labels how a model handles the bad premise along the way, across three behaviors:
- Hallucination Compliance: the model accepts the false premise and runs with it.
- Hallucination Avoidance: the model sidesteps or ignores the false premise.
- Heuristic Correction: the model actively pushes back and tries to fix the premise.
Then it defines an “insightful trajectory” as the full success case: the model corrects the bad premise and reaches the correct answer. Correcting but still ending up wrong does not count. Getting lucky without ever challenging the premise does not count either. That separation matters, because final-answer accuracy alone hides whether a model reasoned its way out or just stumbled into the right place.
The scope: four domains, 18 large language models, 4820 controlled instances. That is a real spread, not a cherry-picked demo.
How often do models actually recover?
The headline finding: successful recovery is relatively rare. Across those 4820 cases, models mostly did not talk themselves out of a false premise once it was in the context. The default behavior leans toward compliance, not correction.
This lines up with something most of us have seen in practice but rarely measured. If you tell a model “given that X is true” when X is false, it tends to build on X rather than stop and say “actually, X is wrong.” The model treats context as authoritative. That is usually a feature. In-context information is how we steer these things. It becomes a liability the moment the context itself is poisoned.
PHRBench also found that recovery, when it happened, was associated with more frequent belief updates along the reasoning trajectory. In plain terms: the models that got out were the ones that revised their stance multiple times mid-reasoning instead of committing early and marching forward. That is an argument for reasoning traces that genuinely reconsider, not ones that rationalize a conclusion they locked in at step one.
I want to be careful here. The paper reports an association, not a causal lever you can pull. “Models that update beliefs more tend to recover more” does not mean “force more belief updates and you will fix hallucination propagation.” But it is a signal worth paying attention to when you evaluate reasoning models.
Can you predict recovery before it happens?
This is the part with the most immediate practical edge. The authors report that properties of the hallucinated prompt itself carry substantial predictive signal for whether recovery will happen. A lightweight predictor hit an AUROC of 0.847 on that task.
Read that carefully. It means you can look at the shape of the bad premise going in and get a meaningful estimate of whether the model will manage to correct it, before you spend the full reasoning budget. 0.847 is not perfect, but for a lightweight predictor it is strong enough to be useful as a gate.
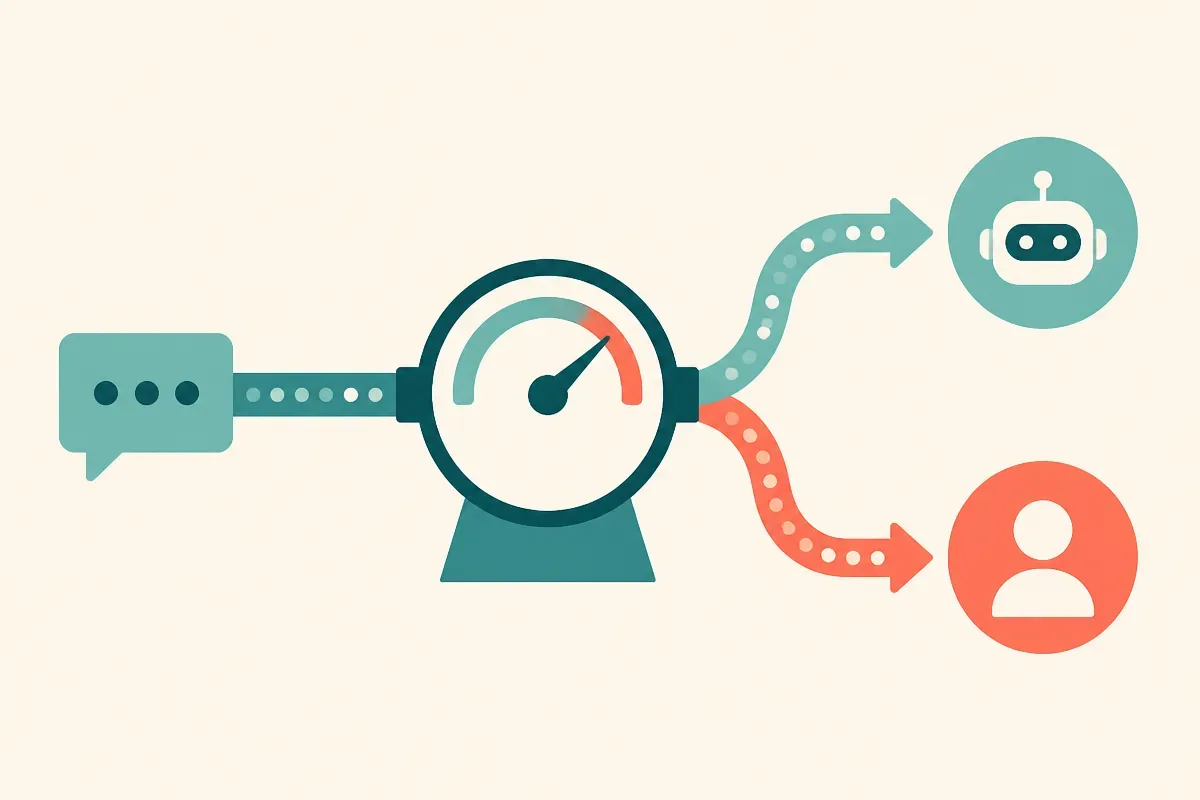
That reframes the problem from “make the model better at recovery” (hard, model-level, slow) to “detect the cases where recovery is unlikely and route around them” (cheap, system-level, available now). You do not need to fix the model. You need to know when not to trust it to fix itself.
What should a builder do with this?
The quiet lesson in PHRBench is that correction is not a reliable safety net. If your architecture assumes a later model will catch an earlier model’s mistake, you are leaning on the rarest behavior in the dataset. Build as if hallucinations propagate, because mostly they do.
A few concrete moves this points toward:
- Contain at the source. Validate retrieved facts and tool outputs before they enter the next prompt, not after the reasoning is done. Containment beats correction because correction mostly does not happen.
- Treat context as untrusted input the same way you treat user input. A false premise injected upstream behaves a lot like a quiet prompt injection: the model obeys it.
- Score trajectories, not just answers, in your own evals. PHRBench’s three-way framing (compliance, avoidance, correction) is a template you can copy. A model that gets the right answer while swallowing a false premise is not safe, it got lucky, and your eval should know the difference.
- Consider a pre-flight check on incoming context. The 0.847 predictor result suggests you can estimate recovery likelihood from the premise alone. A small classifier that flags “low recovery likelihood, escalate to human or second retrieval” is a reasonable thing to prototype.
The catch most readers will miss: this is a controlled benchmark, and controlled means the false premises were constructed and labeled deliberately. Real hallucinations in your stack are messier, lower-contrast, and often partially true, which is exactly the hardest case. So treat the recovery rates as an optimistic ceiling, not a floor. In the wild, where the bad premise is subtle and plausible, expect compliance to be even stickier than 4820 clean instances suggest. The practical takeaway does not change, it gets stronger: stop one bad fact from entering the chain, and you save yourself from every downstream step that would have faithfully built on it.