EmbeddingGemma 2 and the push toward smaller multimodal retrieval
Google DeepMind’s EmbeddingGemma 2 announcement points to a practical shift: multimodal embeddings are moving from specialist infrastructure into everyday retrieval, search, and product workflows, but builders still need to test fit, latency, quality, and operational cost before swapping models.
TL;DR: Google DeepMind’s EmbeddingGemma 2 announcement matters because lightweight multimodal embeddings make image-plus-text retrieval more practical, but model swaps still need task-level evaluation, not vibes.
What did Google DeepMind actually announce?
Google DeepMind announced “EmbeddingGemma 2: an open, lightweight multimodal embedding model.” That title carries the whole operator signal: open, lightweight, multimodal, embedding model.
Not a chatbot. Not an agent. Not a reasoning system. An embedding model.
That matters because embeddings sit under a lot of AI systems people actually ship: semantic search, RAG, recommendations, clustering, deduplication, moderation queues, product matching, support retrieval, visual search, and knowledge-base lookup. They are not flashy. They decide what the model sees next.
The “multimodal” part is the interesting piece. Text-only embeddings are already table stakes. A lightweight model that can represent more than text points toward simpler systems where product photos, screenshots, PDFs, diagrams, thumbnails, captions, and support docs can live in the same retrieval layer.
That does not mean every company should rip out its current vector stack tomorrow. It means the boundary between search and AI product UX keeps moving. If users search with words, upload images, paste screenshots, and expect all of it to connect, the embedding layer has to carry more of the load.
Hacker News picked up the announcement too, which is usually a useful signal for this category. Builders care about embedding models because they affect cost, latency, memory, self-hosting options, privacy posture, and retrieval quality. The model does not need to be glamorous to become important infrastructure.
Why are multimodal embeddings useful?
The simple version: embeddings turn different kinds of content into comparable representations. If the model is good, “red waterproof hiking jacket,” a product photo, and a catalog entry can land near each other in vector space.
That enables retrieval without forcing everything through brittle metadata or hand-written tags.
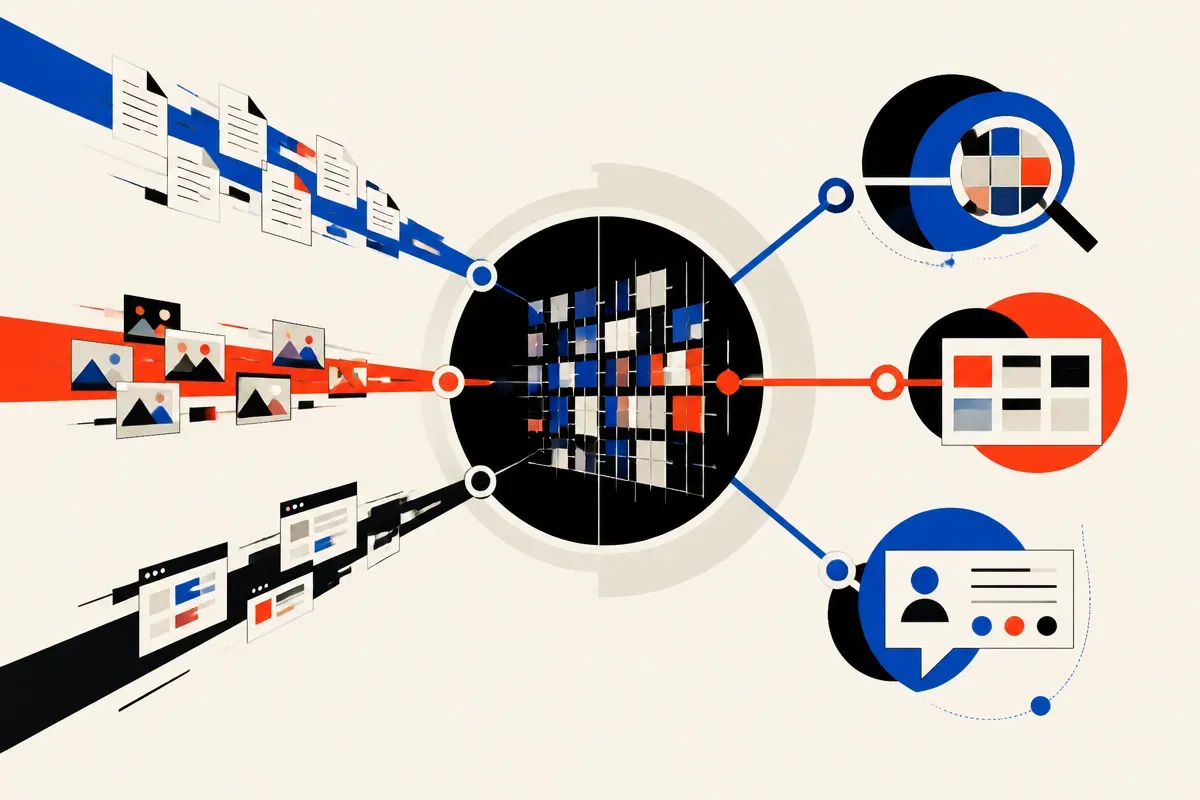
For builders, this can reduce glue work. A support bot could retrieve a help article and a screenshot walkthrough. An ecommerce search tool could match vague text queries to images. An internal knowledge assistant could connect whiteboard photos, docs, and slide exports. A media archive could find clips or images from natural language descriptions.
But “multimodal” also expands the evaluation problem. Text retrieval is already easy to demo and hard to trust. Multimodal retrieval adds more failure modes: visually similar but semantically wrong results, caption bias, poor handling of diagrams, overmatching on style, underperforming on domain-specific imagery, and silent misses when the query uses language the model does not map cleanly to the asset.
This is where I get skeptical of launch-day excitement. Embedding quality is local. A model can look strong in a general benchmark and still miss on your catalog, your documents, your screenshots, your customer language.
What should builders test before switching?
The first test is not “is it better?” The first test is “better for what?”
Pick 50 to 200 real retrieval tasks. Use actual queries from logs if you have them. Include easy cases, weird phrasing, partial terms, screenshots, duplicate-looking images, and the boring internal vocabulary your users really type. Then compare your current embedding model against EmbeddingGemma 2 on recall, ranking, latency, index size, and failure patterns.
Do not only inspect top-1 results. Retrieval systems often fail in the top 5 or top 10, where the assistant later grabs the wrong context and produces a confident answer. If you are using RAG, run end-to-end answer tests too. Better nearest neighbors do not always produce better answers.
Also check operational fit. “Lightweight” is promising, but the only numbers that matter are yours: hardware, batch size, indexing time, query volume, memory, deployment path, and whether you need local control for privacy or cost reasons. Open models can be a big win when teams want repeatable infrastructure, fewer vendor constraints, or offline processing. They still create maintenance work.
My practical move: test EmbeddingGemma 2 as a candidate retrieval layer for one multimodal workflow, not as a platform-wide migration. Start with a narrow collection where text-plus-image search would clearly help, build a small eval set, compare against your current model, and inspect failures by hand. The catch most readers miss is that embeddings are product behavior, not plumbing. Change the embedding model and you change what your AI system notices, ignores, and gets wrong.