Pivot-SD trains the denoising choices that steer diffusion LMs
Pivot-SD reframes post-training for masked diffusion language models by finding the few denoising commitments that shrink uncertainty, then rewarding or discouraging those commitments instead of training every token equally.
TL;DR: Pivot-SD is interesting because it treats masked diffusion language models as their own kind of system, not as autoregressive models with a different decoding wrapper.
What problem is Pivot-SD actually solving?
The primary source here is “Pivot-SD: Efficient Self-Distillation for Masked Diffusion Language Models”, listed on arXiv under cs.CL and cs.LG. The claim is narrow, but useful: masked diffusion language models have a different post-training problem than standard next-token models.
Autoregressive models commit left to right. Every token conditions the next one. Masked diffusion language models work differently. They start with masked positions and iteratively denoise them, often making many commitments in parallel or semi-parallel. That makes them attractive for speed and for certain reasoning setups, but it creates a weird credit-assignment issue.
Not every filled-in token matters equally.
Pivot-SD argues that a small number of “pivot” commitments can collapse uncertainty over many remaining masked positions. Once those commitments are made, the rest of the answer becomes much more constrained. If the pivot is good, the model is now on a better path. If it is bad, the model may still produce fluent text, but the answer is already bent in the wrong direction.
That is the core insight. Do not train on everything. Train on the moments that steer the trajectory.
How does Pivot-SD train those pivots?
Pivot-SD is an offline self-distillation method. It does not simply fine-tune on final answers. It also does not assign one broad reward to a whole denoising step.
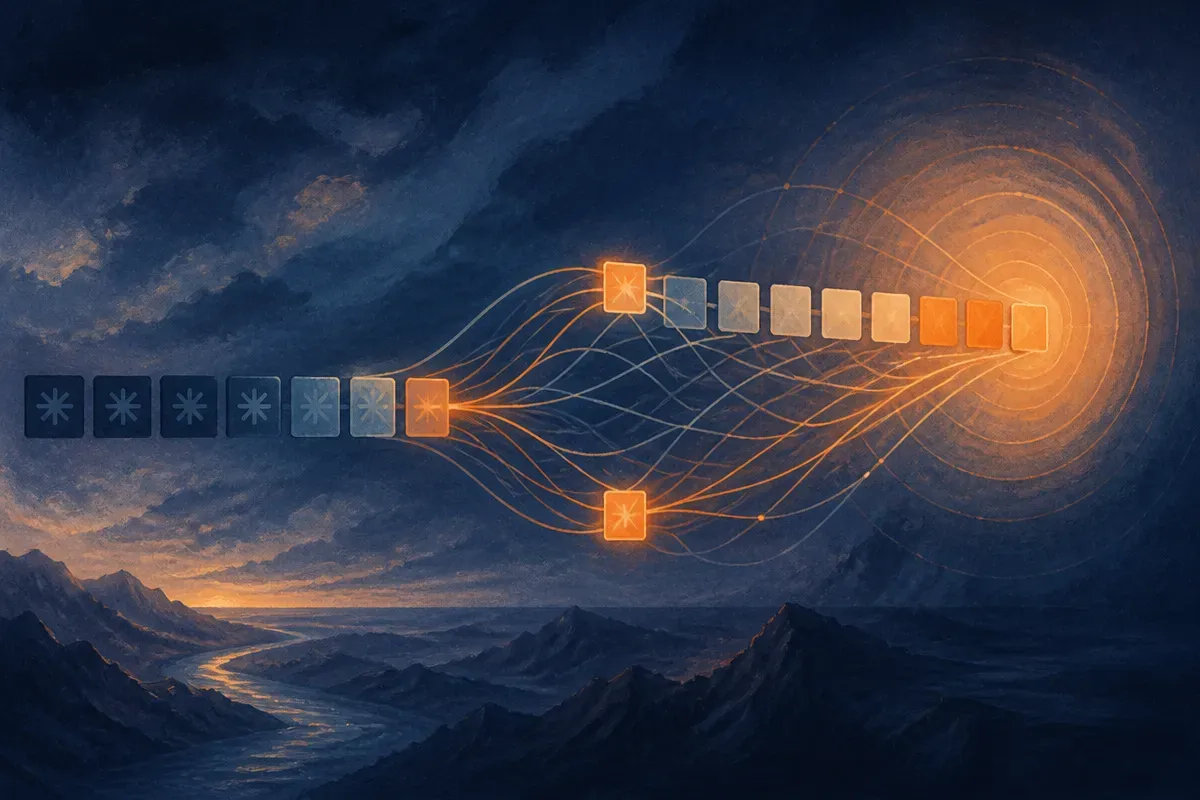
Instead, Pivot-SD selects pivots using an information-gain metric. In plain English: it looks for commitments that sharply reduce uncertainty over the remaining masked positions. Those are the decisions worth teaching.
Then it treats successful and failed trajectories differently. For pivots from successful trajectories, Pivot-SD uses cross-entropy training, pushing the model toward those commitments. For pivots from failed trajectories, it uses targeted unlikelihood, discouraging those specific bad commitments. Importantly, it leaves the rest of the failed trajectory alone.
That last part matters. A failed solution can contain many neutral or even useful tokens. Penalizing the whole thing is blunt. Pivot-SD tries to punish only the decision that sent the model off course.
The efficiency claim is also the part that will catch builders’ attention. The paper reports improvements to LLaDA-8B-Instruct using only 200 questions and four rollouts each, beating full-sequence SFT and budget-matched diffusion RL baselines across math and code benchmarks.
Good result. Also, keep the frame tight. The abstract does not give the exact benchmark list or effect sizes here, so I would not treat this as proof that diffusion language models are broadly better than autoregressive models. It is evidence that post-training recipes for diffusion LMs should not be copied blindly from the autoregressive world.
Why should builders care if they are not training diffusion models?
Most teams are not training masked diffusion LMs today. They are calling hosted autoregressive models, wiring agents, and fighting reliability issues at the product layer.
Still, Pivot-SD points at a pattern that travels well: find the decisions that determine the rest of the run.
In agent workflows, that might be the first tool choice. In code generation, it might be the initial file map or architecture choice. In retrieval, it might be the query rewrite. In long-form generation, it might be the outline. Once those early commitments land, the model can look smart while polishing a bad path.
The useful question is not “was the final answer right?” It is “which commitment made the final answer likely?”
That is a better eval shape. Log intermediate states. Identify the few decisions that shrink the search space. Reward the good ones. Block the bad ones. Do not overcorrect the whole trace when only one turn caused the failure.
Practitioner’s take: if you are building with agents or multi-step model calls, borrow the Pivot-SD mindset before you borrow the technique. Add tracing around the steps that constrain everything downstream, then review successes and failures at that decision level. The catch most readers miss is that better training data is not always more complete training data. Sometimes it is the same run, with attention paid to the two choices that actually mattered.