Reinforcement learning weakens reasoning distillation defenses
The arXiv paper “Distillation Defenses Easily Break After Reinforcement Learning” argues that many defenses against model copying are tested against the wrong attacker, because post-distillation reinforcement learning can recover much of the reasoning capability those defenses appeared to block.
TL;DR: If a distillation defense only works before the attacker runs reinforcement learning, it is probably not a real defense against reasoning-model copying.
What breaks after distillation?
The primary source here is the arXiv cs.AI and cs.LG paper “Distillation Defenses Easily Break After Reinforcement Learning.” Its core claim is simple and uncomfortable: many defenses against reasoning distillation are evaluated too early.
The usual test is: attacker collects outputs or reasoning traces from a strong closed model, trains a weaker model on them, then researchers measure whether a defense reduced the copied capability. The paper argues that this skips the next obvious step. A capable attacker does not stop after supervised distillation. They keep training. Specifically, they run reinforcement learning after distillation.
That changes the threat model.
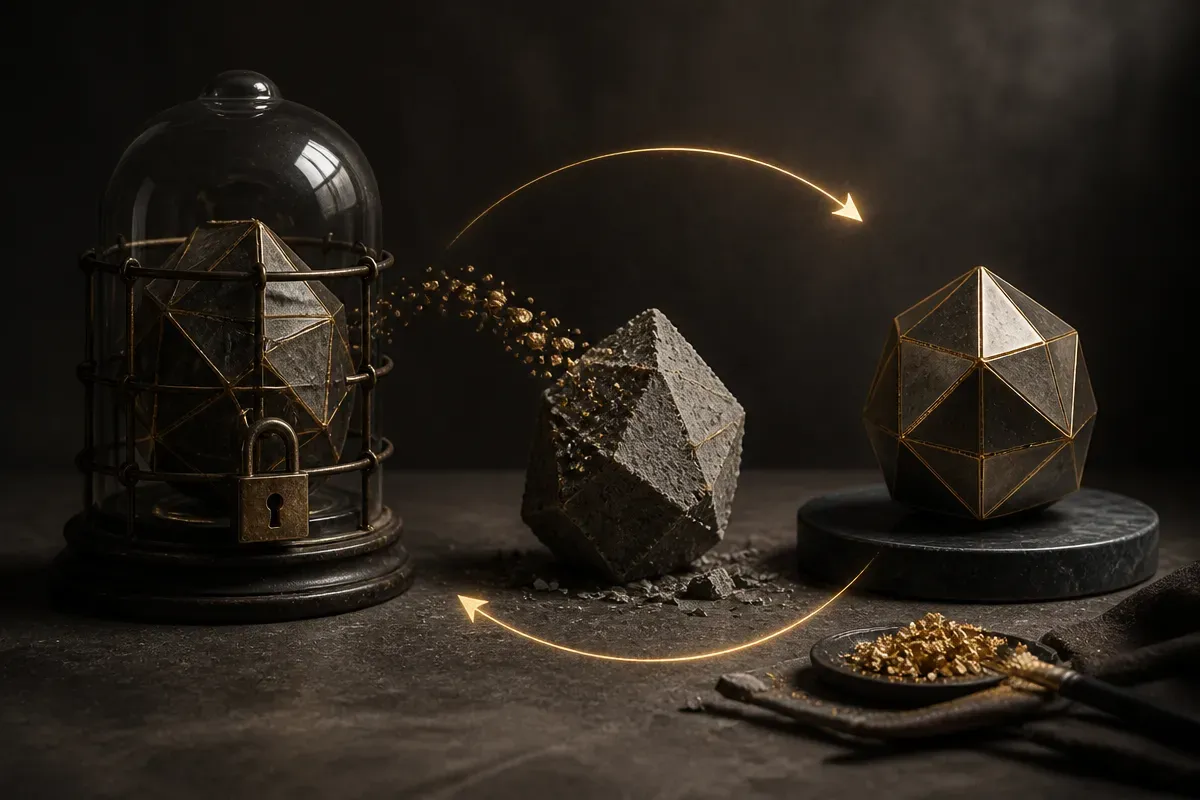
A defense can look effective immediately after the copy step because the stolen model is noisy, partial, or poorly shaped. But reinforcement learning can turn that rough imitation into a much better reasoner. The paper says this lowers the bar for a useful attack. Attackers may not need full hidden reasoning traces if approximate traces, outputs, or other API-obtainable data give them enough structure to start from.
This is the part operators should pay attention to. The scary word is not “distillation.” That has been around for years. The scary part is compounding. A little leaked reasoning signal, scaled across enough examples, then cleaned up by RL, may be enough to move a smaller model meaningfully closer to the closed model’s behavior.
Why does reinforcement learning change the security story?
Reinforcement learning is not magic. It does not make missing information appear from nowhere. But it can optimize from weak signals when the starting point is good enough.
That is why the paper’s framing matters. Some defenses focus on hiding or degrading explicit reasoning traces. The assumption is that if the attacker cannot see the clean chain of thought, the copied model will not learn the reasoning skill well. “Distillation Defenses Easily Break After Reinforcement Learning” argues that this assumption is too narrow. If the defense still leaks enough information to reconstruct approximate reasoning traces, the attacker can use RL to repair or amplify the copied behavior.
This points to a deeper issue with model security evals. A one-stage attack evaluation is not enough. You need to ask what the attacker can do after the obvious first move. Can they filter examples? Can they generate more attempts? Can they reward correct final answers? Can they tune against benchmark-style tasks? Can they combine weak traces with outcome feedback?
The paper’s claim is not that every closed model can be perfectly cloned with trivial effort. It is narrower, and more useful: defenses that look good under an immediate post-distillation eval may fail under a more realistic training pipeline.
What defenses still seem plausible?
The paper points toward batch-level distillation defenses as potentially stronger. That matters because the weak spot is not just any single response. It is the pattern across many responses.
If an attacker can query enough prompts and collect enough reasoning-shaped signal, they can train on the batch. So a better defense may need to detect or limit extraction behavior across many calls, not only sanitize one output at a time. That could mean monitoring query distributions, rate patterns, repeated task families, or suspicious large-scale harvesting.
There is a product tension here. Developers want transparent, useful reasoning. Users want models that explain themselves. Labs want to protect expensive training work. Those goals conflict. If the model exposes rich reasoning, it may teach downstream models. If it hides too much, it may become less useful and less debuggable.
My read: the practical defense will not be one trick. It will be layered. Less reusable reasoning leakage where possible. Better abuse detection across sessions. Stronger terms and enforcement for bulk extraction. Evals that include post-distillation RL, not just first-pass copying. And some acceptance that capability diffusion is hard to stop once models are accessible through APIs.
For builders, the takeaway is to update your eval plan. If you are protecting a model, do not test only whether a student model learns from your outputs. Test whether it improves after another training stage with reinforcement learning or outcome feedback. If you are building on closed-model APIs, assume labs will get stricter about bulk querying and reasoning exposure. The catch most readers miss: the useful security unit is not a single answer, it is the training value of thousands of answers together.