When Documentation Doesn't Help Coding Agents: A Negative Result Worth Reading
A new arXiv paper builds a benchmark and an optimizer to test whether natural-language docs help coding agents fix real issues, then reports that they don't when the source code is already present. Here's what that means for how you build agent context.
TL;DR: When a coding agent can already see the source code, feeding it extra natural-language documentation, whether hand-written, optimized, or retrieved, does not help it resolve real repository issues, according to a new arXiv paper that built the tools to prove its own hypothesis wrong.
The paper is “Compact Documentation for Coding Agents: A Benchmark, an Optimizer, and Why It Does Not Transfer,” posted to arXiv under both cs.AI and cs.CL. It is the rare research artifact that sets out to show something useful and ends up publishing the opposite. That honesty is the whole point, and it happens to be more actionable than most positive results I read.
What did the researchers actually test?
The setup is clean. The team wanted to know if giving a coding agent good documentation makes it better at fixing bugs and closing issues in real repositories. To measure “good documentation” without hand-waving, they built a roundtrip benchmark: take a piece of code, write a natural-language description of it, then regenerate code from that description and check whether the regenerated code passes the original tests. If it passes, the description captured what mattered. If it fails, the description left something out.
That framing produced their first real finding, and it is a good one: completeness, not length, drives a description’s fidelity. A short description that names every behavior the tests care about beats a long one that reads well but omits an edge case. This matches what anyone who has written docs already suspects, but now there is a measurable signal behind it.
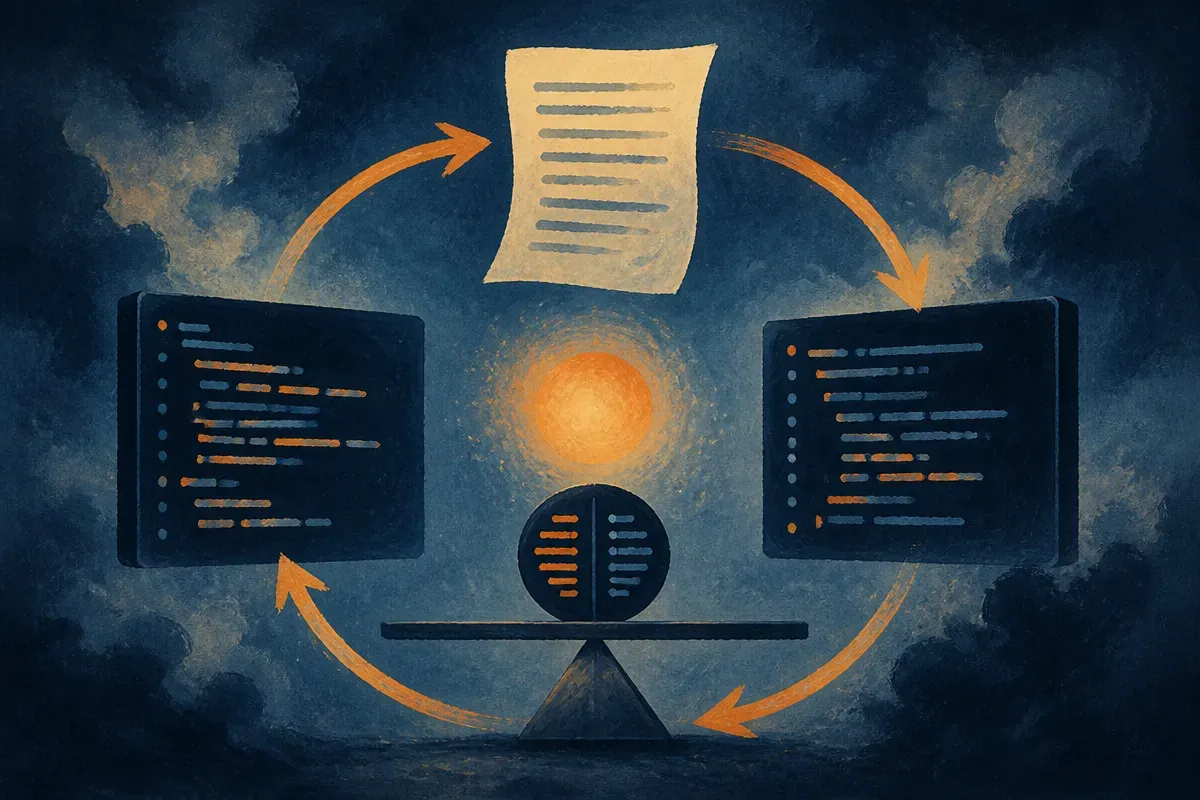
Then they used that benchmark as an optimization target. They searched for a description-writing prompt that would reliably produce high-fidelity descriptions, and they found one that reached full fidelity and generalized to files it had never seen. So at this stage the story looks like a clean win: a benchmark that scores docs, and an optimizer that writes docs good enough to pass it.
Why doesn’t better documentation transfer to real issues?
Here is the turn. The optimized documentation is genuinely good by the roundtrip measure. But the actual question was never “can we write good docs.” It was “does good documentation help an agent resolve real issues.” So they ran that test across two model families and ten repositories.
It did not help.
When the source code is present in the agent’s context, neither the static compact documentation they optimized nor retrieved context beat just handing the agent the issue by itself. The docs added nothing measurable on top of the code the agent could already read.
The detail that makes this credible is the positive control. A negative result is only worth trusting if you can show your measurement is capable of detecting a real improvement. The team confirmed exactly that: their evaluation could catch a genuine gain when one existed. So the flat result is not a broken test. It is a real ceiling. The documentation was good, the measurement was sensitive, and the agent still did not benefit.
The intuition, once you sit with it, is almost obvious. If the source is already in context, the documentation is a lossy compression of information the agent can read directly. The map is redundant when you are standing on the territory. Docs earn their keep when the territory is too large to fit, or absent entirely, not when it is sitting right there.
What does this change for how I build agent context?
I have watched a lot of teams pour effort into generating repo-level documentation, architecture summaries, and “context packs” to feed their coding agents, on the assumption that more curated context is strictly better. This paper is a direct challenge to that reflex, at least for the case where the relevant source is retrievable.
The practical reframing: stop treating documentation as a universal accelerant and start treating it as a substitute for missing source. The paper explicitly characterizes the boundary at which documentation helps, and the boundary is about presence. If your agent can already pull the relevant files, adding a natural-language layer on top is likely wasted tokens and wasted latency. If your agent cannot reach the source, because the codebase is enormous, gated, spread across services, or lives in a system the agent does not have tools to read, then a faithful compact description starts to matter, because now it is the only signal available.
One honest caveat before anyone over-generalizes. This is a negative result on a specific task shape: resolving repository issues where the source is present, across two model families and ten repos. It is not a claim that documentation is useless everywhere. Docs still serve humans, still help onboarding, still matter for cross-team knowledge. And retrieval-heavy workflows where the raw source genuinely does not fit in context were not the case that failed here. The finding is narrow and it is stated narrowly, which is exactly why I trust it more than a broad “docs boost agents by X percent” claim would.
The other quietly valuable thing the paper ships is the roundtrip benchmark itself. Even if you never build compact docs, “regenerate the code from the description and see if it passes the tests” is a reusable way to score any generated summary of a system. That completeness-over-length result is a small piece of prompt guidance you can apply tomorrow: when you do need a description, optimize it for covering every tested behavior, not for reading nicely.
Practitioner’s take: before you build a documentation pipeline for your coding agent, run the cheap test this paper implies. Give the agent the issue plus source alone, then give it the issue plus source plus your docs, and compare pass rates on your own repos with your own tests. If the docs don’t move the number, you just saved yourself a maintenance burden and a pile of tokens. Spend that effort instead on retrieval: making sure the agent can actually reach the right source files, because that is where the paper says the real leverage lives. The catch most people miss is the positive control. If you skip it, a flat result tells you nothing, because you can’t tell whether your docs failed or your eval is blind. Build the control first, then trust the answer.