When a model’s rejection reason changes its next choice
A close read of the arXiv paper “Does a model's stated reason for rejecting a candidate do any work?”, where the useful signal is real, but weaker and messier than a faithful-explanation story would suggest.
TL;DR: Model explanations are not pure decoration, but they are also not clean causal accounts, so treat them as testable clues, not ground truth.
Do stated reasons actually move the model?
The primary source here is the arXiv paper “Does a model’s stated reason for rejecting a candidate do any work?”, listed under cs.CL and cs.LG. The setup is nicely concrete. A language model chooses between candidates and explains why it rejected one. Often the stated reason is a missing fact in that candidate’s profile, like no director or no date of death.
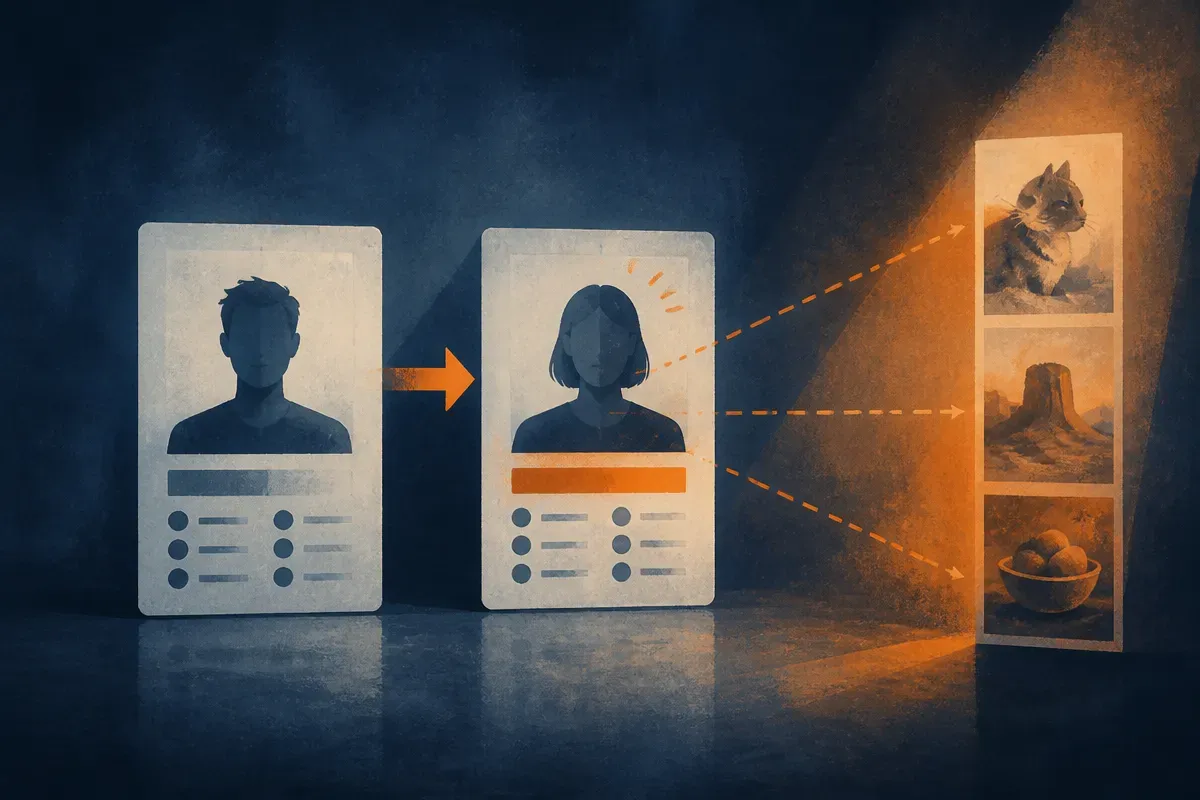
That creates a testable claim. If the model says it rejected a candidate because a fact was missing, add a real sentence containing that fact to that exact candidate profile, then ask again under greedy decoding. If the answer changes more than it does under controls, the stated reason may be doing some work.
In the largest of three runs, across six open models on 2WikiMultihopQA, adding the named missing fact to the named rival moved the model’s choice more than adding a length-matched irrelevant sentence to the same profile. The reported odds ratio was 3.57, with a 95% interval of 1.54 to 8.26, Holm p=0.0210. The effect also survived dropping any single model.
That is not nothing. It argues against the laziest take, which is that model explanations are always post-hoc confetti.
But the paper is more interesting because it does not stop there.
What did the controls catch?
The cleaner causal claim was supposed to be: if the model names a missing fact in a rejected option, adding that same fact to that option should matter more than adding it somewhere else. That contrast did not clear correction. The reported Holm p value was 0.2428.
The strongest result had no content claim at all. The same irrelevant sentence moved the choice more when inserted into the named rival than when inserted into a third option the model had not mentioned. That result was much stronger, Holm p=0.0008.
That matters. It means placement, attention, candidate salience, or some other non-semantic feature may be doing a lot of the work. The model may be saying “this candidate lacks X,” and when you touch that candidate’s profile, the model reconsiders it. Sometimes the content matters. Sometimes the mere intervention at the named location matters.
The paper also reports that repair and control examples differed in co-candidate mentions, relation template, and fluency. Post-hoc matching on co-candidate mentions and relation template preserved the direction of the content effects. Matching on fluency weakened one. That is the right level of caution: the content effect is bounded, not nailed shut.
One more sharp edge: a forced single-token probability read disagreed in direction with the free-text choice on the same contrast, and three proposed explanations for that disagreement were not supported. So even the measurement format changes what you think you are seeing.
Why does this matter for evals?
The most operator-relevant result may be the boring one. Every measurement was a string rule, and the paper reports that validation caught eight defects. The biggest defect was a choice-parsing rule that returned the option a model had just rejected in 17.1% of adjudicable responses. If left unfixed, it would have reported six surviving contrasts instead of four.
That is the receipt I care about. Not because the model got confused. Because the eval got confused.
If your workflow depends on “the model explained itself,” you need to separate three things: the generated rationale, the intervention that changes behavior, and the parser that turns messy text into a metric. Any one of those can fool you.
For builders, the practical move is simple: when an agent rejects an option, log the stated reason, patch the environment or context to satisfy that reason, then rerun with controls that change the same amount of text in the same place. Do not ask a judge model whether the rationale sounds good. Test whether the claimed missing fact changes the next action more than a placebo edit does. The catch most readers miss: even a positive result does not prove the model was “thinking that way.” It only tells you the explanation is a useful handle on behavior under a specific intervention.