UECR-GRPO treats the teacher as evidence, not an oracle
The arXiv paper “When and Where to Trust the Teacher” proposes a cleaner way to mix verifier rewards and teacher guidance in small reasoning models, with modest benchmark gains and a useful lesson for anyone training models on verifiable tasks.
TL;DR: Teacher models help small reasoning models most when their token-level advice is treated as uncertain evidence, not truth, and folded into RL before reward normalization.
What problem is UECR-GRPO trying to fix?
The primary source here is the arXiv paper “When and Where to Trust the Teacher: Unifying On-Policy Distillation and GRPO through Entropy-Calibrated Credit Assignment.” It tackles a very specific training problem in mathematical reasoning: final-answer rewards are clean but sparse, while teacher feedback is dense but not always right.
That tradeoff matters. Reinforcement learning with verifiable rewards, or RLVR, can tell the student model whether it got the final math answer correct. It does not explain which tokens helped or hurt. On-policy distillation, or OPD, can give token-level pressure from a stronger teacher model on student-generated outputs. But the teacher’s preferred wording or path does not always map to correctness.
The paper’s core point is that many hybrid methods bolt teacher guidance onto the process too late. The verifier has already shaped the group ranking, then the teacher comes in to reweight pieces. That can make teacher feedback useful, but also a little structurally awkward. Worse, token reweighting can change how much total credit a response gets, instead of only redistributing that credit across the steps.
That distinction sounds small. It is not. If a response earned a certain verifier-derived advantage, you probably do not want token shaping to quietly inflate or erase the total task credit. You want it to answer a narrower question: given this amount of credit, which parts of the path should receive more or less of it?
Where does the teacher enter the training loop?
The paper introduces Unified Entropy-Calibrated Credit Redistribution for GRPO, or UECR-GRPO. The name is clunky. The idea is cleaner.
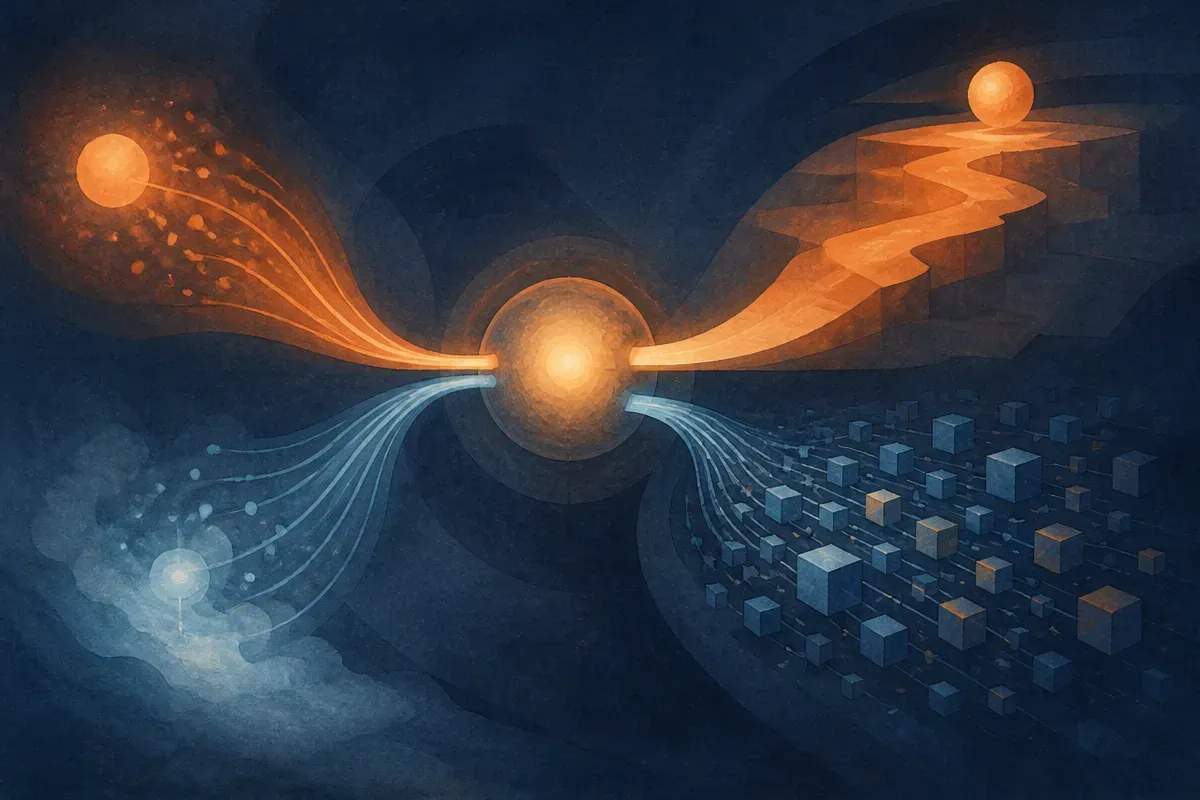
First, Path-Utility Unification combines the verifier reward and a teacher-to-anchor path log-ratio inside one KL-regularized objective. In the on-policy version, the teacher score is length-normalized, then combined with verifier reward before group normalization and PPO clipping. That timing is the point. Teacher evidence can affect response ranking, not just decorate a ranking already set by the verifier.
Second, Entropy-Calibrated Redistribution handles token-level credit. It looks at the signed gap between the teacher and the old policy for each token. If the teacher strongly prefers something the old policy did not, that token can receive more of the verifier-derived credit. If the teacher is uncertain, full-vocabulary teacher entropy attenuates the signal.
That last part is important. The teacher is not treated as a magic labeler. Its confidence changes how much say it gets.
UECR-GRPO also uses a response-wise zero-sum projection to preserve the total task credit and token-wise sign before clipping. Plain English: the method moves credit around inside a response without changing the response’s total verifier-derived credit. That is the paper’s most operator-relevant idea.
How much did it help?
The reported gains are real, but not giant. Across five mathematical reasoning benchmarks, “When and Where to Trust the Teacher” reports average Avg@12 accuracies of 17.21% for Qwen3-1.7B and 65.09% for Qwen3-4B. Those beat the strongest baseline at each scale by 0.89 and 0.56 percentage points.
That is not a “models learn reasoning now” result. It is a training-mechanics result. Small improvements in math benchmarks can still matter when they come from a principled credit assignment change, especially if the method is compatible with existing GRPO-style workflows. But the paper’s own numbers argue against overclaiming. This is an incremental gain, not a regime change.
The more interesting lesson is where the gain comes from. UECR-GRPO does not simply ask a bigger model to supervise a smaller one and hope for the best. It asks when the teacher should affect response-level ranking, when it should only redistribute token-level credit, and when its uncertainty should reduce its influence. That is closer to how I would want production training systems to behave.
For practitioners, the takeaway is not “copy UECR-GRPO tomorrow.” It is to audit where teacher signals enter your training loop. If a verifier gives sparse truth and a teacher gives dense preference, do not mix them casually. Try combining teacher evidence before normalization when it should affect candidate ranking, then use confidence-aware token redistribution when it should shape steps. The catch most teams miss: teacher feedback is only useful if the training objective preserves the task credit you actually trust.