Fact-checking agents need receipts, not vibes
Marketing AI Institute is right that AI makes content production easier and quality control harder. The useful move is not asking an agent to bless a draft, but splitting fact-checking, copy editing, and source review into separate jobs with evidence attached.
TL;DR: Use AI agents as structured reviewers for claims, style, and source gaps, not as final authorities on whether your content is true.
What should a content-checking agent actually do?
Marketing AI Institute’s “How to Use AI Agents to Fact-Check and Copy Edit Your Content” frames the right problem: AI lets marketers publish more, faster, but the checking layer does not automatically scale with production. That is where credibility gets expensive.
The trap is treating “fact-check this” as one job. It is not one job. It is several jobs hiding under one prompt.
A useful content agent should first extract claims. Not opinions. Claims. Dates, names, product capabilities, pricing, availability, statistics, legal assertions, medical statements, quotes, and anything that says a thing happened or will happen.
Then it should classify those claims by risk. A typo in a subheading is not the same as saying a product is free, a study proved something, or a regulation requires an action. Those need different review paths.
Then it should attach evidence. This is the key difference between a content assistant and a content risk system. “Looks accurate” is not an output. A link to the company announcement, documentation, transcript, filing, paper, or named reporting is an output. If the agent cannot find support, it should say that plainly.
Copy editing is a separate pass. Style, clarity, repetition, grammar, and tone are real problems. But mixing them with fact-checking creates a mushy review where the prose gets cleaner and the claims stay weak.
Where do agents help, and where do they still fail?
Agents are good at persistence across a checklist. They do not get bored by the fifteenth claim in a 2,000-word post. They can compare a draft against a style guide, flag unsupported numbers, find inconsistent spellings, and ask whether the headline promises more than the body proves.
That is useful.
But the dangerous part is confidence. A model can produce a clean, professional-sounding review that is wrong. It can miss a stale source. It can cite a page that mentions the topic but does not support the claim. It can also “correct” copy into something less precise.
So I would not let an agent be the judge. I would make it the clerk.
The agent prepares the docket. Here are the claims. Here are the links. Here are the places where the draft says more than the source supports. Here are sentences that sound like fact but read like interpretation. Here are names, dates, and numbers that need human approval.
That is a real workflow. It reduces cognitive load without pretending the machine has editorial judgment.
What workflow is worth shipping?
Start small. Run every draft through three passes before publication.
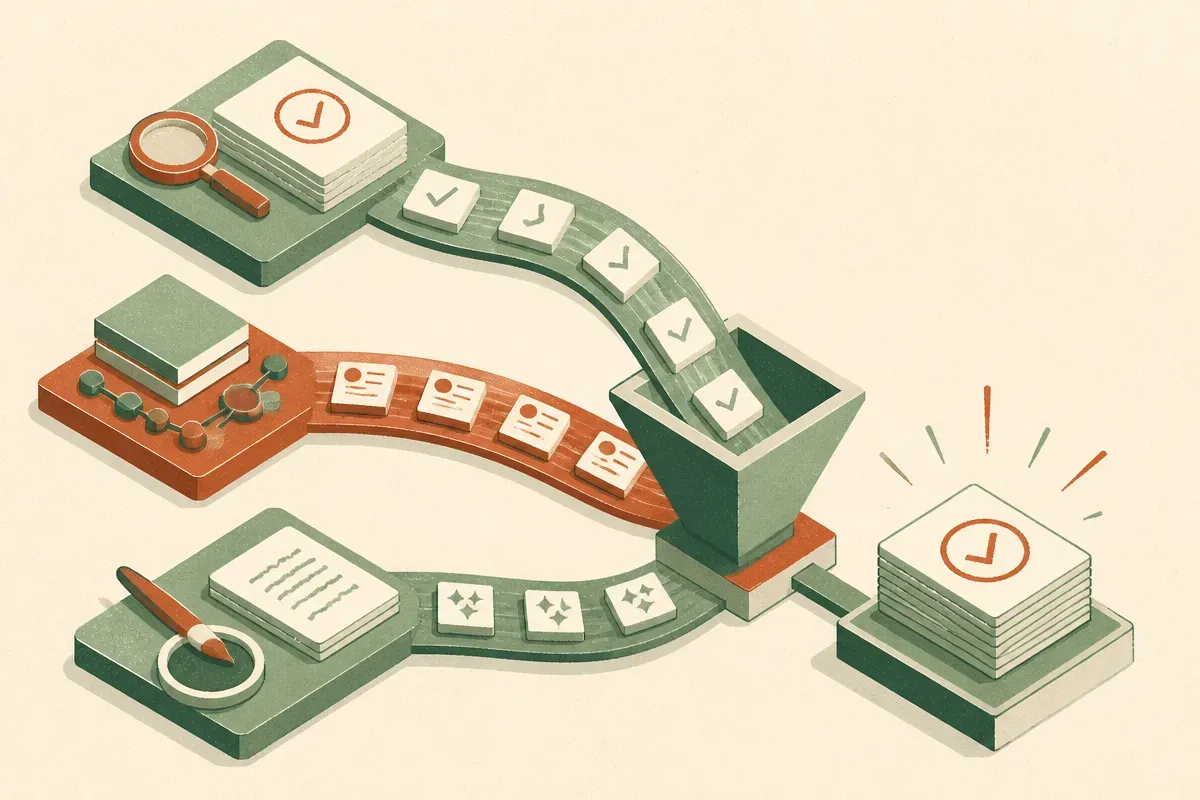
First, a claim extraction pass. The agent returns a table-like review in plain language: claim, risk level, current support, missing support, suggested fix. If there are no sources for a factual claim, the draft should not ship unchanged.
Second, a source integrity pass. The agent checks whether the cited source is primary, secondary, or weak. Company pricing should come from company docs. Academic claims should point to the paper or lab page. Reported rumors should be labeled as reported, not confirmed.
Third, a copy pass. The agent edits for clarity, house style, and unnecessary hype. This is where it can remove vague adjectives, tighten sentences, and flag claims that sound promotional.
The human editor still owns the final call. That is not a weakness in the workflow. That is the workflow.
For builders, the practical move is to create a reusable review agent with a strict output format and a “no evidence, no approval” rule. Try it on your next five posts, then compare what it catches against what your human editor catches. The catch most teams miss: the value is not faster proofreading. It is making unsupported claims visible before they become published liabilities.