Benchmarks Do Not Settle the Open-Weight Risk Debate
A LocalLLaMA thread uses a claimed Gemini 4 benchmark jump to argue open-weight models are not uniquely dangerous. The better read: benchmarks measure capability slices, while release risk depends on access, safeguards, misuse cost, and deployment context.
TL;DR: Higher benchmark scores do not prove open-weight models are safe or dangerous, they only show that capability is moving and risk arguments need better evidence than vibes.
What is actually being claimed?
The primary source is the r/LocalLLaMA post titled “With Gemini 4, bench goes up.” by /u/Intrepid_Travel_3274. The claim is blunt: companies warn that open-weight models are dangerous, but benchmark movement says otherwise.
That is a useful provocation. It is not proof.
The post gives us a common argument in the open model community: if closed frontier systems keep getting stronger, then singling out open-weight releases as the scary part feels selective. A closed model with higher scores can still be available through an API to millions of users. A weaker open model can be downloaded, modified, distilled, stripped of refusals, and deployed without logging. Those are different risk profiles.
Benchmarks do not erase that distinction. They also do not automatically validate it.
This is where the debate often gets sloppy. “Open is dangerous” is too broad. “Closed is safer” is also too broad. The real questions are narrower: What capability is being measured? Who gets access? Can safeguards be removed? How much expertise is needed to cause harm? Is the model useful for harmful workflows, or just good at test questions?
A benchmark jump can raise the temperature. It cannot answer those questions by itself.
Why benchmarks are the wrong referee
Benchmarks are useful when they are treated as instruments, not verdicts. They tell us something about coding, math, reasoning, recall, tool use, multimodal performance, or instruction following, depending on the test. They rarely tell us whether a model materially changes a malicious operator’s cost curve.
That last phrase matters. The safety question is not “does the model score high?” It is “does the model make a bad thing cheaper, faster, more scalable, or more reliable?”
An open-weight model that is mediocre on general chat benchmarks could still be valuable for spam, phishing variants, automated scraping, or low-cost content farms if it is cheap to run and easy to tune. A closed frontier model with better reasoning may be safer for some use cases if access controls, monitoring, and rate limits hold. Or it may be riskier if its capabilities are widely exposed through weak product gating.
Neither answer comes from a leaderboard.
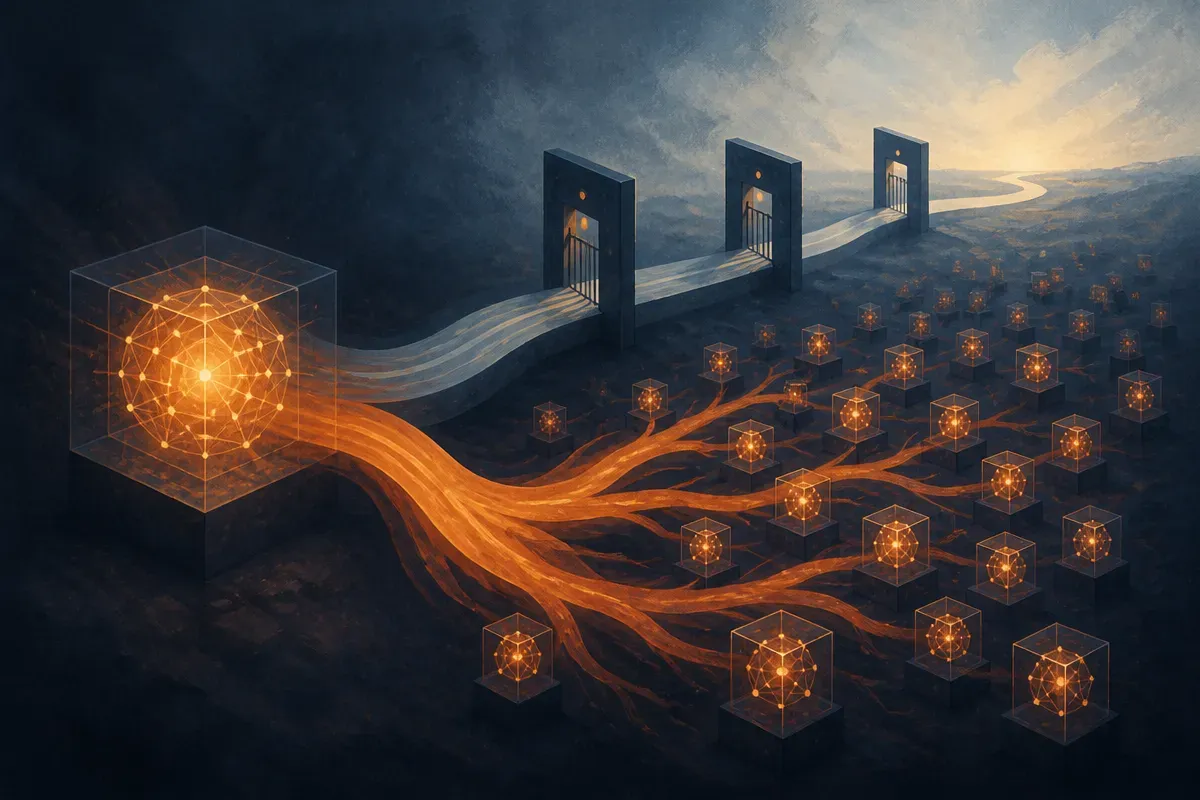
The better evaluation stack would separate at least three layers. Capability, what the model can do under ideal conditions. Control, what the provider or deployer can restrict. Abuse economics, how hard it is to turn the model into a repeatable harmful workflow.
Most public arguments collapse those into one number. That is why they feel satisfying and still miss the operational point.
What should builders take from this?
For builders, the practical lesson is not “ignore safety claims” or “trust open weights by default.” It is to evaluate the model in the workflow you actually plan to ship.
If you are choosing between an API model and an open-weight model, benchmark scores are just the first filter. Next, test latency, cost, refusal behavior, data handling, logging needs, fine-tuning options, and failure modes. If the model touches customer data, the privacy and governance tradeoffs may matter more than a leaderboard delta. If the model writes code, run it through your own repo tasks. If it powers search or support, test grounded answers and hallucination recovery. If it can take actions, evaluate tool-call mistakes and prompt-injection resistance.
I also would not treat Reddit consensus as evidence, even when I agree with the instinct behind it. r/LocalLLaMA is often early to the right questions, especially around local inference and open weights. But this specific claim is thin without the benchmark table, test names, model access details, and first-party confirmation from Google or the benchmark maintainers.
My practitioner’s take: use benchmark movement as a smoke alarm, not a building inspection. When a new model looks better, run a small internal eval against your real jobs, then add an abuse-case eval that asks how the same model could be misused in your product context. The catch most readers miss is that “open” and “closed” are not safety labels. They are distribution choices, and distribution changes what can go wrong.