LangChain 1.4.2 fixes a small but real agent reliability problem
LangChain 1.4.2 is a narrow release, but the HITL tool-call edit fix points at a bigger issue for agent builders: human review only helps if the system preserves the model’s original intent cleanly.
TL;DR: LangChain 1.4.2 is a small release, but its fix for preserving model-generated tool calls during human-in-the-loop edits matters because agent reliability often breaks at the handoff, not in the model.
Why does a tiny LangChain patch matter?
The primary source here is the GitHub release entry titled “langchain-ai/langchain langchain==1.4.2”. It lists one core change since 1.4.1: “fix(langchain): preserve model-generated tool calls in HITL tool call edits and add notice to ToolMessage (#40463)”, included in release PR #40621.
That is not headline bait. It is not a new agent framework, a new model, or a new benchmark claim.
But it is the kind of change that matters in production.
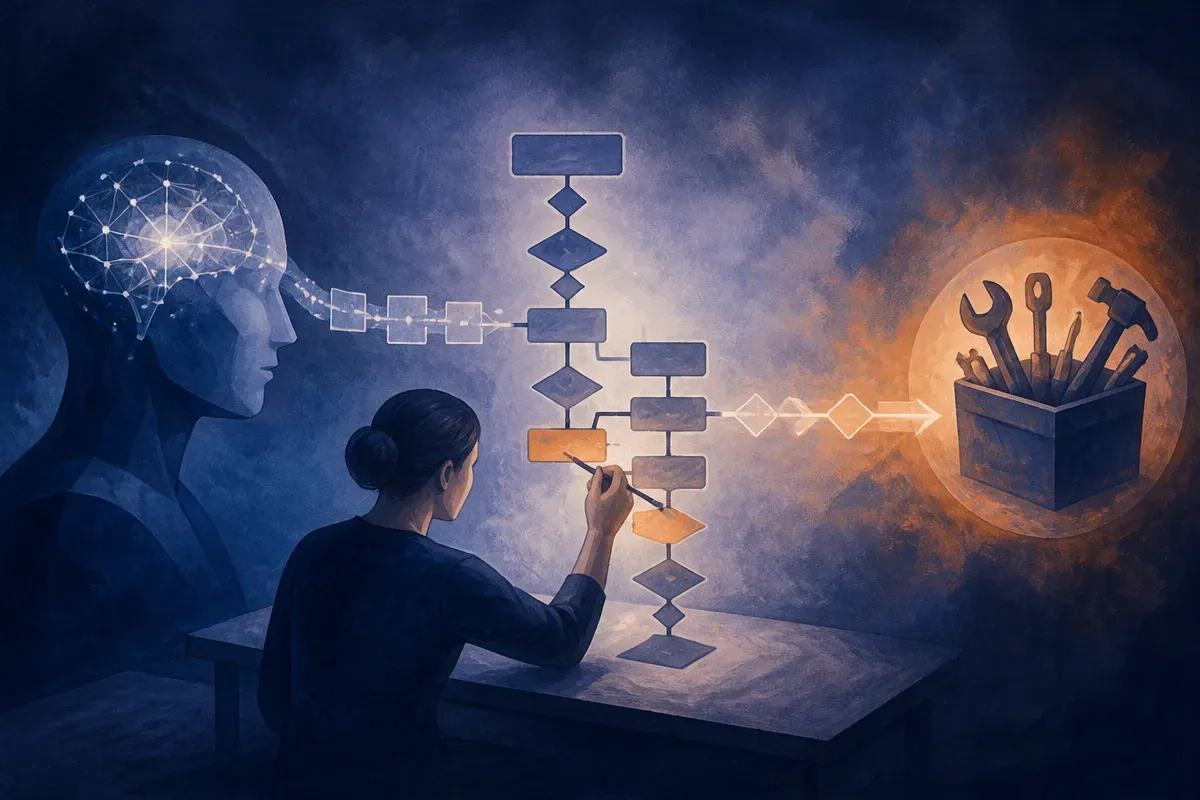
Human-in-the-loop, or HITL, is supposed to make agent systems safer and more controllable. The model proposes an action. A human reviews it. Maybe the human edits the tool call before execution. The system should keep enough of the original tool-call structure to know what the model actually intended, what the human changed, and what finally ran.
If that chain gets muddied, the audit trail gets weaker. Debugging gets harder. Evaluation gets noisy. A failed tool execution can start looking like model failure, when the real issue was an edit path that lost or rewrote part of the original call.
That is the boring part of agents that most demos skip. The handoff layer.
What does this say about where agents are actually fragile?
A lot of agent talk still centers on autonomy. More tools. More steps. More planning. Less supervision.
In practice, many useful agents are supervised systems. They draft support replies, prepare refunds, queue database actions, file tickets, update records, or call internal APIs. A person approves the risky parts.
That design only works if the framework treats tool calls as durable objects, not disposable text blobs.
LangChain’s 1.4.2 fix is narrow, based on the release note. It does not tell us how many users hit the bug, which workflows were affected, or whether the issue created bad executions versus messy state. The release entry does not provide those details, so I would not inflate the claim.
Still, the direction is clear. Agent frameworks are moving from “can the model call a tool?” to “can the system preserve intent, review, edits, execution, and messages in a way operators can trust?”
That is the right layer to obsess over.
A model making a bad call is one failure mode. A human correcting the call, then the system losing the model-generated tool call context, is another. The second one is more frustrating because it lives below the prompt and above the API. It is orchestration debt.
What should builders check after LangChain 1.4.2?
If you use LangChain with HITL tool-call editing, the obvious move is to read the 1.4.2 release and test the upgrade against your own review flow. Not with a happy-path demo. With the weird cases.
Have the model generate a tool call. Edit the arguments. Reject one call and approve another. Change a required field. Trigger a tool error. Then inspect the messages and logs. You want to see the original model-generated tool call, the human edit, and the final tool execution as distinct states, not a blended artifact.
Also look at whatever the added ToolMessage notice changes in your own UI or logs. The release note says LangChain added a notice to ToolMessage, but does not spell out the exact operator-facing behavior in the snippet provided. Treat that as something to verify, not assume.
The broader lesson: agent reliability is not only about better models. It is about preserving state across messy workflows. Tool calls are contracts. Human edits are interventions. Tool messages are evidence. If your system collapses those into one vague transcript, you will have a hard time knowing what happened when something breaks.
Practitioner’s Take: I would upgrade only after writing a small regression test around HITL tool-call edits. Capture the model’s original call, apply a human edit, execute the tool, then assert that your logs still show each step cleanly. The catch most teams miss is that human approval does not automatically make an agent safer. It only helps when the framework keeps the review trail intact.