Jev is a decision model, not another chatbot
Typesafe AI’s Jev points at a useful split in AI products: slow reasoning models for hard work, fast typed decision models for software loops. The launch claims are big, but the practical idea is simple and worth testing.
TL;DR: Jev is interesting because it treats AI as a fast typed decision function, not a chat interface, which could matter most inside software loops where latency and structured outputs beat prose.
What is Jev actually for?
The primary source here is Typesafe AI’s launch of JEV, where founder Diogo Almeida calls it “the first public system 1 model.” Typesafe’s claim is not that Jev is a better chatbot. It is that chat is the wrong shape for a lot of automation.
Sam Witteveen framed this well: most decisions inside software are not deep “system two” reasoning tasks. They are quick classification calls. What kind of ticket is this? Is this agent trace compliant? Which browser action should happen next? Did this output violate a rule?
Jev’s interface, as described by Witteveen, looks closer to a typed function than a conversation. You pass in state, then ask structured questions. Those questions can be choice, score, or yes/no style decisions. The model returns decisions with probabilities and confidence, rather than paragraphs of generated text.
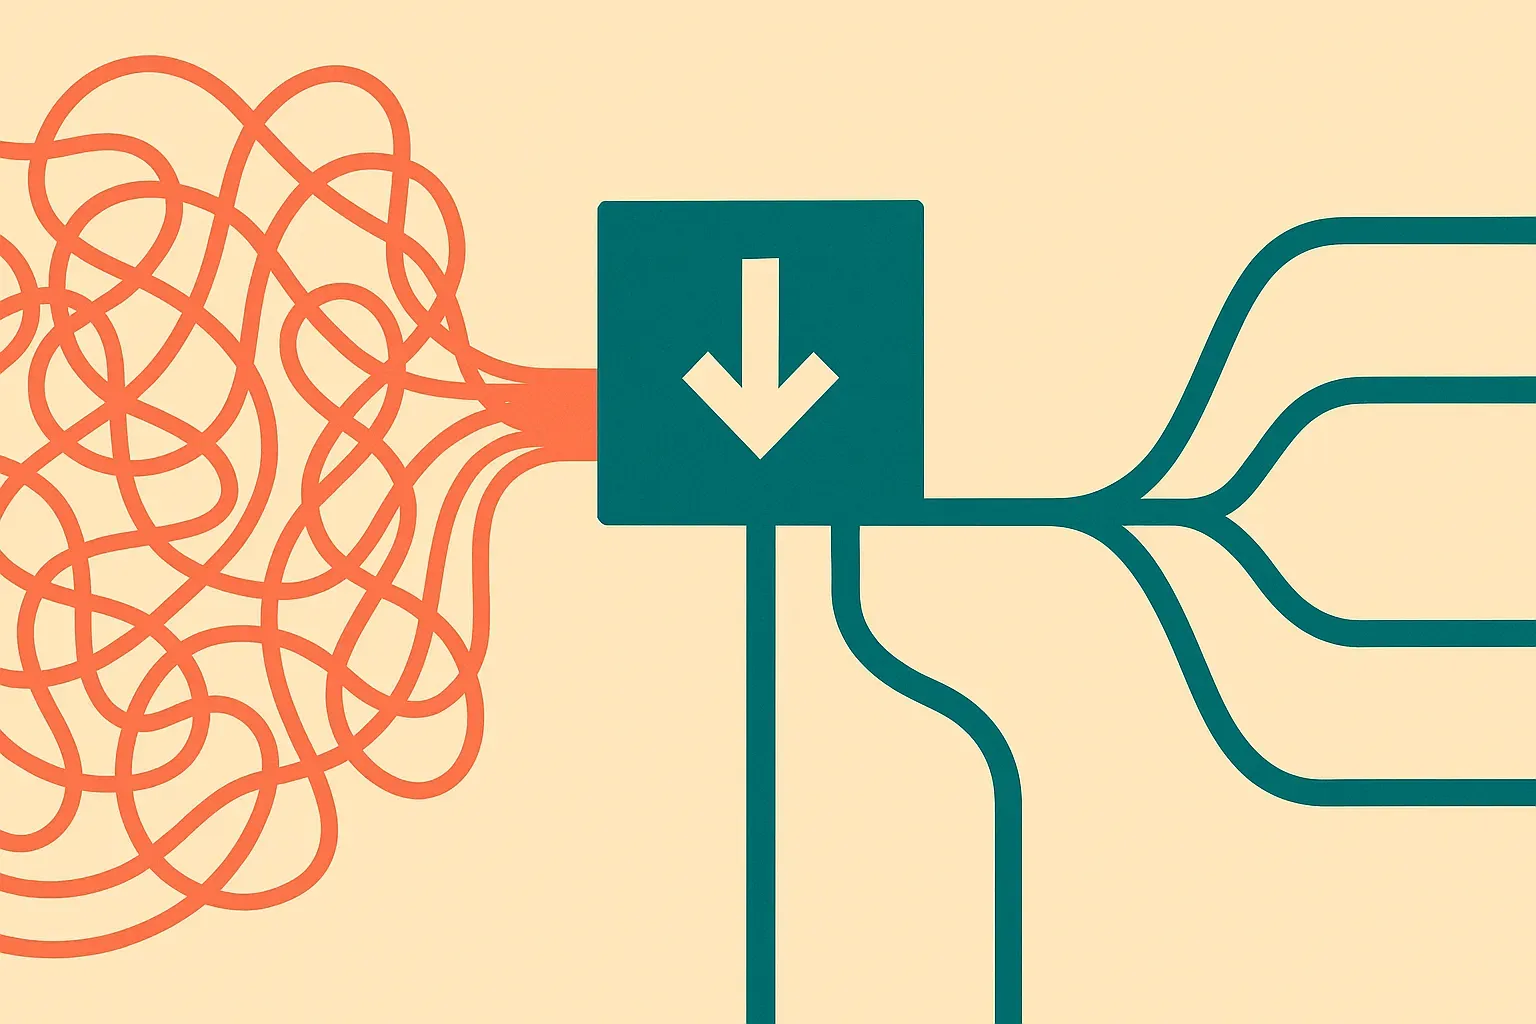
That sounds boring until you price and time it against a normal LLM. Asking a reasoning model for one label still makes it produce tokens sequentially, even if you hide most of the answer behind JSON. Jev is built around the opposite bet: parallel decisions, cheap outputs, and strict answer shapes.
Why does speed matter here?
Typesafe says Jev is up to 100 to 200 times faster and up to 400 times cheaper than traditional large language models, depending on which launch claim you quote. In the Typesafe launch clip shared by The AI Grid, Almeida says input tokens are priced at $42 per billion tokens, and output tokens are free because they are “too cheap to meter.”
Those are first-party claims, not independent measurements. But the demos point to the intended use case. Matthew Berman highlighted Jev playing Doom in real time and racing through Wikipedia link paths far faster than models like Haiku, Sonnet, and Gemini 5.6 Terra in the shown comparisons. The AI Grid pointed to early community demos in Minecraft and browser tasks.
I would not treat those clips as proof of broad model superiority. Demos are demos. But they do show why this product category matters.
Agents are often bottlenecked by tiny calls: classify the current state, choose an action, check a rule, score whether progress happened, route a message. If each call takes seconds, the whole agent feels dumb even when the underlying model is smart. A cheaper, lower-latency decision layer could let builders run many checks per step instead of one expensive judgment call.
That is the real pitch. Not AGI. Not magic. A faster control surface for automation.
Where should builders be skeptical?
The phrase “can’t hallucinate” needs care. Typesafe says Jev outputs decisions instead of words, which reduces one class of hallucination: freeform invented text. But a classifier can still be wrong. It can choose the wrong label with high confidence. It can miss edge cases. It can encode bad categories because the schema was bad.
So the right comparison is not “Jev versus all LLMs.” It is “Jev versus the small model, rules engine, embedding classifier, or frontier model call I already use for this specific decision.”
I also want independent evals. The launch material mentions benchmark performance and intelligence per dollar, but the useful tests will be boring: ticket routing accuracy, moderation recall, agent step selection, regression stability after prompt changes, and latency under real traffic. Especially under messy inputs.
There is also a product design catch. Typed decisions force you to know the shape of the decision ahead of time. That is great for production. It is less useful when the task is exploratory, ambiguous, or requires synthesis. For those, chat and reasoning models still fit.
For builders, I would try Jev as a sidecar, not a replacement. Put it on high-volume decisions where you currently waste expensive model calls: routing, policy checks, agent evals, UI state selection, lead scoring, log triage. Measure accuracy, latency, and cost against your current setup. The catch most readers miss: speed only compounds when your system is designed to make many small decisions, not when you just swap one chatbot endpoint for another.